# CANedge3 Intro and Tools
> Get started guide for the CANedge3 CAN/LIN data logger. This documentation covers introduction, device configuration, protocol-specific guidance (J1939, OBD2, CANopen etc), how to record data, data transfer, and data processing software/API tools. It is strongly recommended to also download the technical {device_name} Docs and use these in combination with this introduction material. The {device_name} Docs are also available in an AI/LLM-friendly text file version.
2026, CSS Electronics
## Pages
- [Configure your device](configure-device\index.html.md): Configure the CANedge via simple online or offline editor tools. Covers the config editor workflow, JSON schema concepts, OTA updates, and links to the firmware update guide.
- [Contents](index.html.md): Top-level table of contents for the CANedge Intro: device introduction, configuration, recording, transfer, and processing tools.
- [CANedge3 - get started](introduction\index.html.md): Quick-start overview of the CANedge data logger: workflow steps (configure, record, transfer, process), quick links to software/API tools, and where to find each section.
- [Process your CAN/LIN data](log-file-tools\index.html.md): Overview of the CANedge processing toolchain: MF4 converters, MF4 decoders + Parquet data lakes, asammdf GUI, Python/MATLAB APIs, and Grafana/Power BI dashboards.
- [Record raw data](record-data\index.html.md): How to record raw CAN/LIN data with the CANedge: preparation checklist, basic logging verification with LED indicators, and links to protocol-specific guides.
- [Transfer data](transfer-data\index.html.md): Transfer CANedge3 log files via SD card or via 3G/4G to your own S3 server. Covers SD extraction, SIM card configuration, S3 upload setup, and cellular connectivity tips.
- [Docs for AI](ai\index.html.md): Download link to the single-file plain-text CANedge documentation built for AI assistants (LLMs) - contains all CANedge Intro content in one .txt file optimised for LLM ingestion.
- [Config editor tools](configure-device\config-tools\index.html.md): Config editor reference: presentation modes, OBD/filter/encryption/bit-timing helper tools, partial config loader, schema loader, encryption key workflow, and Configuration File migration.
- [Firmware update tips](configure-device\firmware-update-guide\index.html.md): How to migrate a CANedge Configuration File when upgrading firmware (PATCH vs MAJOR/MINOR) using the config editor, CANcloud, or the canedge_manager OTA batch manager.
- [About this manual](introduction\about-manual\index.html.md): About the CANedge Intro manual: scope (getting started plus software/API tools), structure by workflow step, link to the full CANedge Docs, and admonition notation conventions.
- [Python](log-file-tools\api-tools\index.html.md): Process CANedge MF4 data in Python: MF4 decoders + Parquet data lake (recommended at scale) or python-can for raw frames and specialised integrations (J1939, CANopen, ISO-TP, UDS, XCP).
- [asammdf GUI](log-file-tools\asammdf-gui\index.html.md): asammdf GUI quick-start for CANedge MF4 logs: load raw MF4, DBC-decode CAN/LIN signals, create plots, and export to CSV/MAT/HDF5/Parquet. Windows/Linux download links included.
- [Dashboards](log-file-tools\browser-dashboards\index.html.md): Open-source browser dashboards for CANedge data: Grafana-Athena (recommended, AWS), Grafana-BigQuery (Google), Grafana-Synapse (Azure), and Power BI-Synapse stacks.
- [MATLAB](log-file-tools\matlab\index.html.md): Process CANedge MF4 data in MATLAB: use the MF4 decoders + Parquet workflow (recommended) for native Parquet support, or MATLAB's Vehicle Network Toolbox for direct MF4 loading.
- [MF4 converters](log-file-tools\mdf4-converters\index.html.md): MF4 converters: convert CANedge MF4 logs to MF4/CSV/ASC/TRC for Vector/PEAK tooling. Also handles decryption (MFE), decompression (MFC), and demuxing of routed log files.
- [MF4 decoders](log-file-tools\mdf4-decoders\index.html.md): MF4 decoders: DBC-decode CANedge MF4 logs to CSV or Parquet for analysis or data lakes. Handles decryption/decompression/demuxing and ISO-TP / J1939-TP / NMEA Fast-Packet multi-frame data.
- [Using the CANmod with your CANedge](record-data\canmod\index.html.md): Connect CANmod sensor modules to a CANedge: single CANmod via 2nd port, multiple CANmods with unique CAN IDs, and parallel CAN bus + CANmod recording configurations.
- [Log CANopen data](record-data\canopen-data\index.html.md): Log CANopen data with the CANedge: broadcast PDO logging, SDO upload request configuration for SDO data, DB9-M12 adapter cables, and converting EDS files to DBC for decoding.
- [Using the internal GNSS/IMU](record-data\internal-gnss-imu\index.html.md): Use the CANedge internal GNSS/IMU: antenna install and device orientation, CAN channel 9 DBC decoding, filtering to reduce file size, and sensor fusion for automotive accuracy.
- [Log J1939 data](record-data\j1939-data\index.html.md): Log J1939 data with the CANedge: default broadcast configuration (auto bit-rate), DB9 adapter cables for trucks/tractors/Caterpillar, recording steps, and DBC decoding tips.
- [Log LIN data](record-data\lin-data\index.html.md): Log LIN data with the CANedge as subscriber or publisher: LDF-derived bit-rate, frame lengths, checksum types and schedule tables; recording wiring, and LIN frame DBC decoding.
- [Logging troubleshooting tips](record-data\logging-troubleshooting\index.html.md): Troubleshoot CANedge logging issues: verify pinout/wiring/power/termination, check LED behaviour, default-config reset, manual bit-rate test, and error-frame review via asammdf.
- [Log NMEA 2000 data](record-data\nmea-data\index.html.md): Log NMEA 2000 data with the CANedge from maritime/GPS equipment: broadcast logging via DB9-M12, PGN filtering, NMEA 2000 DBC decoding, and multi-frame Fast Packet handling.
- [Validate & log OBD PIDs (manual guide)](record-data\obd2-data-manual-guide\index.html.md): Manual OBD2 PID validation guide: identify supported bit-rate, request CAN IDs (11/29-bit), protocol, and PIDs using partial config files when the OBD tool cannot be used.
- [Log OBD data](record-data\obd2-data\index.html.md): Log OBD2 data with the CANedge: editor OBD tool, PID selection, transmit list creation, response filters, GPS-speed control signal to gate transmission, recording, and DBC decoding.
- [Protocols](record-data\protocols\index.html.md): Index of protocol-specific logging guides for the CANedge: OBD2, UDS, J1939, NMEA 2000, CANopen, CCP/XCP on CAN, and LIN bus.
- [Reduce your log file size](record-data\reduce-file-size\index.html.md): Reduce CANedge log file size: filter builder editor tool, ID/PGN filters, prescalers, message rejection, compression, and control signals - typically 90%+ size reduction without data loss.
- [Tips & tricks](record-data\tips-and-tricks\index.html.md): Practical CAN data logging tips for the CANedge: prefer manual bit-rate over auto, keep RTC in UTC, transmit-frame cautions (battery drain), CAN+LIN channel usage, and advanced bit-rates.
- [Log UDS data](record-data\uds-data\index.html.md): Log UDS data with the CANedge: Single Frame + Flow Control multi-frame requests, EV-specific partial configs (Nissan, Hyundai/Kia, VW), recording, and ISO-TP DBC decoding.
- [Log CCP / XCP on CAN data](record-data\xcp-data\index.html.md): Log CCP / XCP on CAN data from prototype vehicles with the CANedge: dynamic DAQ list initialisation via the canedge-ccp-xcp tool (A2L + measurement CSV), recording, and DBC decoding.
- [LTE/S3 troubleshooting](transfer-data\lte-troubleshooting\index.html.md): Troubleshoot CANedge3 LTE / 3G-4G / S3 connectivity: SIM insertion checks, data plan limits, antenna placement, test Configuration File, syslog diagnostics, and contact procedure.
- [S3 server](transfer-data\s3-server\index.html.md): Configure an S3 server for CANedge wireless upload: cloud (AWS, Google, Azure) vs self-hosted MinIO; links to CANcloud, OTA batch manager, S3 API, and HTTPS/TLS configuration.
- [SIM card](transfer-data\sim-card\index.html.md): Insert and configure a SIM card in the CANedge3 for 3G/4G transfer: PIN/APN configuration, antenna requirements, and the optional IoT SIM for global deployment with discounted rates.
- [AWS S3 - manual deployment](transfer-data\s3-server\aws-s3-manual-setup\index.html.md): Manual AWS S3 bucket and IAM user setup for the CANedge (alternative to the CloudFormation template): CORS policy, AdministratorAccess attachment, and access-key generation.
- [Cloud servers](transfer-data\s3-server\clouds\index.html.md): Set up an AWS S3 (recommended), Google Cloud Storage, or Azure storage bucket as the CANedge upload target. Includes CloudFormation/Terraform templates and a Scaleway alternative.
- [Self-hosted server](transfer-data\s3-server\local-server\index.html.md): Set up a self-hosted MinIO S3 server for the CANedge: local Windows install, command-line launch, firewall configuration; for CANedge3 includes port-forwarding for internet access.
- [S3 tools](transfer-data\s3-server\server-tools\index.html.md): Index of S3 management tools for CANedge data: CANcloud browser app, mounting S3 as local drive, OTA batch manager (canedge_manager), and the S3 API for automation/scripting.
- [Tips & tricks](transfer-data\s3-server\tips-and-tricks\index.html.md): Remote-transfer tips: pre-deployment testing, file-size optimisation, log-rate vs upload-rate sizing, smaller file split for unreliable links, secure password storage, and OTA workflow.
- [Cloud server TLS](transfer-data\s3-server\https\cloud\index.html.md): Enable HTTPS/TLS uploads from the CANedge to a cloud S3 server (AWS, Google, Azure-Flexify, Scaleway): use pre-built root CA bundles or manually download a custom endpoint certificate.
- [MinIO server TLS](transfer-data\s3-server\https\self-hosted\index.html.md): Enable HTTPS/TLS on a self-hosted MinIO S3 server using OpenSSL: generate IP-SAN keys, configure MinIO to serve TLS, and point the CANedge to the https:// endpoint.
- [Install self-signed certificates on PC](transfer-data\s3-server\https\self-signed-pc\index.html.md): Install a self-signed TLS certificate on Windows (mmc + Trusted Root) or Linux (update-ca-certificates) so browsers and S3 tools trust your local CANedge MinIO server.
- [CANcloud - manage devices & log files](transfer-data\s3-server\server-tools\cancloud-intro\index.html.md): CANcloud open-source browser tool for managing CANedge devices and S3 log files: Login via Configuration File, file/device management overview, batch over-the-air updates, and the public playground demo link.
- [How to mount your S3 server on Linux](transfer-data\s3-server\server-tools\mount-s3-linux\index.html.md): Mount your CANedge S3 server as a Linux drive via s3fs: install on Debian-based systems, store access credentials in ~/.passwd-s3fs, and mount the bucket as a local folder.
- [Mount your S3 server as a local drive](transfer-data\s3-server\server-tools\other-s3-tools\index.html.md): Mount your CANedge S3 server as a local drive on Windows (TntDrive, Rclone, ExpanDrive) or other platforms for direct file access in data-processing tools and scripts.
- [S3 API](transfer-data\s3-server\server-tools\s3-api\index.html.md): S3 API use cases for CANedge: batch OTA updates, event-triggered log file processing, the canedge_browser Python library, and API examples for automation and integration.
- [Over-the-air batch manager](transfer-data\s3-server\server-tools\s3-ota-batch-manager\index.html.md): Over-the-air batch manager (canedge_manager) Python CLI/API to update Configuration Files and firmware across an entire fleet of connected CANedge devices.
- [DBC decode data](log-file-tools\asammdf-gui\dbc-convert\index.html.md): DBC-decode CANedge MF4 data to physical values in asammdf: Bus Logging tab, multi-DBC loading, per-channel DBC assignment, and LIN database support via DBC or LDF files.
- [Editing](log-file-tools\asammdf-gui\editing\index.html.md): Edit MDF4 files in asammdf: convert between MDF versions for software compatibility, cut sections by time, filter to selected channels, and resample signals to a uniform rate.
- [Export data](log-file-tools\asammdf-gui\export-data\index.html.md): Export raw or decoded CANedge data from asammdf to other formats (CSV, MAT, HDF5, Parquet) for spreadsheets, MATLAB analysis, or Python pipelines.
- [Create plots](log-file-tools\asammdf-gui\plot-data\index.html.md): Visualise decoded CANedge signals in asammdf plots: enable sub-windows, drag-and-drop channels onto plots, sync X-axis across plots, and tile multiple sub-plots horizontally.
- [Load raw data](log-file-tools\asammdf-gui\raw-mdf4\index.html.md): Open and review raw CANedge MF4 log files in asammdf: CAN/LIN bus trace view, error/remote frames, timestamp formatting (delta vs absolute), and MFC/MFE-to-MF4 conversion.
- [Grafana-Athena dashboards](log-file-tools\browser-dashboard\grafana-athena\index.html.md): Visualise CANedge CAN/LIN data in Grafana via an Amazon Parquet data lake + Athena SQL queries. Recommended dashboard stack: includes initial setup and dashboard customisation guides.
- [Grafana-BigQuery dashboards](log-file-tools\browser-dashboard\grafana-bigquery\index.html.md): Visualise CANedge CAN/LIN data in Grafana via a Google Parquet data lake + BigQuery SQL queries. Includes initial setup and dashboard customisation guides.
- [Grafana-Synapse dashboards](log-file-tools\browser-dashboard\grafana-synapse\index.html.md): Visualise CANedge CAN/LIN data in Grafana via an Azure Parquet data lake + Synapse (Microsoft SQL Server) queries. Includes initial setup and dashboard customisation guides.
- [PowerBI-Synapse dashboards](log-file-tools\browser-dashboard\powerbi-synapse\index.html.md): Visualise CANedge CAN/LIN data in Power BI via an Azure Parquet data lake + Synapse. Includes the initial setup guide for the full dashboard stack.
- [MF4 decoder troubleshooting](log-file-tools\mdf4-decoders\mf4-decoder-troubleshooting\index.html.md): Troubleshoot MF4 decoder issues: DBC syntax/prefixes/min-max validation, drag-and-drop tests with Tad, message-key collisions, variable-length CAN IDs, and missing-message diagnostics.
- [Parquet data lake - advanced topics](log-file-tools\mdf4-decoders\parquet-data-lake-advanced\index.html.md): Index of advanced Parquet data lake topics: backlog processing, device-specific DBCs, event detection with email alerts, calculated signals, trip summaries, external databases, custom cloud functions, client-specific routing.
- [Parquet data lake](log-file-tools\mdf4-decoders\parquet-data-lake\index.html.md): Set up a Parquet data lake to automatically DBC-decode CANedge MF4 logs into Parquet files: DBC preparation, local test, and links to AWS/Google/Azure/local deployment guides.
- [Update your CloudFormation stack revision](log-file-tools\mdf4-decoders\update-glue\index.html.md): Update an existing AWS CloudFormation stack for the Amazon Parquet data lake to a newer Lambda function or Python script revision; uses CloudFormation change sets for safe deployment.
- [Import your Amazon S3 input bucket](log-file-tools\mdf4-decoders\parquet-data-lake\amazon-import\index.html.md): Import an existing AWS S3 input bucket (previously deleted or manually created) into the CANedge CloudFormation stack so that the automation/integration can be deployed on top of it.
- [Amazon Parquet data lake](log-file-tools\mdf4-decoders\parquet-data-lake\amazon\index.html.md): Deploy an Amazon Parquet data lake: S3 input/output buckets, a Lambda DBC-decoder, Athena SQL interface, and support Glue jobs (mapping, backlog, summaries) deployed via CloudFormation.
- [Azure Parquet data lake](log-file-tools\mdf4-decoders\parquet-data-lake\azure\index.html.md): Deploy an Azure Parquet data lake: input/output containers, Azure Function DBC-decoder, Synapse SQL interface, and Terraform-deployed HNS-enabled storage account.
- [Google Parquet data lake](log-file-tools\mdf4-decoders\parquet-data-lake\google\index.html.md): Deploy a Google Parquet data lake: input/output buckets, a Cloud Function DBC-decoder, BigQuery SQL interface, and support functions for mapping/backlog/trip summaries.
- [Local Parquet data lake](log-file-tools\mdf4-decoders\parquet-data-lake\local\index.html.md): Create a local Parquet data lake by drag-and-dropping a CANedge LOG/ folder onto mdf2parquet_decode.exe; query later with DuckDB or ClickHouse from Grafana/Excel/Python.
- [Add trip summaries to your data lake](log-file-tools\mdf4-decoders\parquet-data-lake-advanced\aggregation\index.html.md): Add trip-summary tables to your Parquet data lake via aggregation.json - per-device, per-message, per-trip rollups for dashboard overviews and cross-trip comparisons.
- [Add event detection with email notifications](log-file-tools\mdf4-decoders\parquet-data-lake-advanced\alerts\index.html.md): Detect events (DTCs, high temperatures, harsh braking) in your Parquet data lake via events.json, send email notifications, and visualise them in a Grafana event-summary dashboard.
- [Process backlog of MDF files](log-file-tools\mdf4-decoders\parquet-data-lake-advanced\backlog\index.html.md): Process a historical backlog of CANedge MDF log files into the Parquet data lake via a JSON trigger; useful for re-creating data lakes or concatenating small files for query speed.
- [Customize your cloud function](log-file-tools\mdf4-decoders\parquet-data-lake-advanced\custom-function\index.html.md): Customise the Amazon / Google / Azure cloud function with custom code: when customisation is appropriate, the default decoder workflow, file-by-file constraints, and integration patterns.
- [Add calculated signals to your data lake](log-file-tools\mdf4-decoders\parquet-data-lake-advanced\custom-signals\index.html.md): Add calculated signal tables as Parquet output to your data lake: when to use cloud-function customisation vs. handling calculations in Grafana transformations or SQL queries (typically 90%+).
- [Use device specific DBC files](log-file-tools\mdf4-decoders\parquet-data-lake-advanced\device-dbc-files\index.html.md): Apply device-specific DBC files in your Lambda/Cloud Function via dbc-groups.json - useful when one input bucket contains multiple device groups that need separate DBC decoding rules.
- [Write data to external database](log-file-tools\mdf4-decoders\parquet-data-lake-advanced\external-database\index.html.md): Write decoded CANedge data to an external database via REST from the cloud function: customise functions.py to load Parquet with pyarrow and POST to your endpoint of choice.
- [Route data to client-specific output buckets](log-file-tools\mdf4-decoders\parquet-data-lake-advanced\routing\index.html.md): Route decoded CANedge Parquet data to per-client output buckets via routing.json, deploy a client-specific stack (Glue database + Athena workgroup) per client, and separate clients in self-hosted Grafana. Advanced, AWS-only, multi-tenant setup.
- [Customize your dashboard](log-file-tools\browser-dashboard\grafana-athena\customize-dashboard\index.html.md): Customise your Grafana-Athena dashboard: load a CANedge template, basics of panel/variable/transformation editing, and inspiration from the CSS Electronics dashboard playgrounds.
- [Set up Grafana-Athena](log-file-tools\browser-dashboard\grafana-athena\initial-setup\index.html.md): Set up Grafana with Amazon Athena as the data source on top of your CANedge Parquet data lake: prerequisites, Grafana Cloud configuration, IAM permissions, and Athena query setup.
- [Customize your dashboard](log-file-tools\browser-dashboard\grafana-bigquery\customize-dashboard\index.html.md): Customise your Grafana-BigQuery dashboard: load a CANedge template, basics of panel/variable/transformation editing, and inspiration from the CSS Electronics dashboard playgrounds.
- [Set up Grafana-BigQuery](log-file-tools\browser-dashboard\grafana-bigquery\initial-setup\index.html.md): Set up Grafana with Google BigQuery as the data source on top of your CANedge Parquet data lake: prerequisites, service account configuration, and BigQuery query setup.
- [Customize your dashboard](log-file-tools\browser-dashboard\grafana-synapse\customize-dashboard\index.html.md): Customise your Grafana-Synapse dashboard: load a CANedge template, basics of panel/variable/transformation editing, and inspiration from the CSS Electronics dashboard playgrounds.
- [Set up Grafana-Synapse](log-file-tools\browser-dashboard\grafana-synapse\initial-setup\index.html.md): Set up Grafana with Azure Synapse as data source (via MS SQL Server) on top of your CANedge Parquet data lake: prerequisites, connection string, and Synapse query setup.
- [Set up PowerBI-Synapse](log-file-tools\browser-dashboard\powerbi-synapse\initial-setup\index.html.md): Set up Power BI with Azure Synapse as data source on top of your CANedge Parquet data lake: prerequisites, Synapse query configuration, and Power BI connection setup.
---
# index.html.md
# Configure your device
Below we outline how to update your device firmware and configuration.
## Check for firmware updates
Before you start, we suggest that you check if a newer firmware exists. You can compare the `fw_ver` in your `device.json` file on the SD card vs. the latest firmware in the [Docs](https://www.csselectronics.com/pages/can-bus-hardware-software-docs).
Note: For `MAJOR`/`MINOR` updates your Configuration File [needs to be updated](configure-device/firmware-update-guide.md#ref-firmware-update-guide).
## Configure your CANedge
The new Configuration File is now loaded by your device the next time it is powered on.
Online editor
Offline editor
For details, see the [config editor tools](configure-device/config-tools.md#ref-configuration-tools) section and the [Docs](https://www.csselectronics.com/pages/can-bus-hardware-software-docs).
#### NOTE
An invalid Configuration File will be defaulted by the device upon power up
#### NOTE
The UIschema lets you toggle advanced configuration settings on/off (off by default)
* **[1]** The Rule Schema (`schema-XX.YY.json`) determines the structure of the editor, while the Configuration File (`config-XX.YY.json`) contains your actual configuration. The optional UIschema (`uischema-XX.YY.json`) determines the styling of the editor (e.g. for toggling advanced settings). For further details on the JSON Schema concept, see the CANedge Docs.
# index.html.md
# Contents
* [Introduction](introduction.md)
* [Configure](configure-device.md)
* [Record](record-data.md)
* [Transfer](transfer-data.md)
* [Process](log-file-tools.md)
* [Docs for AI](ai/index.md)
# index.html.md
# CANedge3 - get started
This guide provides a simple intro to each step of your workflow - including software/API tools.
### Quick links
### Newsletter & links
[Join our newsletter](https://sibforms.com/serve/MUIEAGPWkuLOidMbNUZ4eBnP8FLQleTVIPTKwKumz0t2xv-O51FPo2CVleSAZBx02m2UGU8l4NGne-4E6cWSd8cxGJZ3cjP7d3Ja7AWU3cR8I1vgGlM--GT81WJzyfRfIyAYVoO9Wkoirkx_Z65Cg9RKF_WG6g-JzMx3dacAI84XqgP2yQdlQrAU2cfEOfw3DkH9ij1MhemEKkkU) or [follow us on LinkedIn](https://www.linkedin.com/company/css-electronics/) for major firmware/software updates.
* [Intro & docs](https://www.csselectronics.com/screen/page/can-logger-resources) - overview of documentation
* [Software](https://www.csselectronics.com/screen/page/can-logger-software-api) - overview of software/APIs
* [CSS github](https://github.com/CSS-Electronics) - source code & API examples
# index.html.md
# Process your CAN/LIN data
The CANedge logs raw data in the popular [MDF](https://www.csselectronics.com/screen/page/mdf4-measurement-data-format) (`MF4`) format - supported by many CAN tools.
In this section we outline some useful tools for processing your raw data:
1. [MF4 converters](log-file-tools/mdf4-converters.md#ref-mdf4-converters) - convert MDF log files to other formats (`MF4`, `csv`, `asc`, `trc`)
2. [MF4 decoders](log-file-tools/mdf4-decoders.md#ref-mdf4-decoders) - DBC decode MDF log files to create [data lakes](log-file-tools/mdf4-decoders/parquet-data-lake.md#ref-parquet-data-lake) (`csv`, `parquet`)
3. [asammdf GUI](log-file-tools/asammdf-gui.md#ref-asammdf-gui) - load, edit, DBC decode and plot your data
4. [Python API](log-file-tools/api-tools.md#ref-api-tools) - automate your data processing via Python
5. [MATLAB](log-file-tools/matlab.md#ref-matlab) - automate your data processing via MATLAB
6. [Dashboards](log-file-tools/browser-dashboards.md#ref-dashboards) - visualize your data in customizable Grafana dashboards
### Sample MDF4 data & DBC files
Download raw CANedge MDF log files and DBC files to test the tools:
[`MF4 samples`](/_static/files/mf4-sample-data/mf4-sample-data-v2.1.zip) |
[`CANedge GPS/IMU DBC`](/_static/files/dbc-files/can9-database-01.09.dbc) |
[`OBD2 DBC`](https://canlogger.csselectronics.com/files/dbc-files/obd-dbc-files-v4.3.zip) |
[`J1939 DBC (demo)`](/_static/files/dbc-files/j1939-dbc-demo-v2.1.zip)
See below links for more DBC files:
[J1939 DBC](https://www.csselectronics.com/products/j1939-dbc-file) |
[J1939-73 DBC](https://www.csselectronics.com/products/j1939-73-dbc-file-diagnostic-messages) |
[NMEA 2000 DBC](https://www.csselectronics.com/products/nmea-2000-dbc-file-pgn-database) |
[ISOBUS DBC](https://www.csselectronics.com/products/isobus-dbc-file-iso-11783) |
[EV DBC pack](https://www.csselectronics.com/pages/ev-data-pack-electric-vehicles) |
[Car DBC pack](https://www.csselectronics.com/pages/obd2-data-pack-car-dbc)
# index.html.md
# Record raw data
Below we outline how to record raw data to the device SD card.
## Preparation
Before you connect your device, it is important that you do the following:
1. Read the introduction and hardware installation guide in the [Docs](https://www.csselectronics.com/pages/can-bus-hardware-software-docs)
2. Verify that the pin-out of your application, adapter cable and CANedge match[1](#id3)
## Verify that you can log data
1. Connect & power the CANedge in your application via Channel 1 (green LED lights up)
2. Verify that the device records data to the SD card (yellow and red LEDs blink)
3. Disconnect the device, extract the SD and confirm that the `LOG/` folder now contains data[2](#id4)
4. If you encounter issues, see our [troubleshooting](record-data/logging-troubleshooting.md#ref-record-troubleshooting) section
See also our [protocols section](record-data/protocols.md#ref-record-protocols) for details on e.g. [OBD2](record-data/obd2-data.md#ref-record-obd2-data), [J1939](record-data/j1939-data.md#ref-record-j1939-data), [UDS](record-data/uds-data.md#ref-record-uds-data), [XCP](record-data/xcp-data.md#ref-record-xcp-data) and more.
#### NOTE
Once you’re done testing, learn how to [reduce your log file size](record-data/reduce-file-size.md#ref-reduce-file-size) (typically by 90%+)
* **[1]** Using an adapter cable with an incorrect pinout may damage the device/application and is not covered by the device warranty. If in doubt, contact us
* **[2]** It is important that you disconnect the device from power before extracting the SD to avoid SD corruption. Similarly, when ejecting the SD card from your PC, you must use ‘safe eject’
# index.html.md
# Transfer data
## Transfer data via SD card
When you’re ready to process your data, you’ll need to transfer it from the device SD card:
1. Disconnect the device from power (**before** extracting the SD card)
2. Extract the SD card, insert it into your PC and open the `LOG/` folder
3. Transfer the folders/files you wish to process to your PC
# index.html.md
# Docs for AI
This documentation is also available as a single plain-text file optimised for AI assistants (LLMs). Download the file below and provide it to your LLM to ask questions about the CANedge3.
For the technical product manual, the separate [CANedge Docs](https://www.csselectronics.com/pages/can-bus-hardware-software-docs#canedge-resources) are also available as an AI/LLM-friendly text file - we recommend providing both files to your LLM in combination.
# index.html.md
# Config editor tools
> ##### Table of Contents
>
> * [Using the config editor](#using-the-config-editor)
> * [Encryption tool](#encryption-tool)
---
## Using the config editor
Below we provide details on how to use the config editor.
### Documentation
We recommend that you review the Configuration section of the CANedge Docs. This explains how the JSON Schema concept works incl. the role of the Configuration File, Rule Schema and UIschema. Further, it provides detailed examples for some of the more advanced configuration settings like CAN ID filters.
### Presentation mode - simple vs. advanced
The editor tools will by default hide advanced settings for simplicity. To show all the available settings, you can switch the Presentation Mode in the sidebar.
### Support tools
The editors add a number of configuration tools in the bottom toolbar:
* **Configuration File migration tool**: This lets you load a new `firmware.bin` and migrate your Configuration File to the new structure, carrying over your settings - see our [firmware update tips](firmware-update-guide.md#ref-firmware-update-guide) for details
* **OBD tool**: This lets you quickly setup your device for e.g. logging OBD2 data from cars incl. creating your OBD2 PID transmit list - see our [OBD2 intro](../record-data/obd2-data.md#ref-record-obd2-data) for details
* **Filter builder**: This tool lets you load a CANedge log file (in CSV format) and DBC file(s) to help analyze your data, design filters - and test their impact. See our [intro to reducing file size](../record-data/reduce-file-size.md#ref-reduce-file-size) for details
* **Encryption tool**: This tool helps you encrypt passwords. For details see the CANedge Docs and the encryption tool section. For batch encryption, see CANcloud or the OTA batch manager section
* **Filter checker**: When setting up CAN ID filters, this tool can help evaluate if a given CAN ID will pass through the filter or not. It also provides guidance for setting up J1939 PGN filters
* **Partial config loader**: This lets you load, schema-validate and merge a partial Configuration File (e.g. a transmit list) into your active Configuration File
* **Bit timing calculator**: You can use the “Bit-timing (advanced)” mode to set a custom bit rate for your application and this calculator can be useful in checking your settings
* **Schema & config loader**: This will be open by default when using the editor and lets you load the UIschema, Rule Schema and Configuration File for use in configuration of the device
---
## Encryption tool
The CANedge supports encryption of passwords - see the CANedge Docs for details.
Below we outline how to easily encrypt fields using the encryption tool within the config editor.
#### NOTE
For devices already connected to S3 you can also use the [CANcloud](../transfer-data/s3-server/server-tools/cancloud-intro.md#ref-cancloud) to encrypt passwords - including across batches of devices
### Automatic encryption (recommended)
Make sure your Configuration File is loaded and that all your passwords are in plain text.
Next, open the ‘Encryption tool’ (lock icon) from the bottom menu in the config editor. Click ‘Load device.json’ to load your device.json file from the CANedge SD card. Then click ‘Merge files’.
### Manual mode with new encryption key (advanced)
Within the config editor, click the “Encryption tool” (lock icon) to open the tool.
In the tool, paste the public key (`kpub`) value from your `device.json` file and click “Create keys”[1](#fn-3).
This produces two keys:
1. **Server public key**: Should be added in the security section of the device Configuration File
2. **Encryption key**: Used for the encryption of plain text data (e.g. passwords)
You are now able to encrypt plain text data as follows:
1. Enter a plain text password and click “Encrypt”
2. Copy the encrypted password to the relevant field in the Configuration File
3. Set the corresponding key format to “Encrypted” in the Configuration File
### Manual mode with existing encryption key (advanced)
You can securely store the encryption key for later use. This lets you use the second mode of the encryption tool to encrypt fields using an existing key.
This way you can later update/add passwords without changing the server public key or any pre-encrypted data in your Configuration File.
---
* **[1]** You can extract the `kpub` from the `device.json` file on the device SD card
# index.html.md
# Firmware update tips
> ##### Table of Contents
>
> * [How to migrate your Configuration File](#how-to-migrate-your-configuration-file)
> * [Migration using the config editor](#migration-using-the-config-editor)
---
## How to migrate your Configuration File
If you are performing a Firmware `PATCH` update (e.g. `01.07.03` to `01.07.05`), you simply need to add the new `firmware.bin` file to your SD card root and power cycle the device.
However, if you are performing a `MAJOR`/`MINOR` update (e.g. `01.07.03` to `01.08.01`), you’ll need to add an updated version of your Configuration File as well (a `config-01.08.json` instead of a `config-01.07.json`). The reason for this is that `MAJOR`/`MINOR` firmware updates result in changes to the Configuration File structure. If you do not provide the relevant Configuration File when adding the new `firmware.bin` file, the CANedge will create the necessary Configuration File with default settings instead. See also the CANedge Docs for details.
If you already have a Configuration File with custom settings, you’ll typically want to ‘migrate’ those changes to the new structure. Below we describe methods for doing this.
---
## Migration using the config editor
You can use our simple [config editor](config-tools.md#ref-configuration-tools) tool to aid in the migration. To do so, you start by loading your Configuration File from the old firmware you wish to migrate from.
Next, click the ‘Migrate Configuration File’ editor tool at the bottom and load the `firmware.bin` that you are going to update your device with. The editor will now enable you to migrate the Configuration File, after which you can download the updated file and put it onto your device SD card along with the `firmware.bin` file. Remember to safely eject the SD card.
---
# index.html.md
# About this manual
> ##### Table of Contents
>
> * [Purpose](#purpose)
> * [Other documentation](#other-documentation)
> * [Notation used](#notation-used)
---
## Purpose
The CANedge3 Intro focuses on the following:
* How to get started with the CANedge3
* How to use relevant software & API tools
The document is structured by the steps you go through when using the device for the first time.
---
## Other documentation
The [CANedge Docs](https://www.csselectronics.com/pages/can-bus-hardware-software-docs) serve as the product manual. Those docs detail the hardware, configuration and concepts beyond the scope of the CANedge Intro.
---
## Notation used
The following notation is used throughout this documentation:
### Admonitions
#### NOTE
Used to highlight supplementary information
#### WARNING
Used if incorrect use may result in major loss of data and/or time
# index.html.md
# Python

[About](https://www.csselectronics.com/pages/python-can-bus-api)
---
Python is a popular programming language for working with CAN/LIN data from the CANedge.
You can work with the CANedge data in Python in multiple ways:
1. [MF4 decoders](mdf4-decoders.md#ref-mdf4-decoders): DBC decode your data to **Parquet data lakes** for large scale analysis
2. [python-can](https://canlogger.csselectronics.com/tools-docs/csscan_mf4/python_csscan/index.html): Directly load MF4 log files in **python-can** for specialized use cases
---
## Which method should you use?
If your goal is to analyse large amounts of DBC decoded CAN/LIN data (across many log files), we recommend using the MF4 decoders to create a Parquet data lake. This will make it easier to ‘abstract away’ the log file aspect of your data and enables ‘beyond-memory’ analyses. The Parquet data lake can also serve other purposes, such as [dashboard visualization](browser-dashboards.md#ref-dashboards). See also our [Parquet data lake section](mdf4-decoders/parquet-data-lake.md#ref-parquet-data-lake) for plug & play automation work flows using the MF4 decoders.
For specialized use cases, python-can enables direct loading of CANedge MF4 files. This is useful if you wish to analyse the raw CAN/LIN frames, replay the data via a USB-to-CAN interface, selectively DBC decode messages/signals, inject conditional logic etc. The integration also offers extensions related to e.g. J1939, CANopen, ISO-TP, UDS, XCP and more[1](#fn-compression).
---
* **[1]** If your data is compressed/encrypted/muxed, you can incorporate the [MF4 to MF4 converter](mdf4-converters.md#ref-mdf4-converters) into your work flow using e.g. a Python `subprocess` step to create a decrypted/decompressed/demuxed MF4 file
# index.html.md
# asammdf GUI
[About](https://www.csselectronics.com/screen/page/asammdf-gui-api-mdf4)
---
The [asammdf GUI](https://www.csselectronics.com/screen/page/asammdf-gui-api-mdf4) lets you easily load, review, DBC decode, plot and export your CANedge data.
Learn how to use the tool via our quickstart guide:
1. [Load raw data](asammdf-gui/raw-mdf4.md#ref-asammdf-raw-data) - natively load raw MF4 from the CANedge
2. [DBC decode data](asammdf-gui/dbc-convert.md#ref-asammdf-dbc-decode-data) - DBC decode data to physical values
3. [Create plots](asammdf-gui/plot-data.md#ref-asammdf-plot-data) - visualize decoded CAN signals in plots
4. [Export data](asammdf-gui/export-data.md#ref-asammdf-export-data) - export raw/decoded data to CSV, MAT, …
---
## Installation (GUI)
Download, unzip and click the `asammdfgui` to open the GUI:
Windows (v8.9.0)
Linux (v8.8.13)
---
## Installation (GUI/API)
1. Install Python for Windows or Linux
2. Open your command prompt and write: `pip install -I asammdf[gui]`
3. Open your start menu, write ‘asammdf’ and open the GUI via the asammdf icon
# index.html.md
# Dashboards
[About](https://www.csselectronics.com/screen/page/telematics-dashboard-open-source) | [Playground](https://grafana.csselectronics.stellarhosted.com/d/obd2-gps-car/obd2-gps-car)
---
Dashboards let you create custom and powerful visualizations of your CANedge data:
1. [Grafana-Athena](browser-dashboard/grafana-athena.md#ref-grafana-athena) - visualize your Amazon Parquet data lake in Grafana **[recommended]**
2. [Grafana-BigQuery](browser-dashboard/grafana-bigquery.md#ref-grafana-bigquery) - visualize your Google Parquet data lake in Grafana
3. [Grafana-Synapse](browser-dashboard/grafana-synapse.md#ref-grafana-synapse) - visualize your Azure Parquet data lake in Grafana
4. [PowerBI-Synapse](browser-dashboard/powerbi-synapse.md#ref-powerbi-synapse) - visualize your Azure Parquet data lake in Power BI
#### NOTE
Want to test the setup with sample data? Download this [`MF4/DBC pack`](/_static/files/log-file-tools/grafana-athena/grafana-athena-sample-data.zip)
# index.html.md
# MATLAB

[About](https://www.csselectronics.com/pages/matlab-mdf-mf4-can-bus)
---
MATLAB is a popular programming platform for working with CAN/LIN data from the CANedge.
You can work with the CANedge data in MATLAB in multiple ways:
1. Use our [MF4 decoders](mdf4-decoders.md#ref-mdf4-decoders) to create DBC decoded Parquet files (natively supported by MATLAB)
2. Use MATLAB’s [Vehicle Network Toolbox](https://www.mathworks.com/products/vehicle-network.html) to directly load MF4 files
#### NOTE
For most MATLAB use cases we recommend using the MF4 decoders to create a Parquet data lake - see the [MF4 decoder docs](mdf4-decoders.md#ref-mdf4-decoders) for MATLAB Parquet script examples.
# index.html.md
# MF4 converters
[About](https://www.csselectronics.com/screen/page/mdf4-converters-mf4-asc-csv)
---
The MF4 converters let you easily convert your log files into other formats (`MF4`, `csv`, `asc`, `trc`) to e.g. load the raw data in Vector/PEAK tools.
The converters also enable you to decrypt/decompress/demux[1](#fn-demux) log files.
docs & download
---
* **[1]** Demuxing is relevant if you have recorded data through a [CANmod.router](https://www.csselectronics.com/products/4x-can-bus-router-fd-converter-gateway-usb)
# index.html.md
# MF4 decoders
[About](https://www.csselectronics.com/pages/mdf4-decoders-dbc-mf4-parquet-csv)
---
The MF4 decoders let you easily DBC decode your log files into `csv` or `parquet` files[1](#fn-additional).
This is useful in performing quick analyses or e.g. creating powerful [Parquet data lakes](mdf4-decoders/parquet-data-lake.md#ref-parquet-data-lake).
docs & download
Parquet in Python
Parquet in MATLAB
---
* **[1]** The MF4 decoders also support decompression/decryption/demuxing of data (with demuxing being relevant if you use the [CANmod.router](https://www.csselectronics.com/products/4x-can-bus-router-fd-converter-gateway-usb)). In addition, the MF4 decoders support multi-frame data (ISO TP, J1939 TP, NMEA 2000 Fast Packets)
# index.html.md
# Using the CANmod with your CANedge
In this section we explain how you can use your CANmod and CANedge devices together.
> ##### Table of Contents
>
> * [Connect one CANmod to your CANedge](#connect-one-canmod-to-your-canedge)
> * [Connect multiple CANmod devices to your CANedge](#connect-multiple-canmod-devices-to-your-canedge)
> * [Record 2 x CAN plus CANmod data](#record-2-x-can-plus-canmod-data)
> * [Decode raw CAN frames from the CANmod](#decode-raw-can-frames-from-the-canmod)
> * [CANmod.router](#canmod-router)
> * [Demux data via MF4 converter](#demux-data-via-mf4-converter)
> * [Demux data via MF4 decoder](#demux-data-via-mf4-decoder)
> * [Use ‘filter builder’ tool](#use-filter-builder-tool)
> * [Use CANmod.gps time to sync CANedge RTC](#use-canmod-gps-time-to-sync-canedge-rtc)
---
## Connect one CANmod to your CANedge
The simplest way to connect your CANmod to your CANedge is as follows:
1. Load your CANedge Configuration File via the [config editor](../configure-device.md#ref-configure)
2. In `2ND-PORT` tab click the `+` button
3. In the `CAN CH2` tab, ensure the `Mode` is `Restricted` or `Normal`
4. In the `CAN CH2` tab set the `Bit-rate configuration mode` to `Bit-rate (simple)`
5. Set the bit-rate to `1M/4M` (CANmod.router) or `250K` (other CANmod devices)[1](#id11)
6. Connect the CANmod to the CANedge 2nd port[2](#id12)
7. Ensure the CANmod CAN termination is enabled
#### NOTE
We recommend using our [DB9-DB9/DB9 adapter](https://www.csselectronics.com/products/db9-y-splitter-can-bus) to connect the CANedge to CANmod(s)[3](#id13)
---
## Connect multiple CANmod devices to your CANedge
You can easily connect multiple CANmod devices to the CANedge[4](#id14).
1. Follow the same steps as for a single CANmod device[5](#id15)
2. Configure your CANmod devices to ensure they all output unique CAN IDs
3. Update your CANmod DBC file to incorporate the configured CAN IDs
---
## Record 2 x CAN plus CANmod data
In some cases you may wish to record data from two CAN buses, while also recording data from one (or more) CANmod devices.
1. Configure the CANedge to record data from the two CAN buses as normal
2. Configure the CANmod to use the same bit-rate as the CH1 CAN bus
3. Configure the CANmod to use unique CAN IDs (i.e. no overlap vs the CH1 CAN bus)
4. Disable termination on the CANmod (assuming the CH1 CAN bus is already terminated)
5. Connect the CANmod to the CH1 CAN bus in parallel with the CANedge[6](#id16)
#### NOTE
You can also consider using a CANmod.router to enable 5 x CAN logging
---
## Decode raw CAN frames from the CANmod
The CANmod devices come with DBC files in their Docs/Introduction sections or below. These can be loaded together with your other DBC files in the CANedge data processing tools.
[`CANmod.gps DBC`](/_static/files/dbc-files/can2-canmod-gps.dbc) |
[`CANmod.temp DBC`](/_static/files/dbc-files/can2-canmod-temp.dbc) |
[`CANmod.input DBC`](/_static/files/dbc-files/can2-canmod-input.dbc) |
[`CANmod.router DBC`](/_static/files/dbc-files/can2-canmod-router.dbc)
---
## CANmod.router
You can use a [CANmod.router](https://www.csselectronics.com/products/4x-can-bus-router-fd-converter-gateway-usb) with a CANedge to enable the CANedge to record 5 x CAN - or daisy chain two CANmod.routers to log 9 x CAN. Below we outline tips for this combination:
### Demux data via MF4 converter
The data on CAN2 will be ‘muxed’. To ‘demux’ the data to CAN11-14[7](#fn-demux-examples), you can use the [MF4 to MF4 converter](../log-file-tools/mdf4-converters.md#ref-mdf4-converters) `mdf2mdf`. The demuxed file can be loaded and e.g. DBC decoded in other CANedge software/API tools.
Example 1: Demux data from CAN2 ID 0x10 onto CAN11-14:
```text
mdf2mdf.exe --muxtp-can2=010#11:12:13:14 -i 00000001.MF4
```
Example 2: Demux data from CAN2 ID 0x10 onto CAN11-14 and CAN2 ID 0x12 onto CAN15-18:
```text
mdf2mdf.exe --muxtp-can2=010#11:12:13:14 --muxtp-can2=012#15:16:17:18 -i 00000001.MF4
```
### Demux data via MF4 decoder
Alternatively, you can use the [MF4 decoders](../log-file-tools/mdf4-decoders.md#ref-mdf4-decoders) to demux and DBC decode your data in one step. To do this, add the CANmod.router DBC file along with your other DBC files as illustrated below[9](#fn-router-dbc).
If you use the CANmod.router in a [Parquet data lake integration](../log-file-tools/mdf4-decoders/parquet-data-lake.md#ref-parquet-data-lake), the same principle applies in how the DBC is added in your input bucket next to the other DBC files.

### Use ‘filter builder’ tool
The CANmod config editor supports the use of the ‘filter builder’ tool to analyze data and set up filters on CAN S1-S4 quickly. The steps are similar to the [CANedge filter builder](reduce-file-size.md#ref-reduce-file-size), except that you first demux your MDF with the `mdf2mdf` and then convert the result into CSV via the `mdf2csv`. This CSV can then be loaded in the CANmod config editor ‘filter builder’ tool. In the tool you can specify which ‘demuxed’ CAN channels (e.g. CAN11-14) correspond to the CANmod.router CAN S1-S4.
---
## Use CANmod.gps time to sync CANedge RTC
The CANedge real-time clock (RTC) can be synchronized via a CAN message. This minimizes drift and can be useful e.g. in ensuring that the RTCs of multiple CANedge units stay in sync.
The CANedge Docs contain a detailed example on how to configure this. For a ‘quick start’ you can use below partial config file, which you can load via the [partial config loader](../configure-device/config-tools.md#ref-configuration-tools) tool. This config assumes you’re using the default CANmod.gps CAN IDs and syncs the CANedge RTC based on the CANmod.gps `Epoch` signal when `TimeConfirmed` is true[8](#gps-epoch).
[`FW 01.09, RTC CAN sync 'partial config'`](/_static/files/record/can-rtc-sync/canmod-gps-rtc-sync.json)
---
* **[1]** The CANmod.router uses `1M/4M` CAN FD by default on the primary CAN. Other CANmod devices use the `250K` bit-rate as default, which matches the default for the `Bit-rate standard` field of the CANedge. If you are using a custom bit-rate on the CANmod, you should update the CANedge bit-rate accordingly. Note that the CANedge ‘bit-rate auto detection’ feature does not work if a single CANmod is connected on CAN CH2
* **[2]** The CANmod termination is enabled by default, see also the CANmod Docs. The switch below the DB9 connector should be turned to the Ohm symbol
* **[3]** If you use 3rd party adapter cables, ensure that the pinout is correct (this is not the case for many 3rd party DB9 adapter cables)
* **[4]** There is in principle no limitation on the number of CANmod devices you can daisy chain from a CAN bus perspective - as long as you manage busload and uniqueness of the CAN IDs. However, if you use the CANedge 5V power supply, we recommend connecting a maximum of 10 CANmod devices on the 2nd port. If you need to connect more than this, we recommend to instead use an external power supply.
* **[5]** To daisy chain multiple CANmod devices, you can e.g. use multiple DB9-DB9/DB9 Y-splitter cables
* **[6]** This can e.g. be done via a DB9-DB9/DB9 adapter as per pictures on the CANmod product pages
* **[7]** We recommend demuxing to CAN channels 11, 12, …. This matches the CANmod.router DBC (which assumes ID 0x10 maps to CAN11-14 and 0x12 to CAN15-18) and ensures there will be no overlap vs. CAN9 (GPS/IMU). You can find more demuxing examples in the MF4 to MF4 converter documentation
* **[8]** Using a GNSS based `Epoch` signal enables high-precision RTC synchronization and will result in far more precise synchronization vs. e.g. network-based RTC synchronization
* **[9]** The DBC assumes you connect the CANmod.router to the CANedge CH2 with default configuration. If you deviate from this (e.g. by using customer CAN IDs for the muxed data or daisy chaining multiple routers), then the DBC must be updated accordingly
# index.html.md
# Log CANopen data
CANopen is a protocol often used in industrial machinery, robotics and automotives.
In this section we provide tips on how to log CANopen data with your CANedge.
#### NOTE
We **strongly recommend** that you read our [CANopen intro](https://www.csselectronics.com/pages/canopen-tutorial-simple-intro) and [EDS intro](https://www.csselectronics.com/pages/canopen-eds-file-electronic-data-sheet) before proceeding
> ##### Table of Contents
>
> * [Configure your device](#configure-your-device)
> * [Record CANopen data](#record-canopen-data)
> * [DBC decode CANopen data](#dbc-decode-canopen-data)
---
## Configure your device
Some CANopen data is broadcast, meaning that you do not need to request it. Instead, you can use the default Configuration File with automatic bit-rate detection.
However, you can also configure the CANedge to actively request data via CANopen SDO messages (Service Data Objects) using SDO upload requests. This requires that you know what CAN ID (aka COB-ID) and data payload to transmit in order to request certain data.

---
## Record CANopen data
To log CANopen data, simply connect the CANedge to your CANopen application with a suitable adapter cable. The most common ones are the [DB9-M12](https://www.csselectronics.com/products/m12-db9-cable-5-pin) or [DB9-generic](https://www.csselectronics.com/products/can-bus-db9-open-wire-generic) adapters.
---
## DBC decode CANopen data
To DBC decode CANopen data you need the associated DBC file. In CANopen, DBC files are rarely used - though you may instead have CANopen EDS files (Electronic Data Sheet). In such cases, you can follow our [step-by-step guide](https://www.csselectronics.com/pages/canopen-eds-file-electronic-data-sheet#convert-eds-to-dbc) to convert your EDS to a DBC file.
You can then decode your data via the [processing tools](../log-file-tools.md#ref-process) - we recommend to start with [asammdf](../log-file-tools/asammdf-gui.md#ref-asammdf-gui).

# index.html.md
# Using the internal GNSS/IMU
Below we cover the basics of the internal GNSS/IMU for CANedge variants that support this.
> ##### Table of Contents
>
> * [Install the device](#install-the-device)
> * [DBC decode the data](#dbc-decode-the-data)
> * [Reduce file size](#reduce-file-size)
> * [Enable sensor fusion](#enable-sensor-fusion)
> * [Use GPS speed to start/stop logging/transmission](#use-gps-speed-to-start-stop-logging-transmission)
> * [Use GPS time to sync CANedge RTC](#use-gps-time-to-sync-canedge-rtc)
> * [Output internal data onto CAN1/CAN2 (e.g. GPS/IMU)](#output-internal-data-onto-can1-can2-e-g-gps-imu)
---
## Install the device
The CANedge incl. GNSS/IMU relies on an active GPS antenna in order to provide valid GPS-based signals. The GPS antenna should be installed with clear visibility to the sky.
To make use of IMU data (e.g. acceleration rates), you must also ensure that the CANedge itself is installed and oriented correctly. See the [Docs](https://www.csselectronics.com/pages/can-bus-hardware-software-docs) (Configuration/GNSS).[1](#id5)
---
## DBC decode the data
The internal GNSS/IMU data is recorded in ‘CAN Channel 9’, an internal pseudo channel. To decode the raw GNSS/IMU CAN frames, use the DBC file from the Docs (Internal signals section). The DBC file is also included below.
Note that most software tools (asammdf GUI, Python API, …) support loading multiple DBC files, so that you can in parallel load DBC files relating to CAN Channel 1 and/or 2.
[`can9-database-01.09.dbc`](/_static/files/dbc-files/can9-database-01.09.dbc)
---
## Reduce file size
By default, all GNSS/IMU messages are broadcast at the maximum frequency. This can quickly increase your log file size and we recommend that you filter/prescale the data to only record what you need at the frequency required. You can do so via the CAN INTERNAL section of the Configuration File. For details on filters/prescalers, see our section on [reducing file size](reduce-file-size.md#ref-reduce-file-size).
---
## Enable sensor fusion
If your CANedge is installed in an automotive you can enable sensor fusion. This will greatly enhance accuracy, reduce signal noise and even let you retain a fix in GNSS hostile areas such as parking lots, mines, tunnels etc.
To enable sensor fusion in your Configuration File, selected the advanced view and set the ‘Dynamic platform model’ to Automotive and ‘Sensor fusion’ to Enabled. For most use cases, you can leave the IMU-mount alignment angles at their default values (with ‘Method’ set to Manual)[2](#id6).
---
## Use GPS speed to start/stop logging/transmission
A common way to start/stop your CANedge logging and transmission is by using a speed signal from the CANedge internal GPS/IMU. This is useful to e.g. avoid battery drainage when a transmitting device remains powered on while the vehicle ignition is off - or simply to only record data when a vehicle is actively driving.
Below we provide a ‘partial’ Configuration File, which starts logging/transmission on CAN1/CAN2/CAN9 when the Speed signal is above `0.2 m/s` - and stops when below `0.19 m/s`. You can load this into your own Configuration File with the [partial config loader](../configure-device/config-tools.md#ref-configuration-tools) tool.[4](#fn-partial)
[`FW 01.09 (incl. GNSS/IMU)`](/_static/files/record/control-signal/control-signal-internal-gps-example.json)
---
## Use GPS time to sync CANedge RTC
The CANedge real-time clock (RTC) can be synchronized via a CAN message. This minimizes drift and can be useful e.g. in ensuring that the RTCs of multiple CANedge units stay in sync.
The CANedge Docs contain a detailed example on how to configure this. For a ‘quick start’ you can use below partial config file, which you can load via the [partial config loader](../configure-device/config-tools.md#ref-configuration-tools) tool. This syncs the CANedge RTC based on the internal GPS `Epoch` signal when `TimeConfirmed` is true[3](#id7).
[`FW 01.09, RTC CAN sync 'partial config'`](/_static/files/record/can-rtc-sync/internal-gps-rtc-sync.json)
---
## Output internal data onto CAN1/CAN2 (e.g. GPS/IMU)
With `FW 01.09.01+` you can route data from CAN1/2/9 and LIN1/2 onto CAN1/2. This e.g. allows you to use the CANedge as a GPS-to-CAN module by outputting the internal GPS/IMU messages to your CAN bus. You can also use this to route the internal ‘CAN heartbeat’ onto e.g. CAN1.
Below is a step-by-step guide:
1. Ensure that the source channel reception state is set to ‘Enable’
2. Ensure that the source message is recorded by your CAN ID filters
3. Ensure that the output channel transmission state is set to ‘Enable’
4. Ensure that the output channel ‘Mode’ is set to ‘Normal’
5. Ensure that the output channel bit-rate is fixed (i.e. not auto-detection)
6. In the ‘Routing’ tab click the ‘+’ to add a new rule
7. Add a name (e.g. ‘GnssPosition’) and source (e.g. ‘CAN-internal’)
8. Ensure ‘State’ is enabled and ‘Log’ is disabled (except if debugging)
9. Set the source ID format and ID to match the source message (e.g. ‘11-bit’ and ‘67’)
10. Specify the output channel ID format and ID as per your preference (e.g. ‘11-bit’ and ‘507’)

---
* **[1]** Note that sensor fusion is only supported in automotive applications. Some messages, such as Attitude (roll, pitch, heading), are only valid when sensor fusion is active.
* **[2]** The Docs describe how you can manually adjust and/or estimate the IMU alignment angles. This is relevant if your device cannot be installed as per the default alignment and/or if you want to ensure that your installation is as accurate as possible. This is more advanced and not necessary in most use cases. Note that setting the IMU-mount alignment method to Estimate will result in the device only recording IMU adjustment angles and no other GNSS/IMU data - see the Docs for details.
* **[3]** We recommend that you also downscale the `GnssTime` message within the CAN INTERNAL tab by adding a Time prescaler with a value of `60000`. This reduces the frequency of the message to one message per minute
* **[4]** You should always test this out to verify that it is working as intended before leaving the device for a longer period in your vehicle
# index.html.md
# Log J1939 data
J1939 is a protocol used in most heavy-duty vehicles (trucks, buses, tractors, …).
In this section we outline how to log J1939 data with your CANedge.
#### NOTE
We recommend that you read our [J1939 intro](https://www.csselectronics.com/pages/j1939-explained-simple-intro-tutorial) before proceeding
> ##### Table of Contents
>
> * [Configure your device](#configure-your-device)
> * [Record J1939 data](#record-j1939-data)
> * [DBC decode J1939 data](#dbc-decode-j1939-data)
> * [Advanced: Log J1939 on-request data](#advanced-log-j1939-on-request-data)
> * [Advanced: Multi-frame J1939 data (J1939 TP)](#advanced-multi-frame-j1939-data-j1939-tp)
> * [Advanced: Separate/merge J1939 source address](#advanced-separate-merge-j1939-source-address)
> * [Advanced: Decode J1939-73 DM1 (DTCs)](#advanced-decode-j1939-73-dm1-dtcs)
---
## Configure your device
J1939 data is generally broadcast, meaning that you do not need to request it. Instead, you can use the default Configuration File with automatic bit-rate detection.
Our section on [reducing your log file size](reduce-file-size.md#ref-reduce-file-size) also contains guidance on J1939 PGN filtering.
---
## Record J1939 data
To log J1939 data from a heavy-duty vehicle, you need to find a suitable way to connect the CANedge. Below are the most common methods:
1. [DB9-J1939](https://www.csselectronics.com/products/j1939-db9-adapter-cable-deutsch): This lets you record J1939 data from most trucks, buses, engines, tractors
2. [DB9-CAT](https://www.csselectronics.com/products/caterpillar-db9-9-pin-adapter-cable): This lets you log J1939 data from some Caterpillar vehicles/engines
3. [DB9/DB9-J1939](https://www.csselectronics.com/products/j1939-db9-splitter-adapter-cable): This lets you log 2 x J1939 networks in some vehicles (e.g. tractors)
4. [DB9/DB9-OBD2](https://www.csselectronics.com/products/obd2-j1939-db9-splitter-adapter-cable): This lets you log both J1939/OBD2 in some trucks/buses
5. Contactless [CH1](https://www.csselectronics.com/products/contactless-can-bus-reader-adapter) / [CH2](https://www.csselectronics.com/products/cancrocodile-contactless-can-adapter): This lets you log J1939 data directly from the CAN high/low harness
Once you have identified which adapter cable to use you can follow below steps:
1. Connect the CANedge to your J1939 application via the adapter cable
2. Verify that the device turns on and logs data (CH1 LED and MEM LEDs blink)
3. Disconnect the device from power and extract the SD card
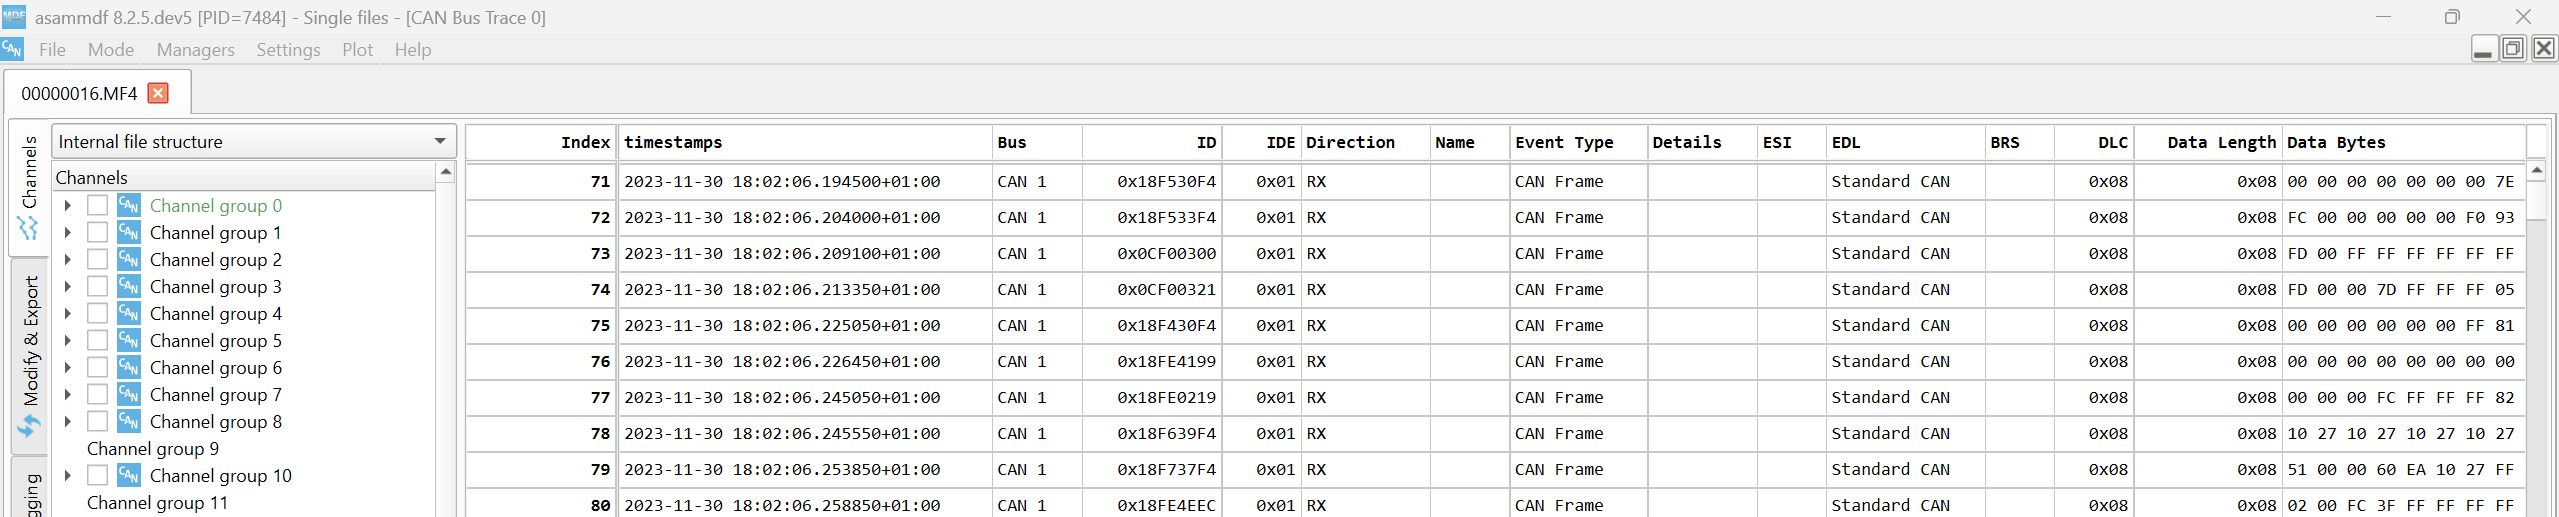
4. Open the MF4 in [asammdf](../log-file-tools/asammdf-gui.md#ref-asammdf-gui) and [display the raw CAN trace](../log-file-tools/asammdf-gui/raw-mdf4.md#ref-asammdf-raw-data) - it should look as below:
---
## DBC decode J1939 data
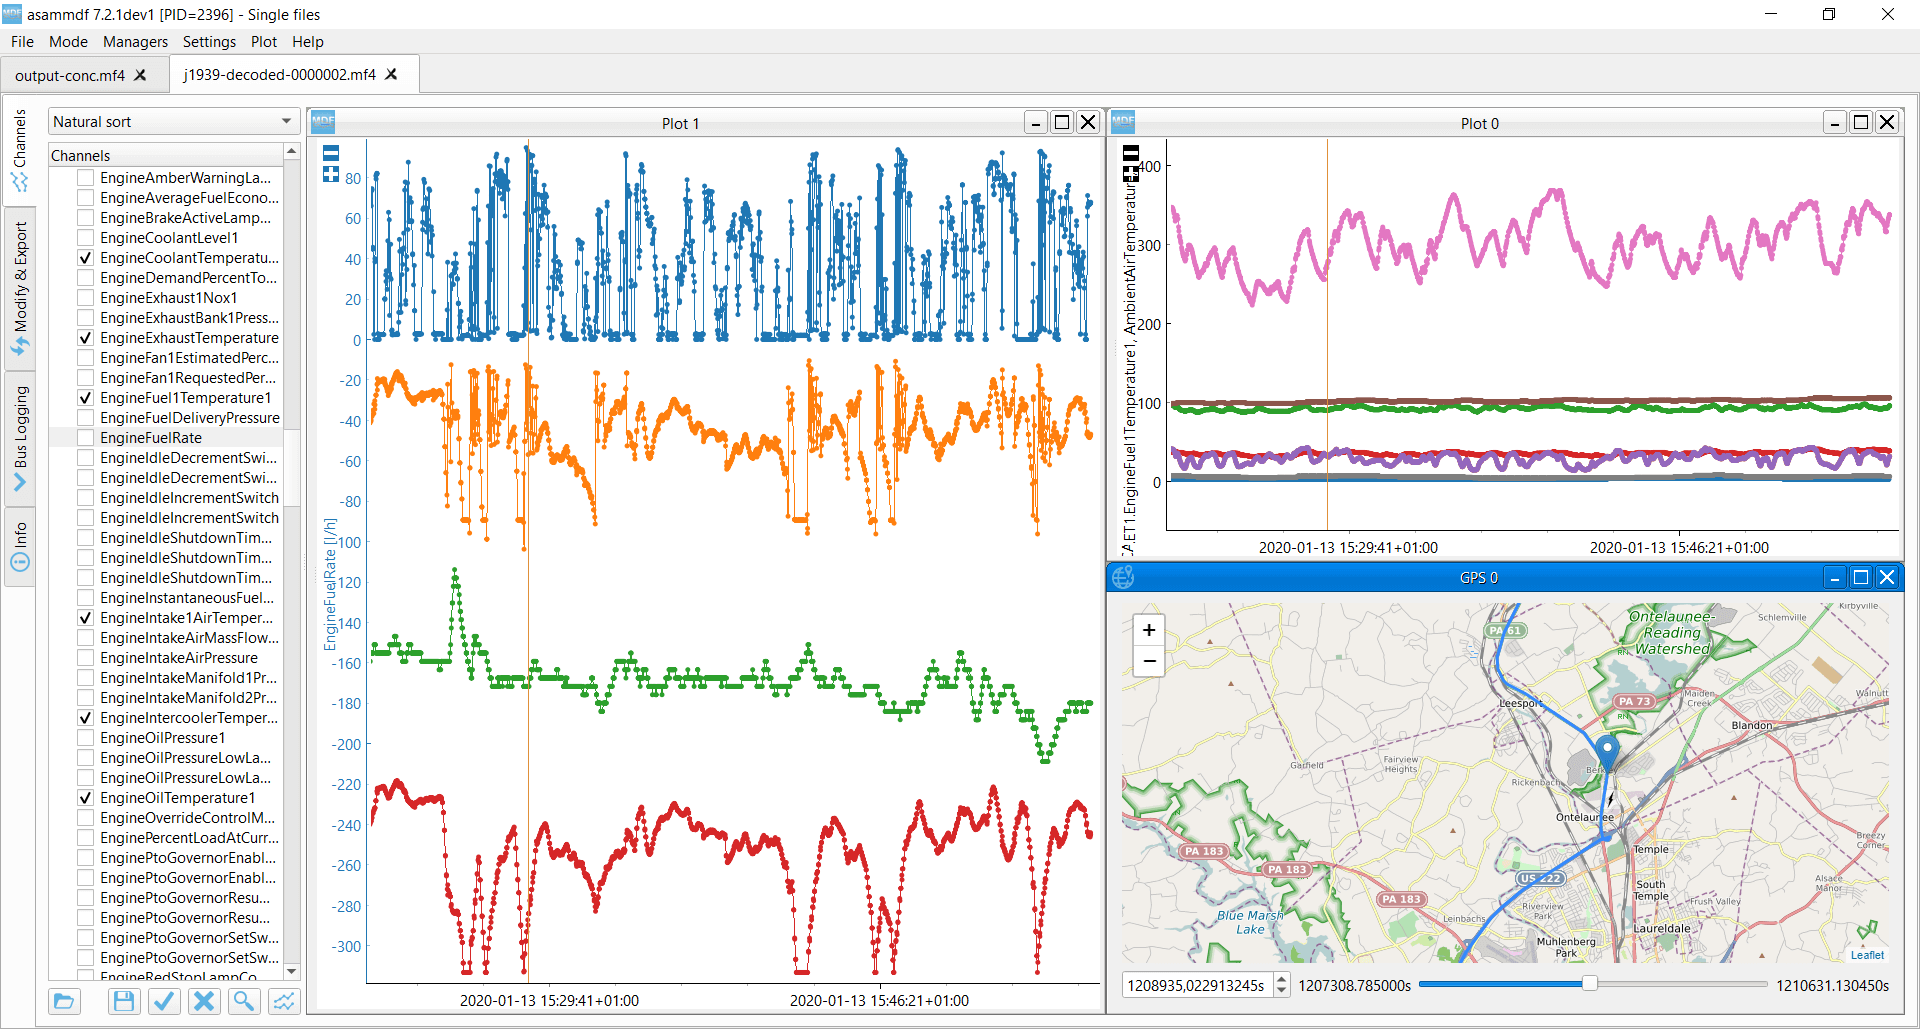
To DBC decode J1939 data you need the associated DBC file. If you are not the equipment manufacturer, you can purchase our [J1939 DBC file](https://www.csselectronics.com/products/j1939-dbc-file), which contains 1800+ PGNs and 12000+ SPNs. For most J1939 networks, this lets you decode the majority of the parameters.
You can decode your data via the [processing tools](../log-file-tools.md#ref-process) - we recommend to start with [asammdf](../log-file-tools/asammdf-gui.md#ref-asammdf-gui).
---
## Advanced: Log J1939 on-request data
In some cases, you may wish to log on-request J1939 data. To do so, you need to transmit the relevant J1939 request frame into the CAN bus - see also our [J1939 simple intro](https://www.csselectronics.com/screen/page/simple-intro-j1939-explained/language/en).
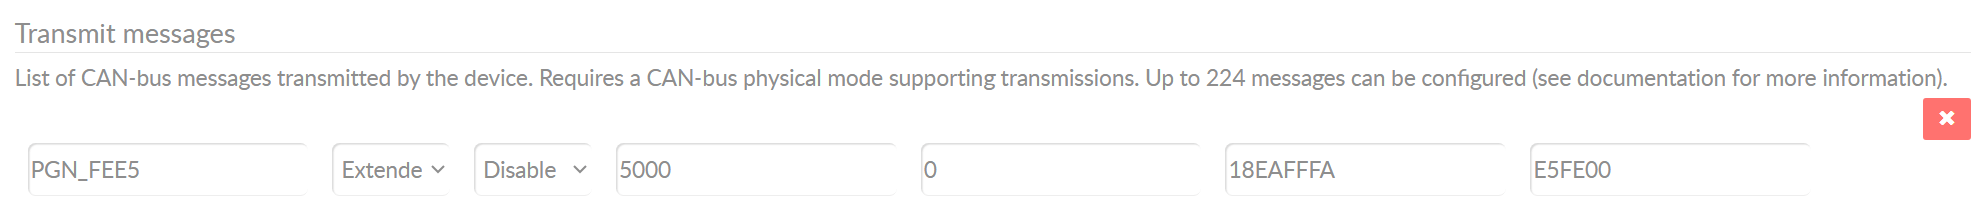
An example is PGN `65253` (`FEE5`) which contains the SPN Engine Hours. Below we show what the transmit message could look like for this particular PGN. There are two key things to note:
1. The transmit frame CAN ID is `18EAFFFA`, reflecting the J1939 request PGN `59904` (`EA00`)
2. Note that we use a ‘global request’ (`0xFF`) and an arbitrary source address (`0xFA`)
3. The data contains the requested PGN `FEE5` (note the byte ordering to `E5FE`)
#### NOTE
A vehicle might not respond to your request - and caution should be taken when transmitting[1](#fn-transmit)
---
## Advanced: Multi-frame J1939 data (J1939 TP)
J1939 often involves multi-frame responses as per J1939 TP, which means that data has to be reassembled before it can be DBC decoded. You can DBC decode and visualize multi-frame data using the [MF4 decoders](../log-file-tools/mdf4-decoders.md#ref-mdf4-decoders) and e.g. [Grafana dashboards](../log-file-tools/browser-dashboards.md#ref-dashboards)
---
## Advanced: Separate/merge J1939 source address
When using the [MF4 decoders](../log-file-tools/mdf4-decoders.md#ref-mdf4-decoders) to DBC decode J1939 data, the default settings will separate each decoded J1939 message by source address (adding this as a suffix to each folder). This is typically preferred if you are analyzing a fleet of similar vehicle models (e.g. as an OEM). However, if you are processing data across a ‘mixed fleet’ of vehicles, the source address separation can make it difficult to e.g. visualize data in static Grafana dashboard panels across devices. In such a case, you can add the argument `--pgn-src-merge` when running the MF4 decoders via the command line - or within e.g. a Lambda automation script. The resulting data lake will join data across multiple source addresses into a single output table.
---
## Advanced: Decode J1939-73 DM1 (DTCs)
If you need to DBC decode and visualize J1939-73 DM1 messages to extract Diagnostic Trouble Codes (DTCs) you should use our [MF4 decoders](../log-file-tools/mdf4-decoders.md#ref-mdf4-decoders) and [J1939-73 DBC](https://www.csselectronics.com/products/j1939-73-dbc-file-diagnostic-messages).
Our J1939-73 DBC files ‘break out’ the DM01 message into the header and separate DTCs. When using the MF4 decoders, this results in separate tables per DTC, header and source address.

For DM1 decoding and visualization, we recommend to use our [Grafana dashboard](../log-file-tools/browser-dashboards.md#ref-dashboards) integrations (Amazon, Google or Azure) as this enables you to easily add a custom DM1 message table as outlined in the [calculated signals](../log-file-tools/mdf4-decoders/parquet-data-lake-advanced/custom-signals.md#ref-parquet-data-lake-advanced-custom-signals) section. The new table is structured as below:

With the calculated DM1 table you can easily visualize your DTCs in e.g. Grafana - and you can optionally also set up [event detection](../log-file-tools/mdf4-decoders/parquet-data-lake-advanced/alerts.md#ref-parquet-data-lake-advanced-alerts) to immediately get notified when a DTC is active (and see all historical events). See also our J1939-73 DM1 Grafana-Athena [playground](https://grafana.csselectronics.stellarhosted.com/d/j1939-73-dm01-truck/j1939-73-dm01-truck?orgId=1):

### Automatically look up DM1 SPN names and descriptions
If you get our [J1939 DBC](https://www.csselectronics.com/products/j1939-dbc-file) it includes a Parquet table with SPN IDs, names and descriptions. You can add this into your Parquet data lake within `aggregations/j1939spn/2024/01/01/j1939-spn-table.parquet` and re-run your table mapping script. This will let you copy/paste our J1939-73 dashboard playground panel, which automatically looks up the SPN names/descriptions for any SPNs that are found in the DM1. Simply copy the panel from our playground into your own dashboard.
---
* **[1]** Be careful if transmitting data onto a vehicle while the ignition is off (as this may ‘wake up’ the ECUs and cause battery drain). If your device remains powered when the ignition is off and you need to transmit data, we recommend using a control signal to start/stop transmission dynamically (see the [OBD2 section](obd2-data.md#ref-record-obd2-data) for examples)
# index.html.md
# Log LIN data
LIN is a protocol used in most automotives today, often serving as a supplement to CAN bus.
In this section we outline how to log LIN data with your CANedge.
#### NOTE
We recommend that you read our [LIN intro](https://www.csselectronics.com/pages/lin-bus-protocol-intro-basics) and [LDF intro](https://www.csselectronics.com/pages/ldf-lin-description-file) before proceeding
> ##### Table of Contents
>
> * [Configure your device](#configure-your-device)
> * [Record LIN data](#record-lin-data)
> * [DBC decode LIN data](#dbc-decode-lin-data)
---
## Configure your device
In most use cases the CANedge acts as a LIN subscriber - sniffing existing LIN traffic being communicated between other LIN nodes. In such cases, you need to specify the correct bit-rate. You will most often also need to configure the ‘LIN-bus frames’ section with the length and checksum type for each LIN frame ID[1](#fn-frame-table).
The bit-rate, frame lengths and checksum information can be found in the [LDF](https://www.csselectronics.com/pages/ldf-lin-description-file) (LIN Description File) for your network. Below is an example of this from our [HELLA IBS case study](https://www.csselectronics.com/pages/hella-ibs-lin-bus-data-logger):

If the LIN bus has no existing LIN master (aka LIN publisher), then the CANedge can take this role. In this case you must configure the CANedge as a LIN publisher and enter your LIN schedule table in the ‘LIN-bus transmit list’ section. The LIN bus schedule can also be found in the LDF. The transmit list may consist of a mix of LIN headers (triggering data to be sent by other LIN nodes) and LIN frames including payloads (when the CANedge is to send information to other nodes). Below is an example from our HELLA IBS case study:

---
## Record LIN data
To log LIN data you typically need to create a custom wiring harness that matches the CANedge pin-out (see the CANedge Docs). After this, you can follow below steps:
1. Connect the CANedge to your LIN application via the adapter cable
2. Verify that the device turns on and logs data (CH1 LED and MEM LEDs blink)
3. Disconnect the device from power and extract the SD card
4. Open the MF4 in [asammdf](../log-file-tools/asammdf-gui.md#ref-asammdf-gui) and [display the raw LIN trace](../log-file-tools/asammdf-gui/raw-mdf4.md#ref-asammdf-raw-data) - it should look as below:

---
## DBC decode LIN data
To DBC decode LIN data you need the associated LDF and/or DBC file. LDF decoding is supported in e.g. the asammdf GUI natively. If you wish to visualize your LIN data in e.g. [Grafana dashboards](../log-file-tools/browser-dashboards.md#ref-dashboards) you will need to first create a DBC file. In such cases, you can follow our [step-by-step guide](https://www.csselectronics.com/pages/ldf-lin-description-file#ldf-vs-dbc) to convert your LDF to a DBC file via canmatrix.
You can decode your data via the [processing tools](../log-file-tools.md#ref-process) - we recommend to start with [asammdf](../log-file-tools/asammdf-gui.md#ref-asammdf-gui).

---
* **[1]** Unless configured otherwise, the device assumes that the length of the LIN frame data payload is always defined by the message ID (bits 5 and 6 of the identifier): 00-31 (0x00-0x1F): DLC 2, 32-47 (0x20-0x2F): DLC 4, 48-63 (0x30-0x3F): DLC 8. Supports LIN 1.3 classic checksum and LIN 2.0 enhanced checksum format. By default, all frames except ID 0x3C and 0x3D use enhanced checksum
# index.html.md
# Logging troubleshooting tips
The below steps can be useful in troubleshooting issues with logging data.
> ##### Table of Contents
>
> * [Check your basic setup](#check-your-basic-setup)
> * [Test if the device powers on correctly](#test-if-the-device-powers-on-correctly)
> * [Test if data is being recorded](#test-if-data-is-being-recorded)
> * [Test if bit timing is incorrect](#test-if-bit-timing-is-incorrect)
> * [Contact us](#contact-us)
---
## Check your basic setup
1. Check your pinout: Verify that your CANedge, adapter cable and application pinouts match
2. Check your wiring: Confirm that the CAN L/H wires are both connected
3. Check your power supply: Verify that you provide a 7-32V power supply to the CH1 connector
4. Verify that you are connecting to a valid CAN bus - and that it is broadcasting data[1](#fn-obd)
5. In e.g. test setups, check if the CAN bus system is properly terminated
---
## Test if the device powers on correctly
1. Delete the Configuration File from the device SD (this will make the CANedge reset it)
2. Connect the CANedge to your application and verify that the green LED lights up
3. If the device does not power on, contact us
---
## Test if data is being recorded
1. Check if the yellow and red LEDs start flashing - if so, data is being recorded
2. If the device does not start recording, try using a manual bit rate in the Configuration File
---
## Test if bit timing is incorrect
If you are able to log data, but you suspect frames are lost, you may need to use a custom bit-rate (rather than one of the default ones). A simple way to detect if this may be relevant is to enable error frame logging and review the raw CAN bus data for error frames via the asammdf GUI. In the CANedge Docs we provide guidance (incl. calculator tools) for setting a custom bit-rate.
---
## Contact us
If you’re still unable to record data, please contact us and provide the following details:
1. Details on your CAN application and setup (picture, bit-rate, termination, power supply etc.)
2. Details on your observed results from the above tests
3. Your `device.json` and Configuration File
---
* **[1]** If you are logging data from an OBD connector, there may be a ‘gateway’ blocking access to the raw CAN data. In this case, you can try recording OBD2 data instead - see our [OBD2 section](obd2-data.md#ref-record-obd2-data)
# index.html.md
# Log NMEA 2000 data
NMEA 2000 is a protocol often used in maritime vessels and GPS equipment (e.g. in tractors).
In this section we provide tips on how to log NMEA 2000 data with your CANedge.
#### NOTE
We recommend that you read our [NMEA 2000 intro](https://www.csselectronics.com/pages/nmea-2000-n2k-intro-tutorial) before proceeding
> ##### Table of Contents
>
> * [Configure your device](#configure-your-device)
> * [Record NMEA 2000 data](#record-nmea-2000-data)
> * [DBC decode NMEA 2000 data](#dbc-decode-nmea-2000-data)
> * [Advanced: Multi-frame NMEA 2000 data (Fast Packets)](#advanced-multi-frame-nmea-2000-data-fast-packets)
---
## Configure your device
NMEA 2000 data is generally broadcast, meaning that you do not need to request it. Instead, you can use the default Configuration File with automatic bit-rate detection.
Our section on [reducing your log file size](reduce-file-size.md#ref-reduce-file-size) also contains guidance on PGN filtering.
---
## Record NMEA 2000 data
To log NMEA 2000 data from a ship/boat, you need to find a suitable way to connect the CANedge. This is typically done using a [DB9-M12](https://www.csselectronics.com/products/m12-db9-cable-5-pin) adapter. In some deployments you may wish to record J1939 data directly from vessel engines in parallel using the CANedge 2nd port. In such cases, see our [J1939 section](j1939-data.md#ref-record-j1939-data) for guidance on connectors.
---
## DBC decode NMEA 2000 data
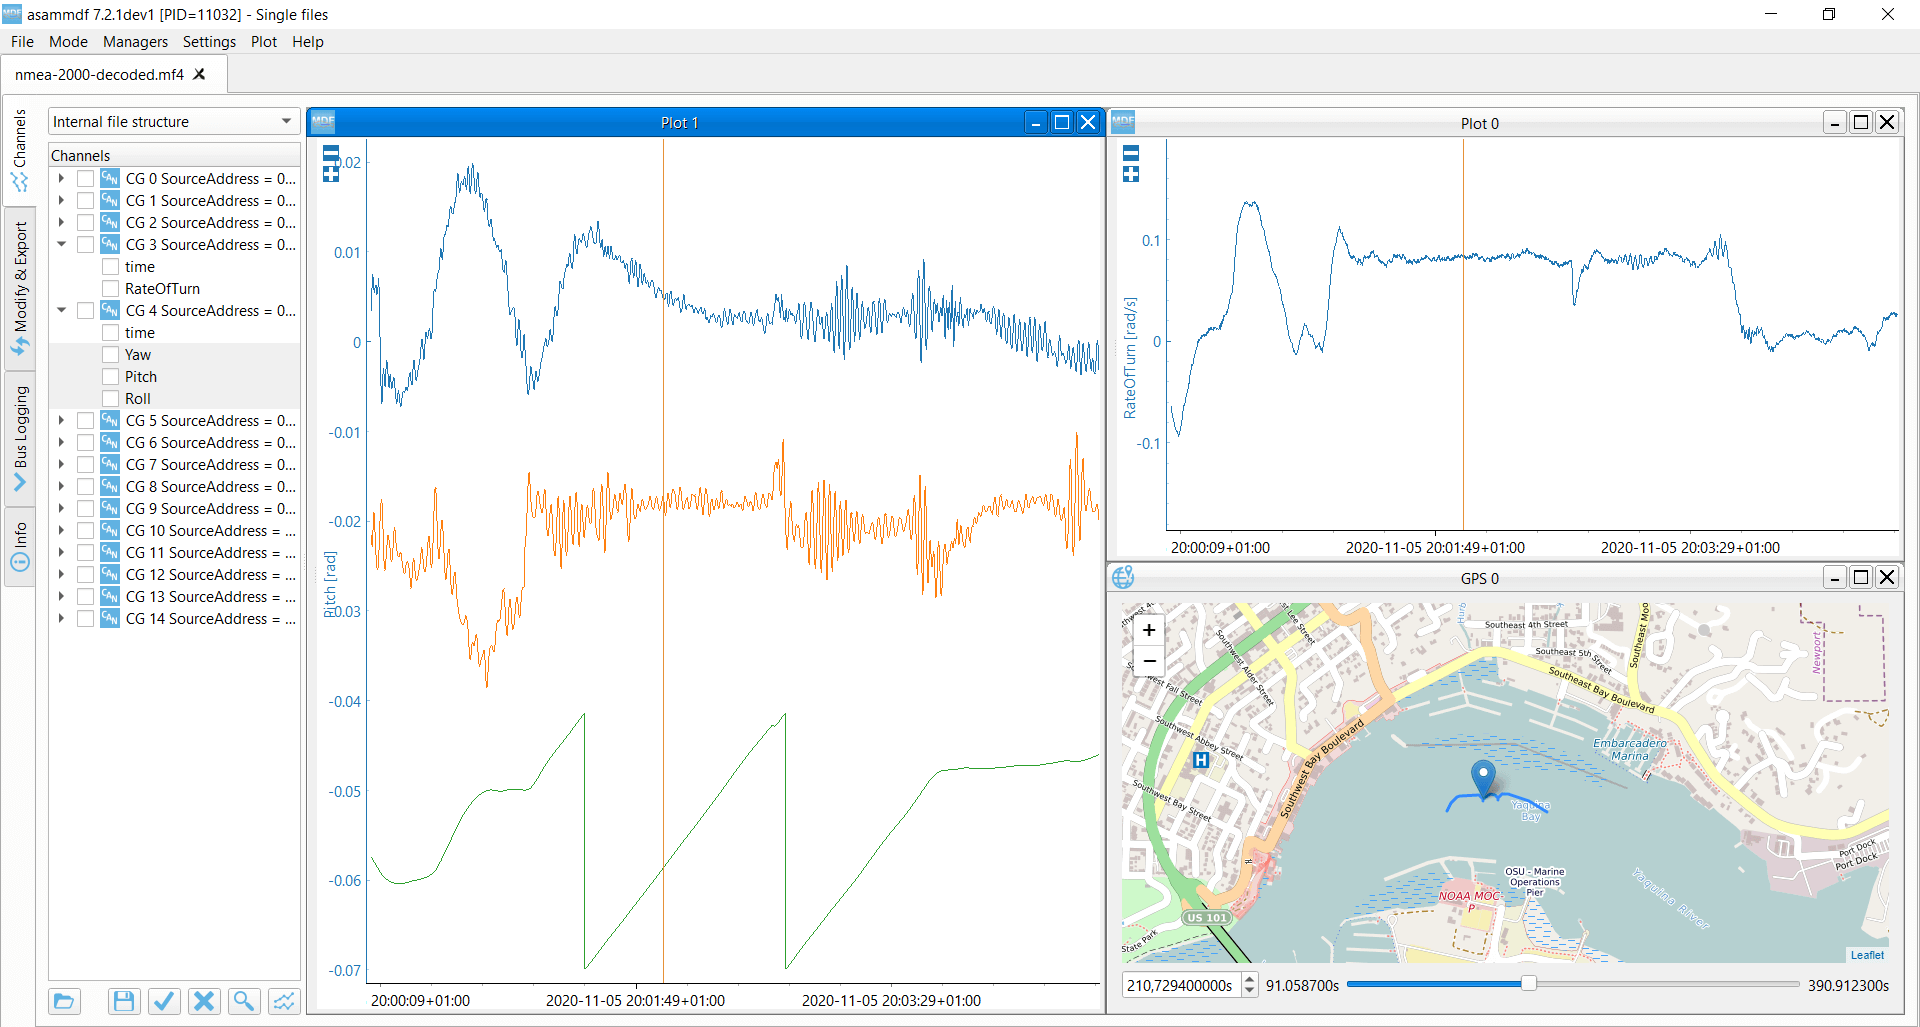
To DBC decode NMEA 2000 data you need the associated DBC file. If you are not the equipment manufacturer, you can purchase our [NMEa 2000 DBC file](https://www.csselectronics.com/products/nmea-2000-dbc-file-pgn-database), which contains 170+ PGNs and 1500+ signals. For most NMEA 2000 networks, this lets you decode the majority of the parameters.
You can decode your data via the [processing tools](../log-file-tools.md#ref-process) - we recommend to start with [asammdf](../log-file-tools/asammdf-gui.md#ref-asammdf-gui).
---
## Advanced: Multi-frame NMEA 2000 data (Fast Packets)
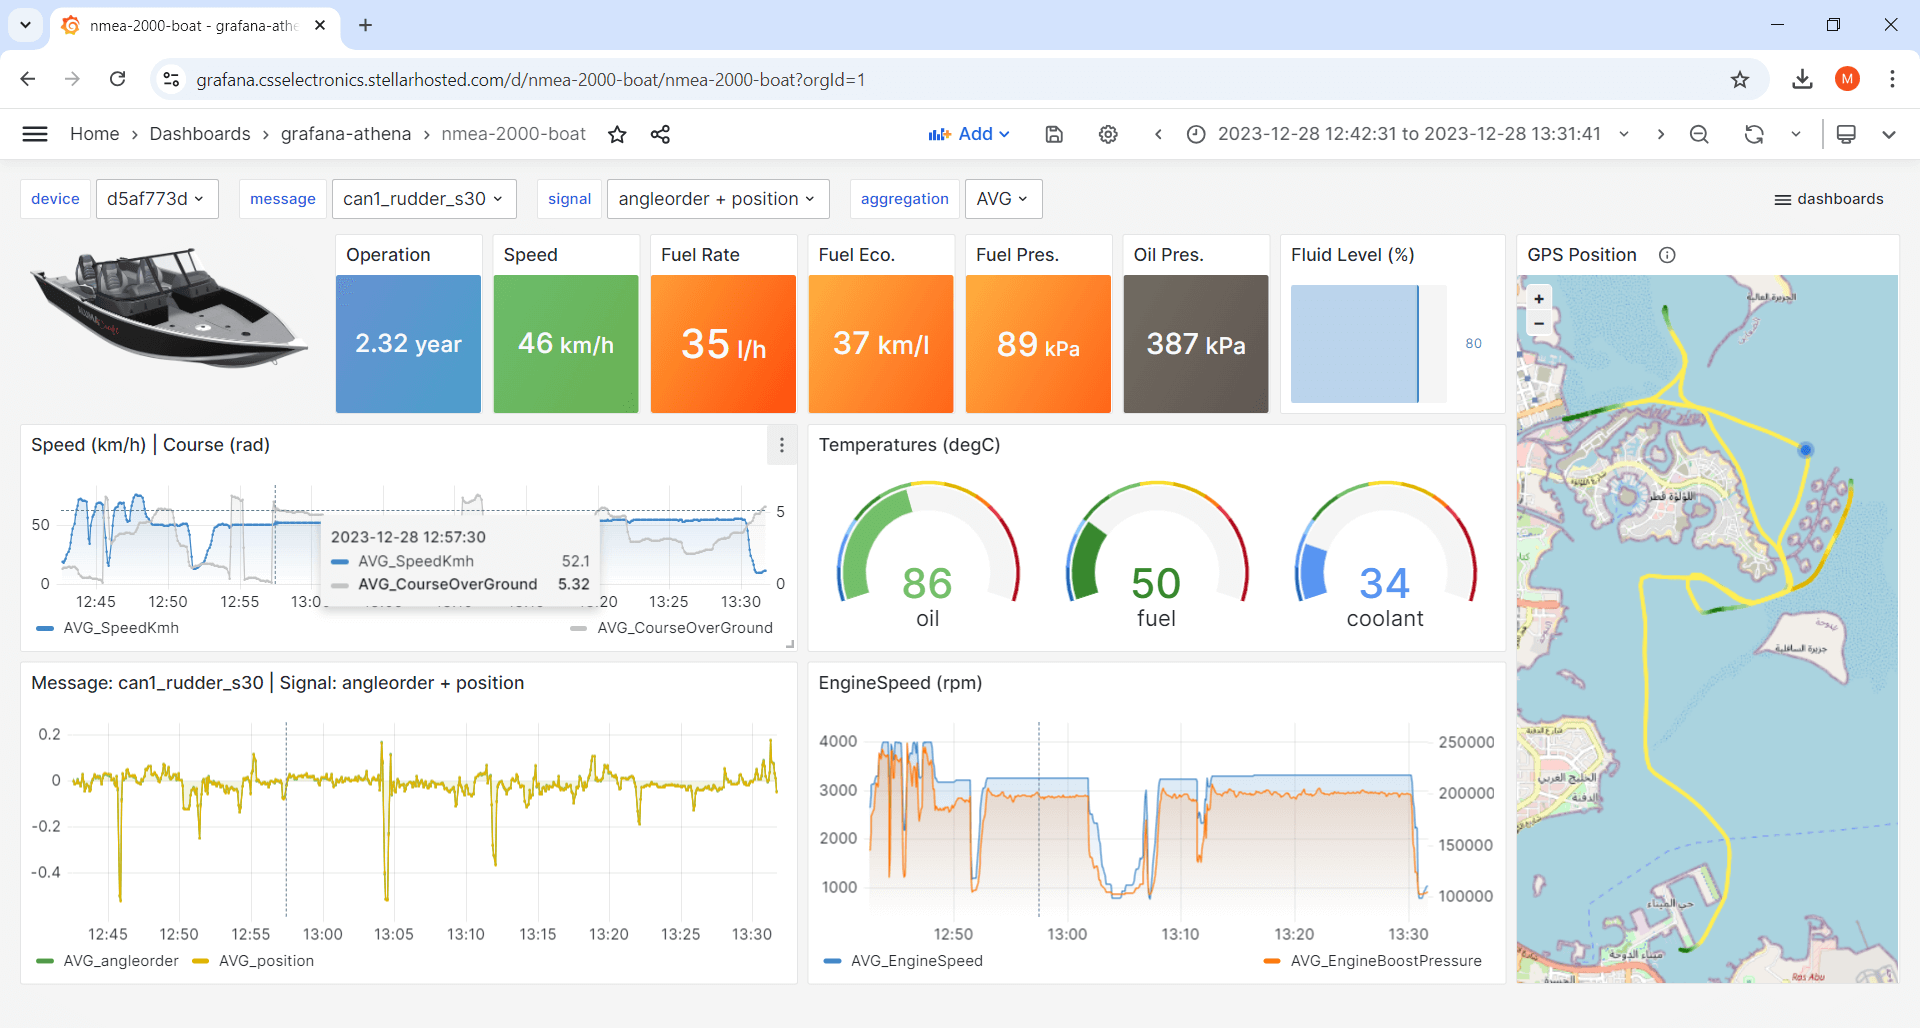
NMEA 2000 often involves multi-frame responses via ‘Fast Packets’. This data has to be reassembled before it can be DBC decoded. You can DBC decode and visualize multi-frame data using the [MF4 decoders](../log-file-tools/mdf4-decoders.md#ref-mdf4-decoders) and e.g. [Grafana dashboards](../log-file-tools/browser-dashboards.md#ref-dashboards). This requires specifying which IDs/PGNs are to be interpreted as Fast Packets in the DBC file meta data (see the [MF4 decoder docs](../log-file-tools/mdf4-decoders.md#ref-mdf4-decoders)). Our NMEA 2000 DBC already includes this meta information and is therefore ready-to-use.
# index.html.md
# Validate & log OBD PIDs (manual guide)
In this section we outline how to validate which OBD PIDs are supported in your vehicle (without the use of our OBD tool). We also describe how you can construct a custom OBD transmit list manually.
> ##### Table of Contents
>
> * [Validation: Determine bit-rate, request IDs, protocol and PIDs](#validation-determine-bit-rate-request-ids-protocol-and-pids)
> * [How to load ‘partial’ config files](#how-to-load-partial-config-files)
> * [1: Identify bit-rate](#identify-bit-rate)
> * [2: Identify request IDs and OBD protocol](#identify-request-ids-and-obd-protocol)
> * [3: Look up supported PIDs](#look-up-supported-pids)
> * [Create a custom OBD2 transmit list](#create-a-custom-obd2-transmit-list)
---
## Validation: Determine bit-rate, request IDs, protocol and PIDs
This section lets you identify what OBD data your vehicle supports and how to request it.
### How to load ‘partial’ config files
First, you will need to learn how to load a ‘partial’ config file:
1. Open your Configuration File in the [config editor](../configure-device.md#ref-configure)
2. Click the bottom menu ‘+’ to open the ‘Partial config loader’ tool
3. Navigate to the relevant partial config JSON, open it and click ‘Merge files’
### 1: Identify bit-rate
OBD may use 500K or 250K bit-rates - below lets you identify which one to use:
1. Load below ‘partial config’ (500K bit-rate) into your Configuration File
2. Download the Configuration File to your SD (replace the original) and safely eject the SD
3. Start your vehicle and leave it running for ~2 min[1](#fn-ignition)
4. Connect the CANedge to the OBD2 connector in your vehicle via the OBD2-DB9 adapter
5. Power it for ~1 min, then disconnect the device and extract the SD card
6. Open the logged MF4 in [asammdf](../log-file-tools/asammdf-gui.md#ref-asammdf-gui) and [display the raw CAN trace](../log-file-tools/asammdf-gui/raw-mdf4.md#ref-asammdf-raw-data)
7. If the CAN trace includes a `CAN Frame` (as in below picture), the bit-rate is 500K
8. If it *only* includes an `Error Frame`, update your CH1 bit-rate to 250K and repeat the above[2](#fn-only-errors)
[`bit-rate test 'partial config'`](/_static/files/record/obd2/obd2-partial-configs/bit-rate-validation/500K/partial.json)

*Example 1: The bit-rate is confirmed to be valid due to successful TX frame*

*Example 2: The bit-rate is confirmed to be invalid due to error frame and no TX frame*
### 2: Identify request IDs and OBD protocol
Depending on your vehicle model/year, OBD may use one of below combinations:
1. Request ID `0x7DF` and OBD2/OBDonEDS protocol (most common in cars)
2. Request ID `0x18DB33F1` and OBD2/OBDonEDS protocol
3. Request ID `0x7DF` and WWH-OBD/OBDonUDS protocol
4. Request ID `0x18DB33F1` and WWH-OBD/OBDonUDS protocol
By requesting data via each of the 4 methods, we can test what the vehicle responds to:
1. Load below ‘partial config’ into your Configuration File
2. If your bit-rate is 250K instead of 500K, update CAN CH1 accordingly
3. Start your vehicle and leave it running for ~2 min[1](#fn-ignition)
4. Power the CANedge in your vehicle for ~2 min
5. Open the resulting MF4 in asammdf and look for `RX` `CAN Frame` entries
6. If the vehicle responds to `0x7DF` OBD2/OBDonEDS requests, combination 1 is supported etc[3](#fn-multiple-protocols)
[`IDs, protocol and PIDs test 'partial config'`](/_static/files/record/obd2/obd2-partial-configs/supported-pids/500K/partial.json)
#### NOTE
If your vehicle output regular proprietary CAN IDs as well, you can look for the relevant response IDs by [filtering](../log-file-tools/asammdf-gui/raw-mdf4.md#ref-asammdf-raw-data) for the ranges `7E8-7EF` and `18DAF100-18DAF1FF`
### 3: Look up supported PIDs
Next, you can determine which OBD PIDs are supported based on the CAN trace:
1. Open our [OBD PID lookup tool](https://www.csselectronics.com/pages/obd2-pid-table-on-board-diagnostics-j1979) and select PID 00 (PIDs Supported [01 - 20])
2. Find the relevant response frame via the CAN trace (see highlighted example below)[4](#fn-response-frame)
3. Copy/paste the relevant 4 payload bytes into the lookup tool’s payload[5](#fn-payload-protocol)
4. Review the resulting PID list and note down supported PIDs of interest
5. Optionally repeat for PIDs `0x20`, `0x40`, … (if responses)
As an example, see below trace with responses to the `7DF` OBD2/OBDonEDS requests:
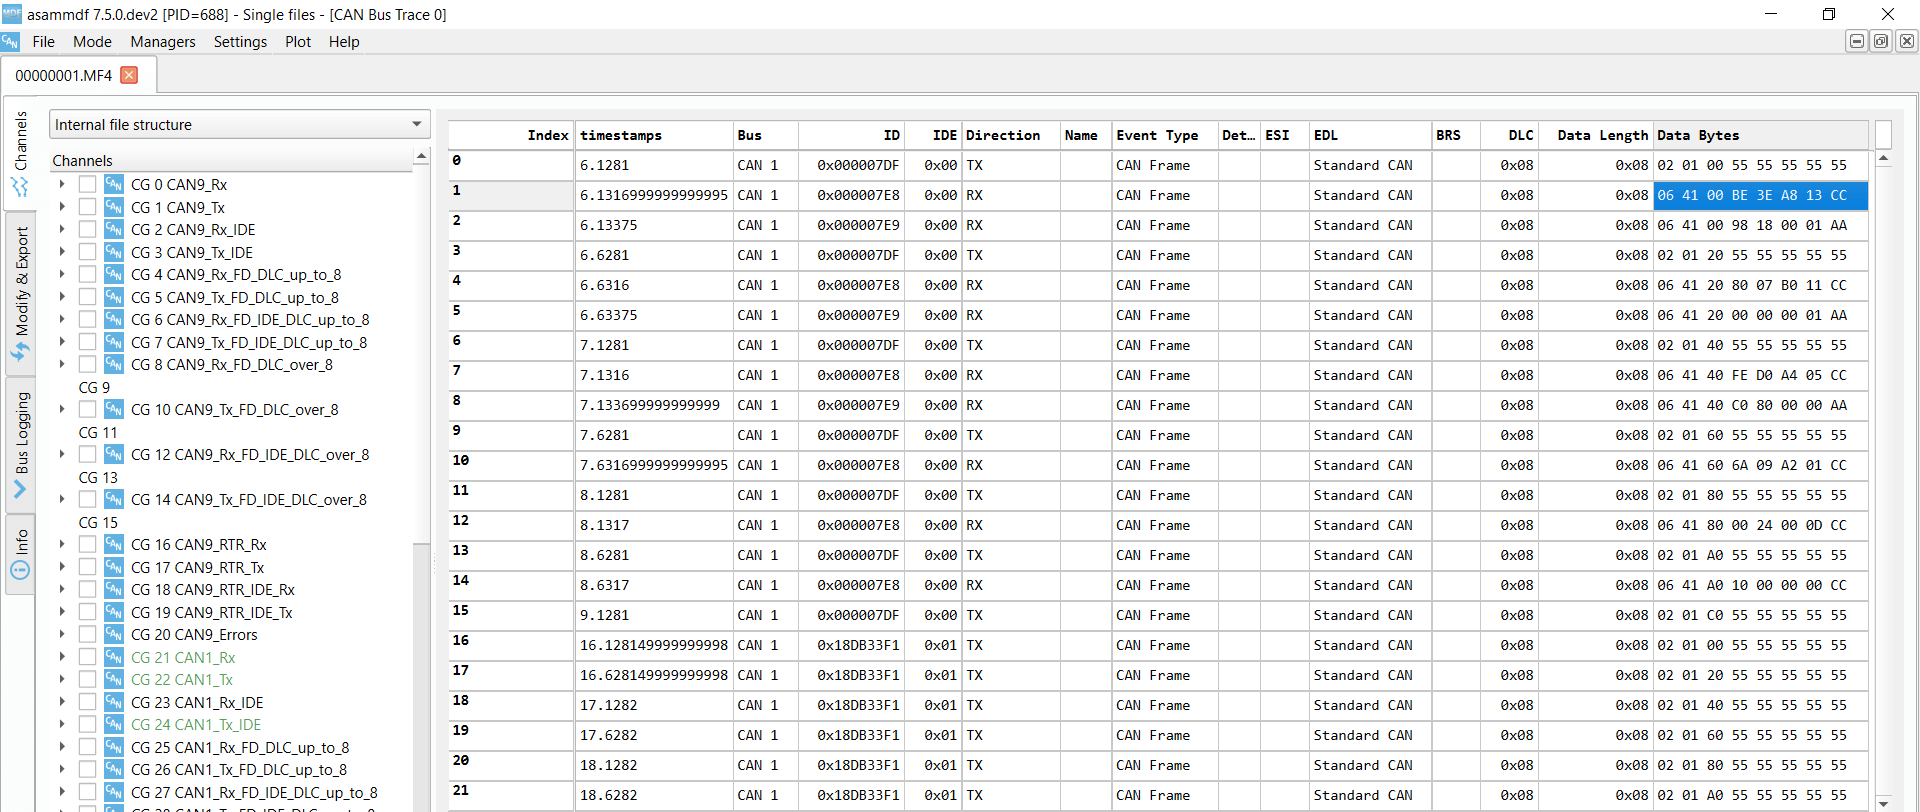
If we copy the first response (ID `0x7E8`) bytes into the tool, we get below result for PID `0x00`:
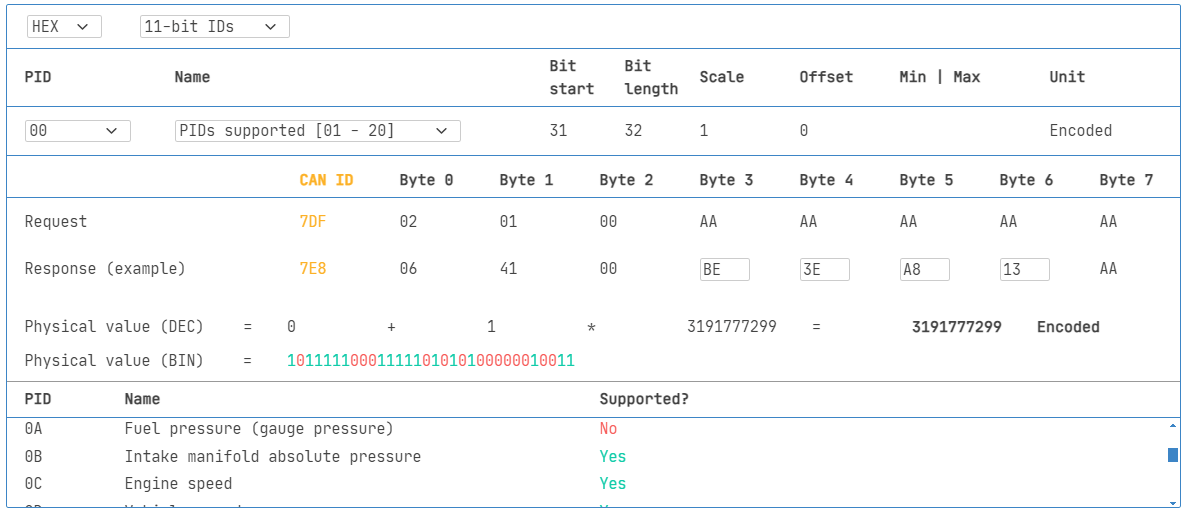
#### NOTE
A typical non-EV car may support 40-80 OBD PIDs out of the ~200 possible PIDs
---
## Create a custom OBD2 transmit list
If you want to add new PID requests, we recommend to first go through the validation step to identify supported PIDs for your vehicle, then include those of interest in your transmit list.
Below we provide ‘partial’ configs for each method as a starting points for your own transmit list:
1. [`11-bit-OBD2/OBDonEDS 'partial config'`](/_static/files/record/obd2/obd2-partial-configs/examples/500K/11-bit-OBDonEDS/partial.json)
2. [`11-bit-WWH-OBD/OBDonUDS 'partial config'`](/_static/files/record/obd2/obd2-partial-configs/examples/500K/11-bit-OBDonUDS/partial.json)
3. [`29-bit-OBD2/OBDonEDS 'partial config'`](/_static/files/record/obd2/obd2-partial-configs/examples/500K/29-bit-OBDonEDS/partial.json)
4. [`29-bit-WWH-OBD/OBDonUDS 'partial config'`](/_static/files/record/obd2/obd2-partial-configs/examples/500K/29-bit-OBDonUDS/partial.json)
#### NOTE
The above examples use 500K bit-rate for CAN CH1 - change this if your vehicle uses 250K
We recommend below steps when creating a custom OBD transmit list:
1. Start out with the relevant ‘partial’ config from the above list
2. In CAN CH1 remove requests that are not supported by your vehicle
3. For each PID you wish to add, add a new entry to the transmit list
4. In the entry, copy all fields from the entry above
5. In the data payload field, set the 3rd byte to match the hex PID value
6. Update the entry name to something suitable, then repeat for the next PID
7. When your list is complete, review all `period` and `offset` values
8. Ensure the `offset` values ‘space out’ all messages by 300-500 ms[6](#fn-offset)
9. Ensure `offset < period` for all entries, otherwise the Configuration File will be invalid
---
* **[1]** The vehicle ECUs may take some time to boot up and acknowledge CAN frames, hence it is useful to wait for a few minutes with the vehicle turned on
* **[2]** Even if the bit-rate is valid, disconnecting the device from an active CAN bus may result in error frames. As such, you should focus on whether the log file contains a `CAN Frame` or not
* **[3]** A vehicle may produce responses to multiple combinations (e.g. `7DF` with both OBDonEDS and OBDonUDS). In such cases, we recommend to look at which PIDs are supported by each method
* **[4]** For OBD2/OBDonEDS this will start with payload `06 41 00`. For WWH-OBD/OBDonUDS it will start with payload `07 62 F4 00`
* **[5]** For OBD2/OBDonEDS, copy/paste the 4th to 7th bytes. For WWH-OBD/OBDonUDS, copy/paste the 5th to 8th bytes. Regardless of the protocol used, the bytes should be pasted into the 4 available fields in the OBD2 lookup tool
* **[6]** In the plug & play config, this is ensured by having a sequence of transmit messages be sent out over a 5000 ms period. If you need to add more transmit messages than what fits in that list, you should expand the period accordingly
# index.html.md
# Log OBD data
OBD is a protocol used in most non-EV 2008+ vehicles (cars, vans, trucks).
In this section we outline how to log OBD data with your CANedge.
#### NOTE
We **strongly recommend** that you read our [OBD2 intro](https://www.csselectronics.com/pages/obd2-explained-simple-intro) before proceeding
> ##### Table of Contents
>
> * [Configure your device (OBD tool)](#configure-your-device-obd-tool)
> * [Record OBD2 data](#record-obd2-data)
> * [DBC decode OBD2 data](#dbc-decode-obd2-data)
> * [Validation: Determine IDs, protocol and supported PIDs](#validation-determine-ids-protocol-and-supported-pids)
> * [OBD requests & battery drainage](#obd-requests-battery-drainage)
> * [Advanced: Multi-frame OBD2 data (ISO TP)](#advanced-multi-frame-obd2-data-iso-tp)
---
## Configure your device (OBD tool)
1. Open your Configuration File in the [config editor](../configure-device.md#ref-configure)
2. Click the bottom menu ‘car’ icon to open the ‘OBD tool’
3. Use the default settings and select the parameters (PIDs) you wish to record
4. Optionally add filters to only log the OBD responses
5. Optionally add control signal to stop PID requests when the GPS-based speed is 0
6. Click **Merge files** to add the OBD details to your existing Configuration File
7. Click ‘Review changes’ and download the file to your SD (replacing the existing)
8. Safely eject the SD and insert it into your device
#### NOTE
This transmits common OBD2 PIDs with 500K bit-rate and 11-bit IDs (supported by most non-EV cars). See also below on how to systematically determine what your vehicle supports
---
## Record OBD2 data
1. Connect the CANedge to the OBD2 connector in your car via the OBD2-DB9 adapter[1](#id6)
2. Verify that the device turns on and logs data (CH1 LED blinking)
3. Disconnect the device from power and extract the SD card
4. Open the recorded MF4 in [asammdf](../log-file-tools/asammdf-gui.md#ref-asammdf-gui) and [display the raw CAN trace](../log-file-tools/asammdf-gui/raw-mdf4.md#ref-asammdf-raw-data)
5. If your car responds you should see CAN frames with ID `0x7E8` in your data as below:
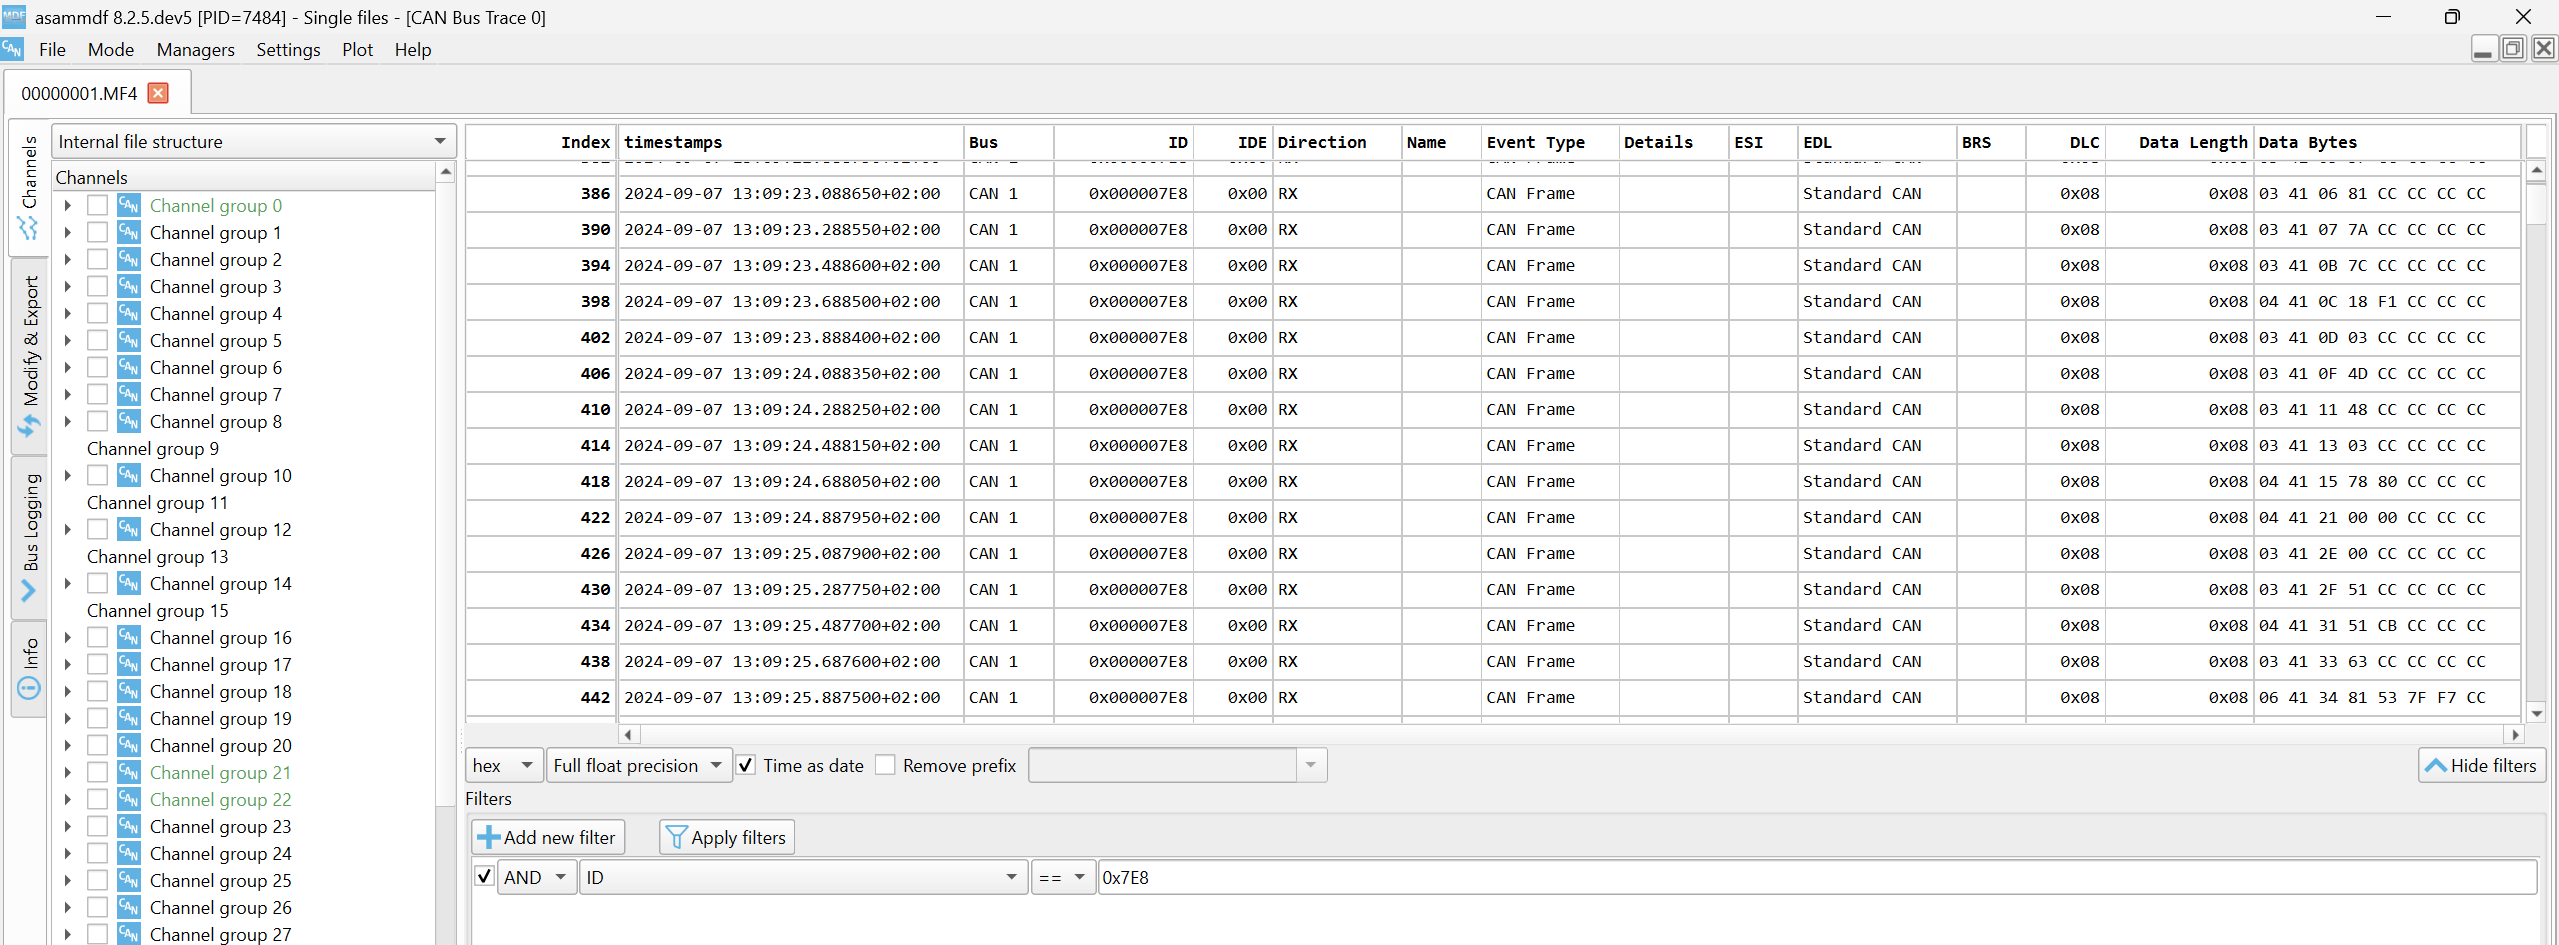
#### NOTE
If your raw data does not contain any ID `0x7E8` OBD2 responses, go to our ‘Validation’ section
---
## DBC decode OBD2 data
To DBC decode OBD2 data we recommend to use our free [`OBD2 DBC`](https://canlogger.csselectronics.com/files/dbc-files/obd-dbc-files-v4.3.zip).
You can decode your data via the [processing tools](../log-file-tools.md#ref-process) - start with [asammdf](../log-file-tools/asammdf-gui.md#ref-asammdf-gui).
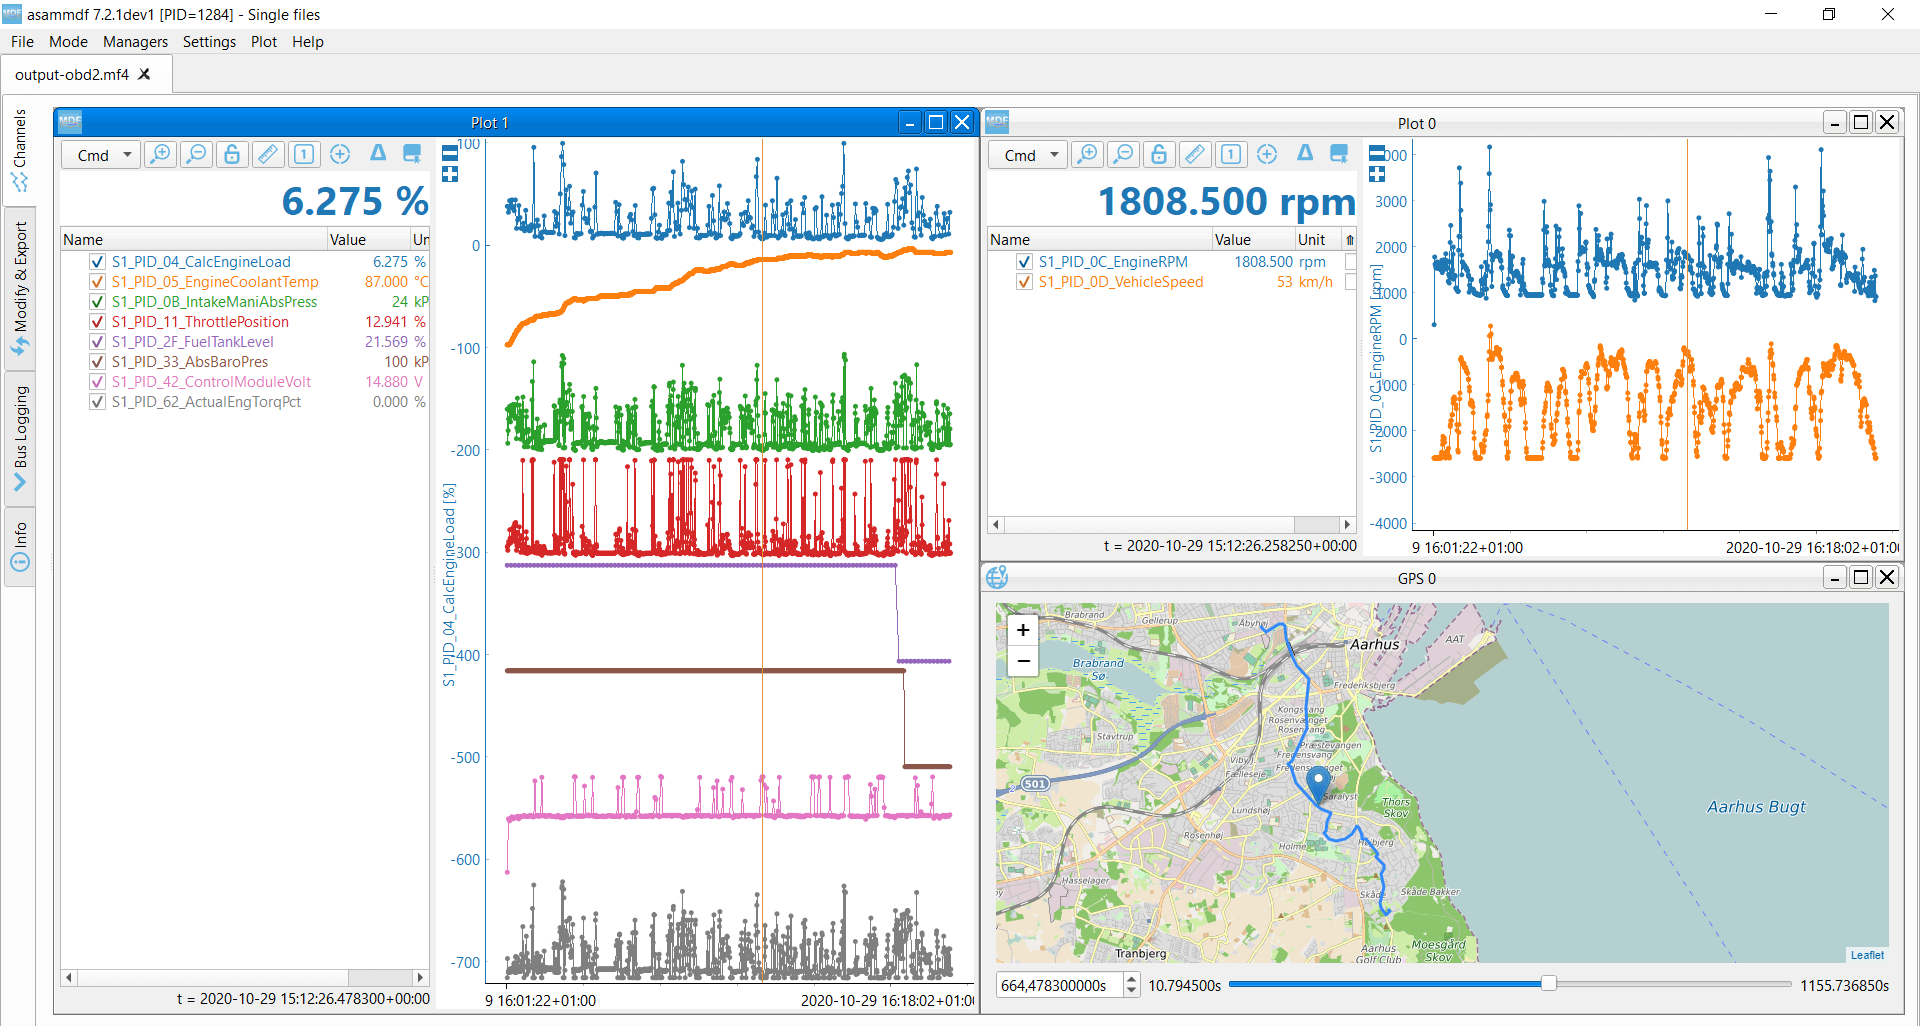
---
## Validation: Determine IDs, protocol and supported PIDs
This section lets you identify what OBD data your vehicle supports and how to request it[2](#fn-manual-guide):
1. In the ‘OBD tool’ select ‘Identify supported PIDs’ and click ‘Merge files’
2. Download the Configuration File to your SD (replace the original) and safely eject the SD
3. Start your vehicle and leave it running for ~2 min[3](#fn-ignition)
4. Connect the CANedge to the OBD2 connector in your vehicle via the OBD2-DB9 adapter
5. Power it for ~3 min, then disconnect the device and extract the SD card
6. Convert the recorded log file to CSV via the [MF4 converter](../log-file-tools/mdf4-converters.md#ref-mdf4-converters) `mdf2csv`
7. Load the CSV in the OBD tool within ‘Select from supported PIDs’
This auto-configures the ID/protocol and limits the PID list to those supported by your vehicle.
#### NOTE
If your CSV is empty, review the raw CAN bus trace in asammdf to see if it only contains CAN errors - if so, try changing the bit-rate e.g. from 500K to 250K
---
## OBD requests & battery drainage
The CANedge consumes <1W[4](#fn-power), which is not an issue for your car battery in practical use cases.
In most cases, the device also turns off with your vehicle ignition. However, if this is not the case then OBD2 requests may ‘wake up’ the car ECUs. In such scenarios consider below solutions:
1. Turn transmission on/off via a control signal - e.g. GPS speed as supported by the OBD tool
2. Disconnect the device between trips
3. Re-wire your OBD2 connector so that the power pin is linked to the ignition
4. Use a [DB9-DB9/DC](https://www.csselectronics.com/products/db9-dc-can-bus-power-splitter) splitter and a [cigarette-to-DC](https://www.csselectronics.com/products/dc-cigarette-outlet-adapter) adapter to power the device
---
## Advanced: Multi-frame OBD2 data (ISO TP)
Some OBD2 communication involves multi-frame data, e.g. DTCs, VIN and more. To request such data, you need to use flow control frames - see our [OBD2 intro](https://www.csselectronics.com/pages/obd2-explained-simple-intro) for detailed examples. Below is an example request for the Vehicle Identification Number. You can DBC decode and visualize multi-frame data using the [MF4 decoders](../log-file-tools/mdf4-decoders.md#ref-mdf4-decoders) and e.g. [Grafana dashboards](../log-file-tools/browser-dashboards.md#ref-dashboards).

#### NOTE
The OBD tool also includes some ISO TP PIDs for the OBD2 protocol (e.g. DTCs, VIN). These use ‘physical’ request IDs (e.g. `7E0`) which may need to be changed in your use case
---
* **[1]** We strongly recommend using one of our OBD-DB9 adapters as 3rd party cables often use different pinouts.
* **[2]** The OBD tool simplifies the process of validating what PIDs are supported by your vehicle. If you prefer, you can find our old ‘manual’ guide [here](obd2-data-manual-guide.md#ref-record-obd2-data-manual-guide)
* **[3]** The vehicle ECUs may take some time to boot up and acknowledge CAN frames, hence it is useful to wait for a few minutes with the vehicle turned on
* **[4]** The CANedge3 consumes up to 2.5W during active LTE transfer
# index.html.md
# Protocols
The CANedge can log data from any CAN/LIN protocol. However, some protocols may involve custom configuration or decoding methods.
In this section we explain how you can log data from the most common protocols:
1. [OBD2](obd2-data.md#ref-record-obd2-data) (cars, vans, trucks, …)
2. [UDS](uds-data.md#ref-record-uds-data) (EVs, cars, …)
3. [J1939](j1939-data.md#ref-record-j1939-data) (trucks, tractors, buses, maritime …)
4. [NMEA 2000](nmea-data.md#ref-record-nmea-data) (maritime, farming equipment, …)
5. [CANopen](canopen-data.md#ref-record-canopen-data) (industrial automation, …)
6. [CCP / XCP on CAN](xcp-data.md#ref-record-xcp-data) (prototype vehicles, …)
7. [LIN bus](lin-data.md#ref-record-lin-data) (automotive, sensors, batteries, …)
# index.html.md
# Reduce your log file size
By default, the CANedge records all raw CAN/LIN frames at their original frequencies - but you can use filters, prescalers, compression and control signals to drastically reduce file size.
In this section we explain how you can reduce the size of your CANedge log files.
> ##### Table of Contents
>
> * [Use filter builder tool](#use-filter-builder-tool)
> * [Tips & tricks](#tips-tricks)
> * [Filter example](#filter-example)
> * [Enable data compression](#enable-data-compression)
> * [Setup control signals](#setup-control-signals)
---
## Use filter builder tool
The simplest way to build filters is via the ‘filter builder’ editor tool:
1. Load your config in the [config editor](../configure-device.md#ref-configure-device), then open the filter builder from the bottom menu
2. Convert an ‘unfiltered’ log file[1](#fn-default-filters) to CSV via the [MF4 converter](../log-file-tools/mdf4-converters.md#ref-mdf4-converters) `mdf2csv` and load it in the tool
3. Optionally load your DBC file(s) with CAN channel prefixes (`can1-`, `can2-`, …)
4. Use the tool to add batches of ID filters to your Configuration File and review the size impact
### Tips & tricks
- Optionally use your DBC files (without CSV data) to set filters
- For J1939/ISOBUS/NMEA data, the tool lets you add PGN filters
- The search box lets you search entries based on channel, ID, name, signal names and more
- Use the ‘replace’ option if you only wish to record the selected IDs
- Use ‘append to top’ to e.g. prescale certain IDs while recording all other IDs as-is
- Use ‘unmatched’ to select all IDs not matched by DBCs to e.g. add them as rejection filters
- Evaluate your added filters via the ‘show summary with current filters’
#### NOTE
For details on how filters/prescalers work, see the [CANedge Docs](https://www.csselectronics.com/pages/can-bus-hardware-software-docs) (Configuration/CAN/Filters)
### Filter example
Below example would result in the following:
1. Only the CAN IDs `70B`, `72A` and `18FFA43D` are recorded
2. `70B` is recorded once every 500 ms
3. `72A` is recorded once every 2nd time it occurs
4. `18FFA43D` is recorded at the original broadcast frequency
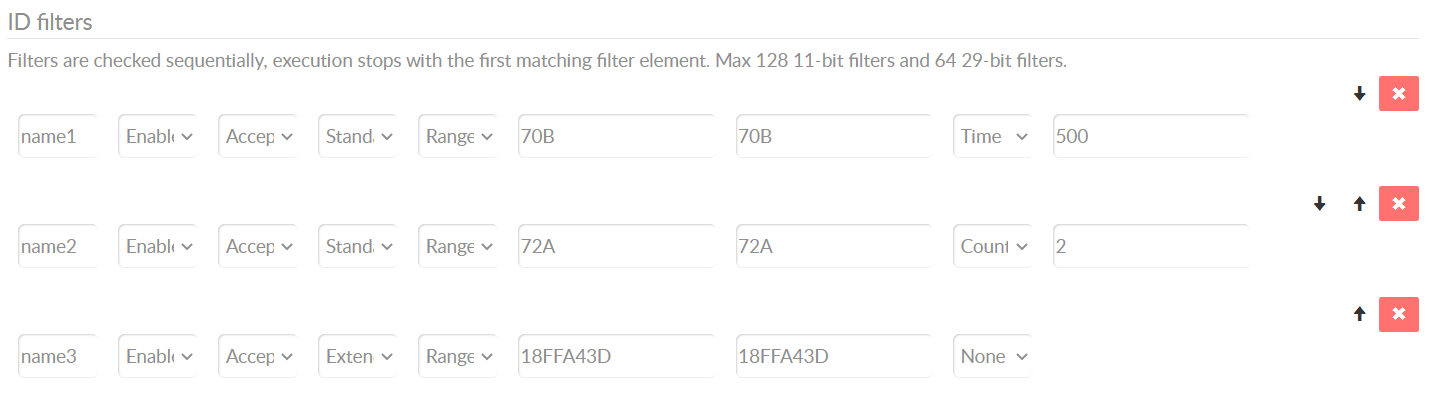
---
## Enable data compression
You can enable compression (in the LOG section) to reduce file size by **50-70%**.
Note that your files will be converted from `MF4` to `MFC` in this case. The MF4 converters/decoders natively process `MFC` files, so for these tools there will be no ‘downside’ to this. If you use asammdf, you must first convert `MFC` files to `MF4` via the MF4 converter `mdf2mdf`.
#### NOTE
If you record very large amounts of data (3+ MB/min), we recommend to use the `256 byte` window instead of the `1024 byte` window[4](#fn-compression-windows)
---
## Setup control signals
Finally, if you only need to record data under certain circumstances, you can use the Control Signal to start/stop logging based on CAN signal thresholds. For detailed examples of how this can be used, see the CANedge Docs.
You can use the control signal to e.g. start logging based on a signal exceeding a limit, or a DTC being flipped. You can also control the behavior of CAN 1 based on a signal on CAN 2.
In the [internal GNSS/IMU section](internal-gnss-imu.md#ref-internal-gnss-imu) we provide an example based on GPS speed.
Below we show how to start/stop logging based on Engine Speed (J1939):
1. In the editor, show the ‘Advanced’ view and select CAN 1
2. Set the ‘Reception (rx) initial state’ to `Disable`
3. In the Control section, set the ‘Control reception (rx) state’ to `Enable`
4. In the Start/Stop sections, enter the signal decoding details[3](#start-stop)
5. Set the Start trigger low to 200 and the high to an arbitrarily high number
6. Set the Stop trigger low to 0 and the high to 199
Below ‘partial config’ contains this example[2](#partial-config):
[`FW 01.09, J1939 engine speed control signal 'partial config'`](/_static/files/record/control-signal/j1939-engine-speed-control-signal-can1.json)
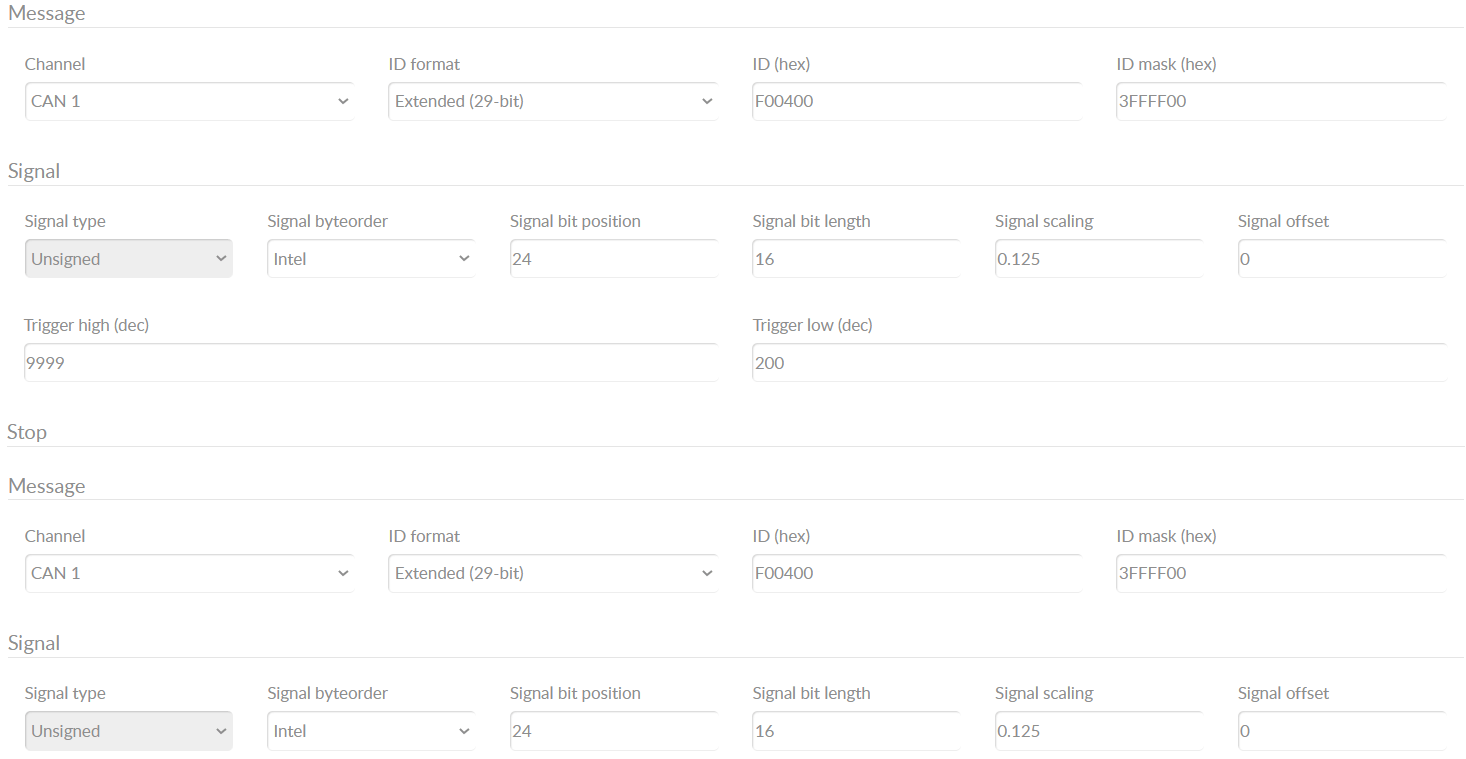
---
* **[1]** Make sure the log file is recorded with the ‘default filters’ (where the device records everything at the raw frequency)
* **[2]** You can load this into your own Configuration File with the ‘Partial config loader’ editor tool
* **[3]** You can find the decoding details via your DBC file. Optionally, you can use our [DBC editor](https://www.csselectronics.com/pages/dbc-editor-can-bus-database) to load your DBC file to identify the various fields
* **[4]** If you are recording a lot of data per minute, the highest compression window can result in reduced performance for other tasks, e.g. affecting the upload speed of CANedge2/CANedge3 devices. For such cases, it is recommended to use a smaller compression window
# index.html.md
# Tips & tricks
Below we’ve collected tips & tricks on data logging based on user experiences:
## Set a manual bit-rate
The CANedge is plug & play with auto bit-rate detection. However, it is recommended to use a manual bit rate when possible to reduce boot time and improve performance.
## Use the default real-time clock timezone (UTC)
The CANedge lets you modify the timezone by offsetting the RTC by a number of hours vs the default timezone (UTC). However, we generally recommend to keep the default UTC timezone to keep things simple. First, the offset will not accomodate daylight saving time. Second, most of the data processing software supports viewing the data timestamps in your local PC time (incl. asammdf, the MF4 converters, Python APIs and dashboards).
## Take care when transmitting data
If you intend to transmit data into the CAN bus, make sure you know what you are doing.
There are two cases to be particularly aware of:
1. Custom frames: If you transmit custom CAN frames into the CAN bus, make sure you understand the implications to avoid inducing unintended behavior into e.g. a vehicle
2. Battery drainage: If the device transmits data while a vehicle is off, it may wake the ECUs and cause battery drainage. Use the control signal to [control transmission](obd2-data.md#ref-record-obd2-data) in this case
## Use both channels
The CANedge has 2 x CAN + 2 x LIN channels. If you only use CAN 1 for your vehicle/machine, you can e.g. use CAN 2 to add extension modules. For example, you can use the [CANmod.temp](https://www.csselectronics.com/products/thermocouple-to-can-bus) to add thermocouple temperature data, the [CANmod.input](https://www.csselectronics.com/products/analog-to-can-bus-digital-pulse) to add 8 x analog/digital/pulse measurements or the [CANmod.router](https://www.csselectronics.com/products/4x-can-bus-router-fd-converter-gateway-usb) to add 4 x CAN channels.
## Consider an advanced bit-rate
The CANedge supports a range of standard bit rates, which are optimized for most CAN based applications. However, you may be able to optimize the logging performance if you optimize the bit rate for your specific setup (cable length etc) via an advanced bit-rate.
# index.html.md
# Log UDS data
UDS (Unified Diagnostic Services) is a protocol often used in automotives, incl. electric cars.
In this section we provide tips on how to log UDS data with your CANedge.
#### NOTE
We **strongly recommend** that you read our [UDS intro](https://www.csselectronics.com/pages/uds-protocol-tutorial-unified-diagnostic-services) before proceeding
> ##### Table of Contents
>
> * [Configure your device](#configure-your-device)
> * [Record UDS data](#record-uds-data)
> * [DBC decode UDS data](#dbc-decode-uds-data)
---
## Configure your device
To request UDS data you need to know what CAN frames to send. In contrast to OBD2, this is proprietary and only known if you are the OEM - or if the info has been reverse engineered.
In our [EV data pack](https://www.csselectronics.com/pages/ev-data-pack-electric-vehicles), we provide ‘partial’ configs that may be used for the following EVs:
1. Nissan EVs (e.g. [Leaf](https://www.csselectronics.com/pages/nissan-leaf-can-bus-obd2-soc-state-of-charge), [Niro](https://www.csselectronics.com/pages/elecric-vehicle-telematics-dashboard-kia-niro-ev))
2. Hyundai/Kia EVs (e.g. Kona, [EV6](https://www.csselectronics.com/pages/kia-ev6-can-bus-data-uds-dbc), Ioniq)
3. VW EVs (e.g. ID.3, ID.4, [Skoda Enyaq](https://www.csselectronics.com/pages/skoda-enyaq-can-bus-uds-dashboard), Audi Q4)
For UDS requests, you often need to send a ‘Single Frame’ (SF) request followed by a ‘Flow Control’ (FC) frame to trigger a multi-frame response from the vehicle. This can be done as illustrated in below picture, where the Flow Control frame is delayed slightly vs. the Single Frame:
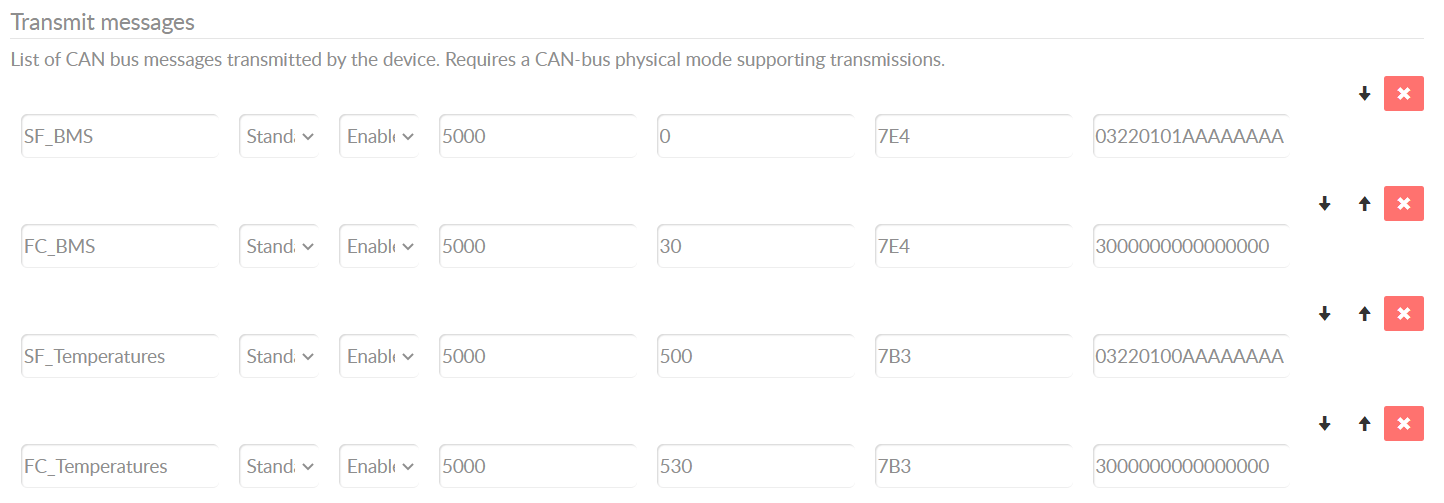
---
## Record UDS data
To record the UDS data, see the section on [OBD2 data](obd2-data.md#ref-record-obd2-data) (the principles are the same). The section also contains guidance on how to avoid transmitting data when the vehicle ignition is off.
---
## DBC decode UDS data
To DBC decode UDS data you need the associated DBC file. If you are not the manufacturer, you may still have access to the DBC if it has been reverse engineered (like our EV data pack DBCs).
UDS often involves multi-frame responses as per ISO TP. You can DBC decode and visualize multi-frame data using the [MF4 decoders](../log-file-tools/mdf4-decoders.md#ref-mdf4-decoders) and e.g. [Grafana dashboards](../log-file-tools/browser-dashboards.md#ref-dashboards) (see below EV6 example).

# index.html.md
# Log CCP / XCP on CAN data
CCP and XCP on CAN are protocols often used in prototype development in automotives.
In this section we provide tips on how to log CCP or XCP on CAN data with your CANedge.
#### NOTE
We **strongly recommend** that you read our [CCP/XCP intro](https://www.csselectronics.com/pages/ccp-xcp-on-can-bus-calibration-protocol) and [A2L intro](https://www.csselectronics.com/pages/a2l-file-asap2-intro-xcp-on-can-bus) before proceeding
> ##### Table of Contents
>
> * [Configure your device](#configure-your-device)
> * [Record CCP or XCP on CAN data](#record-ccp-or-xcp-on-can-data)
> * [DBC decode CCP/XCP on CAN data](#dbc-decode-ccp-xcp-on-can-data)
---
## Configure your device
The CANedge can be used to record CCP or XCP on CAN data by initializing dynamic DAQ lists.
For this purpose you should use our [canedge-ccp-xcp](https://github.com/CSS-Electronics/canedge-ccp-xcp) Python tool. This lets you provide an A2L file and a CSV with measurements you wish to record. The script then creates a ‘transmit list’ for the CANedge for initializing the DAQ lists and a DBC for decoding the data.
If you have any questions on using the script, [contact us](https://www.csselectronics.com/pages/contact-us).

---
## Record CCP or XCP on CAN data
To log CCP or XCP on CAN data, simply connect the CANedge (with the generated Configuration File) to your CCP/XCP application using a suitable adapter cable. The device will initialize the DAQ lists and start recording the ECU response data.
---
## DBC decode CCP/XCP on CAN data
To DBC decode CCP/XCP data you need the associated DBC file - specifically the DBC file created by the canedge-ccp-xcp tool, which matches the transmit list your device is using.
You can decode your data via the [processing tools](../log-file-tools.md#ref-process) - we recommend to start with [asammdf](../log-file-tools/asammdf-gui.md#ref-asammdf-gui).
# index.html.md
# LTE/S3 troubleshooting
The below steps can be useful in troubleshooting connectivity issues.
> ##### Table of Contents
>
> * [Check the basics](#check-the-basics)
> * [Verify a connection to our S3 test server](#verify-a-connection-to-our-s3-test-server)
> * [Test your own S3 server access](#test-your-own-s3-server-access)
> * [Troubleshoot upload speed](#troubleshoot-upload-speed)
---
## Check the basics
1. Set up your S3 bucket as per our [S3 guide](s3-server.md#ref-s3-server)
2. Verify that you can login via CANcloud by loading your Configuration File
3. Ensure that you have followed the [SIM card setup guide](sim-card.md#ref-sim-card)
4. In particular, ensure that your SIM is correctly inserted[1](#id5)
5. Check that your SIM card is active and has not hit a data limit
6. Ensure that you are testing the unit in an area with proper 3G/4G coverage
7. Power the unit for 5 min and see if it uploads the `device.json` to your S3 bucket
*If the device still fails to connect, proceed to the next step below.*
---
## Verify a connection to our S3 test server
1. Download our test Configuration File: [`config-01.08.json`](/_static/files/transfer/troubleshooting/ce3-gnss/config-01.08.json) | [`config-01.09.json`](/_static/files/transfer/troubleshooting/ce3-gnss/config-01.09.json)
2. Load the file in the [config editor](../configure-device.md#ref-configure) and modify the SIM details to match your SIM
3. Ensure that the 3G/4G antenna is connected and has clear access to the sky during your test
4. Create a backup of your original Configuration File on the device SD card
5. Add the test Configuration File to your SD card
6. Power on your device with a suitable power supply (7-32 V DC, >3W) for 5 min
7. Log into the S3 test server via [CANcloud](s3-server/server-tools/cancloud-intro.md#ref-cancloud) and check if your device uploads the `device.json`
8. If the device does not connect, review the `syslog.txt` file on the SD for further diagnostics
9. If the syslog shows issues reading the SIM, review your PIN and physical insertion
10. If the syslog shows that the SIM is accepted, but unable to connect, review your APN/roaming
11. Optionally test with another micro SIM card (update the Configuration File accordingly)
*If it is still not connecting, please send us an e-mail with a zip of the entire SD content, details on which SIM cards you have tested and a description of your setup.*
*If the device connects, proceed to the next step below.*
---
## Test your own S3 server access
Assuming you have verified that your SIM card works with our AWS S3 test server, you can try with your own S3 server.
1. Log into your *own S3 server* via CANcloud via your browser
2. Delete the device Configuration File on your own S3 server[3](#id6)
3. On the device SD, update your Configuration File to use your own S3 server details again
4. Check if the device is now able to connect to your own server (i.e. is the `device.json` uploaded)
5. If the device is still unable to connect to your server, check the below:
* Verify that all your server details are correct (see the [S3 server guides](s3-server.md#ref-s3-server) for syntax)
* Verify that you do not use `https://` in your endpoint (if you have enabled TLS, disable it)[4](#id7)
6. Open your Configuration File via Notepad and set the `syslog` value from 0 to 3, then save it
7. If a `syslog.txt` is already on the SD card, delete or rename it
8. Try the test again and review the new `syslog.txt` for details
*If you’re still unable to get started after trying the above steps, contact us and describe your results from the above tests. In your mail, please include a zip with your SD card contents.*
---
## Troubleshoot upload speed
The CANedge3 is able to upload data at 4-6 MB/min, depending on various factors. If you are seeing unexpectedly slow upload rates, consider below steps:
1. Ensure the CANedge3 LTE antenna has clear line-of-sight to the sky
2. Ensure that you are using the correct APN
3. Ensure the S3 bucket region is near your deployment region
4. Configure your log file splits to be 1-20 MB in size
5. If deploying in areas with poor coverage, consider using a [high-spec antenna](https://www.csselectronics.com/products/2-in-1-antenna-4g-lte-gps-high-spec)
6. If you are recording very high busloads (3+ MB/min MF4), consider using [filters/prescalers](../record-data/reduce-file-size.md#ref-reduce-file-size)[2](#fn-busload)
Below we explain how you can do a clean evaluation of the upload speed:
1. Download & unzip our simulated MF4 log files from [here](https://canlogger1000.csselectronics.com/files/guides/documentation/troubleshooting/canedge-speed-test-data.zip)
2. Add the `meta/` folder from the zip to your SD card root to set your session counter to `50000000`
3. Add the `40000001/` folder inside your device SD `LOG//` folder
4. Power on the device until it has offloaded the full 100 MB of `40000001/` to your S3 bucket
5. In CANcloud, get the #min between the last/first upload in `40000001/` via ‘Last Modified (S3)’
6. Divide 100 MB by the #min to get your upload speed in MB/min
7. After testing, update the `meta/meta_log.json` session number to be your last session number + 1, then add this folder to your SD card root again to correct your session counter
If you are still unable to get the expected upload rates after trying the above steps, [contact us](https://www.csselectronics.com/screen/page/can-bus-logger-contact) and describe your results from the above tests. In your mail, please include your Configuration File.
*If you’re still unable to get the expected upload rates after trying the above steps, contact us and describe your results from the above tests. In your mail, please include your Configuration File.*
---
* **[1]** Gold plating must face up and you should hear a small click upon insertion, as per the SIM card guide. You can check if the device has loaded your SIM card correctly by opening the `device.json` after a power cycle and checking if the `cellular_iccid` field contains your SIM’s ICCID
* **[3]** The device will automatically upload the Configuration File from the SD card when it connects to an S3 server. If a change is made after this to the Configuration File directly on the SD card, the device will perform an over-the-air update and download the Configuration File from the S3 server. To avoid confusion, it is therefore recommended to delete the S3 Configuration File during troubleshooting
* **[4]** HTTPS transfer is an advanced feature. For troubleshooting purposes we recommend to first get the simpler HTTP transfer to work. If you are using a MinIO S3 server and you have enabled TLS, you can temporarily remove the TLS certificates and restart the server
* **[2]** For very high busloads, the CANedge will gradually start reducing upload speed to prioritize lossless data logging. In such scenarios it is recommended to review if filters/prescalers can be added. Compression may also be useful in this context, but it is recommended to use the 256 byte window rather than 1024 byte window for very high busloads
# index.html.md
# S3 server
Below we outline two types of S3 servers that you can use with your CANedge3:
#### NOTE
If you need to upload data via the internet we recommend that you start with an [AWS S3 cloud](s3-server/clouds.md#ref-clouds). It is simple to setup and practically free at small scale.[1](#id2)
---
* **[1]** For most use cases, AWS S3 costs <0.5 $/month/device and is free for 1 year (up to 5 GB)
# index.html.md
# SIM card
To enable 3G/4G data transfer, you’ll need to insert and configure a micro SIM card.
> ##### Table of Contents
>
> * [Insert and configure your SIM card](#insert-and-configure-your-sim-card)
> * [AT&T SIM card registration](#at-t-sim-card-registration)
---
## Insert and configure your SIM card
1. Insert your micro SIM card in the SIM slot on the back (gold plate facing up)[1](#fn-sim)
2. Ensure your 3G/4G antenna is properly connected and has clear access to the sky
3. In your [Configuration File](../configure-device.md#ref-configure), add your PIN and APN (if required)[2](#fn-apn) and optionally enable roaming
4. Once you have added your [S3 server details](s3-server.md#ref-s3-server) you can test the device connectivity
Note that the CANedge3 is not locked to any SIM provider and supports global 3G/4G frequency bands. However, we always recommend that you test the connectivity prior to deployment.
#### WARNING
Incorrect insertion of the SIM card may result in damage to the device[3](#fn-sim-reader)
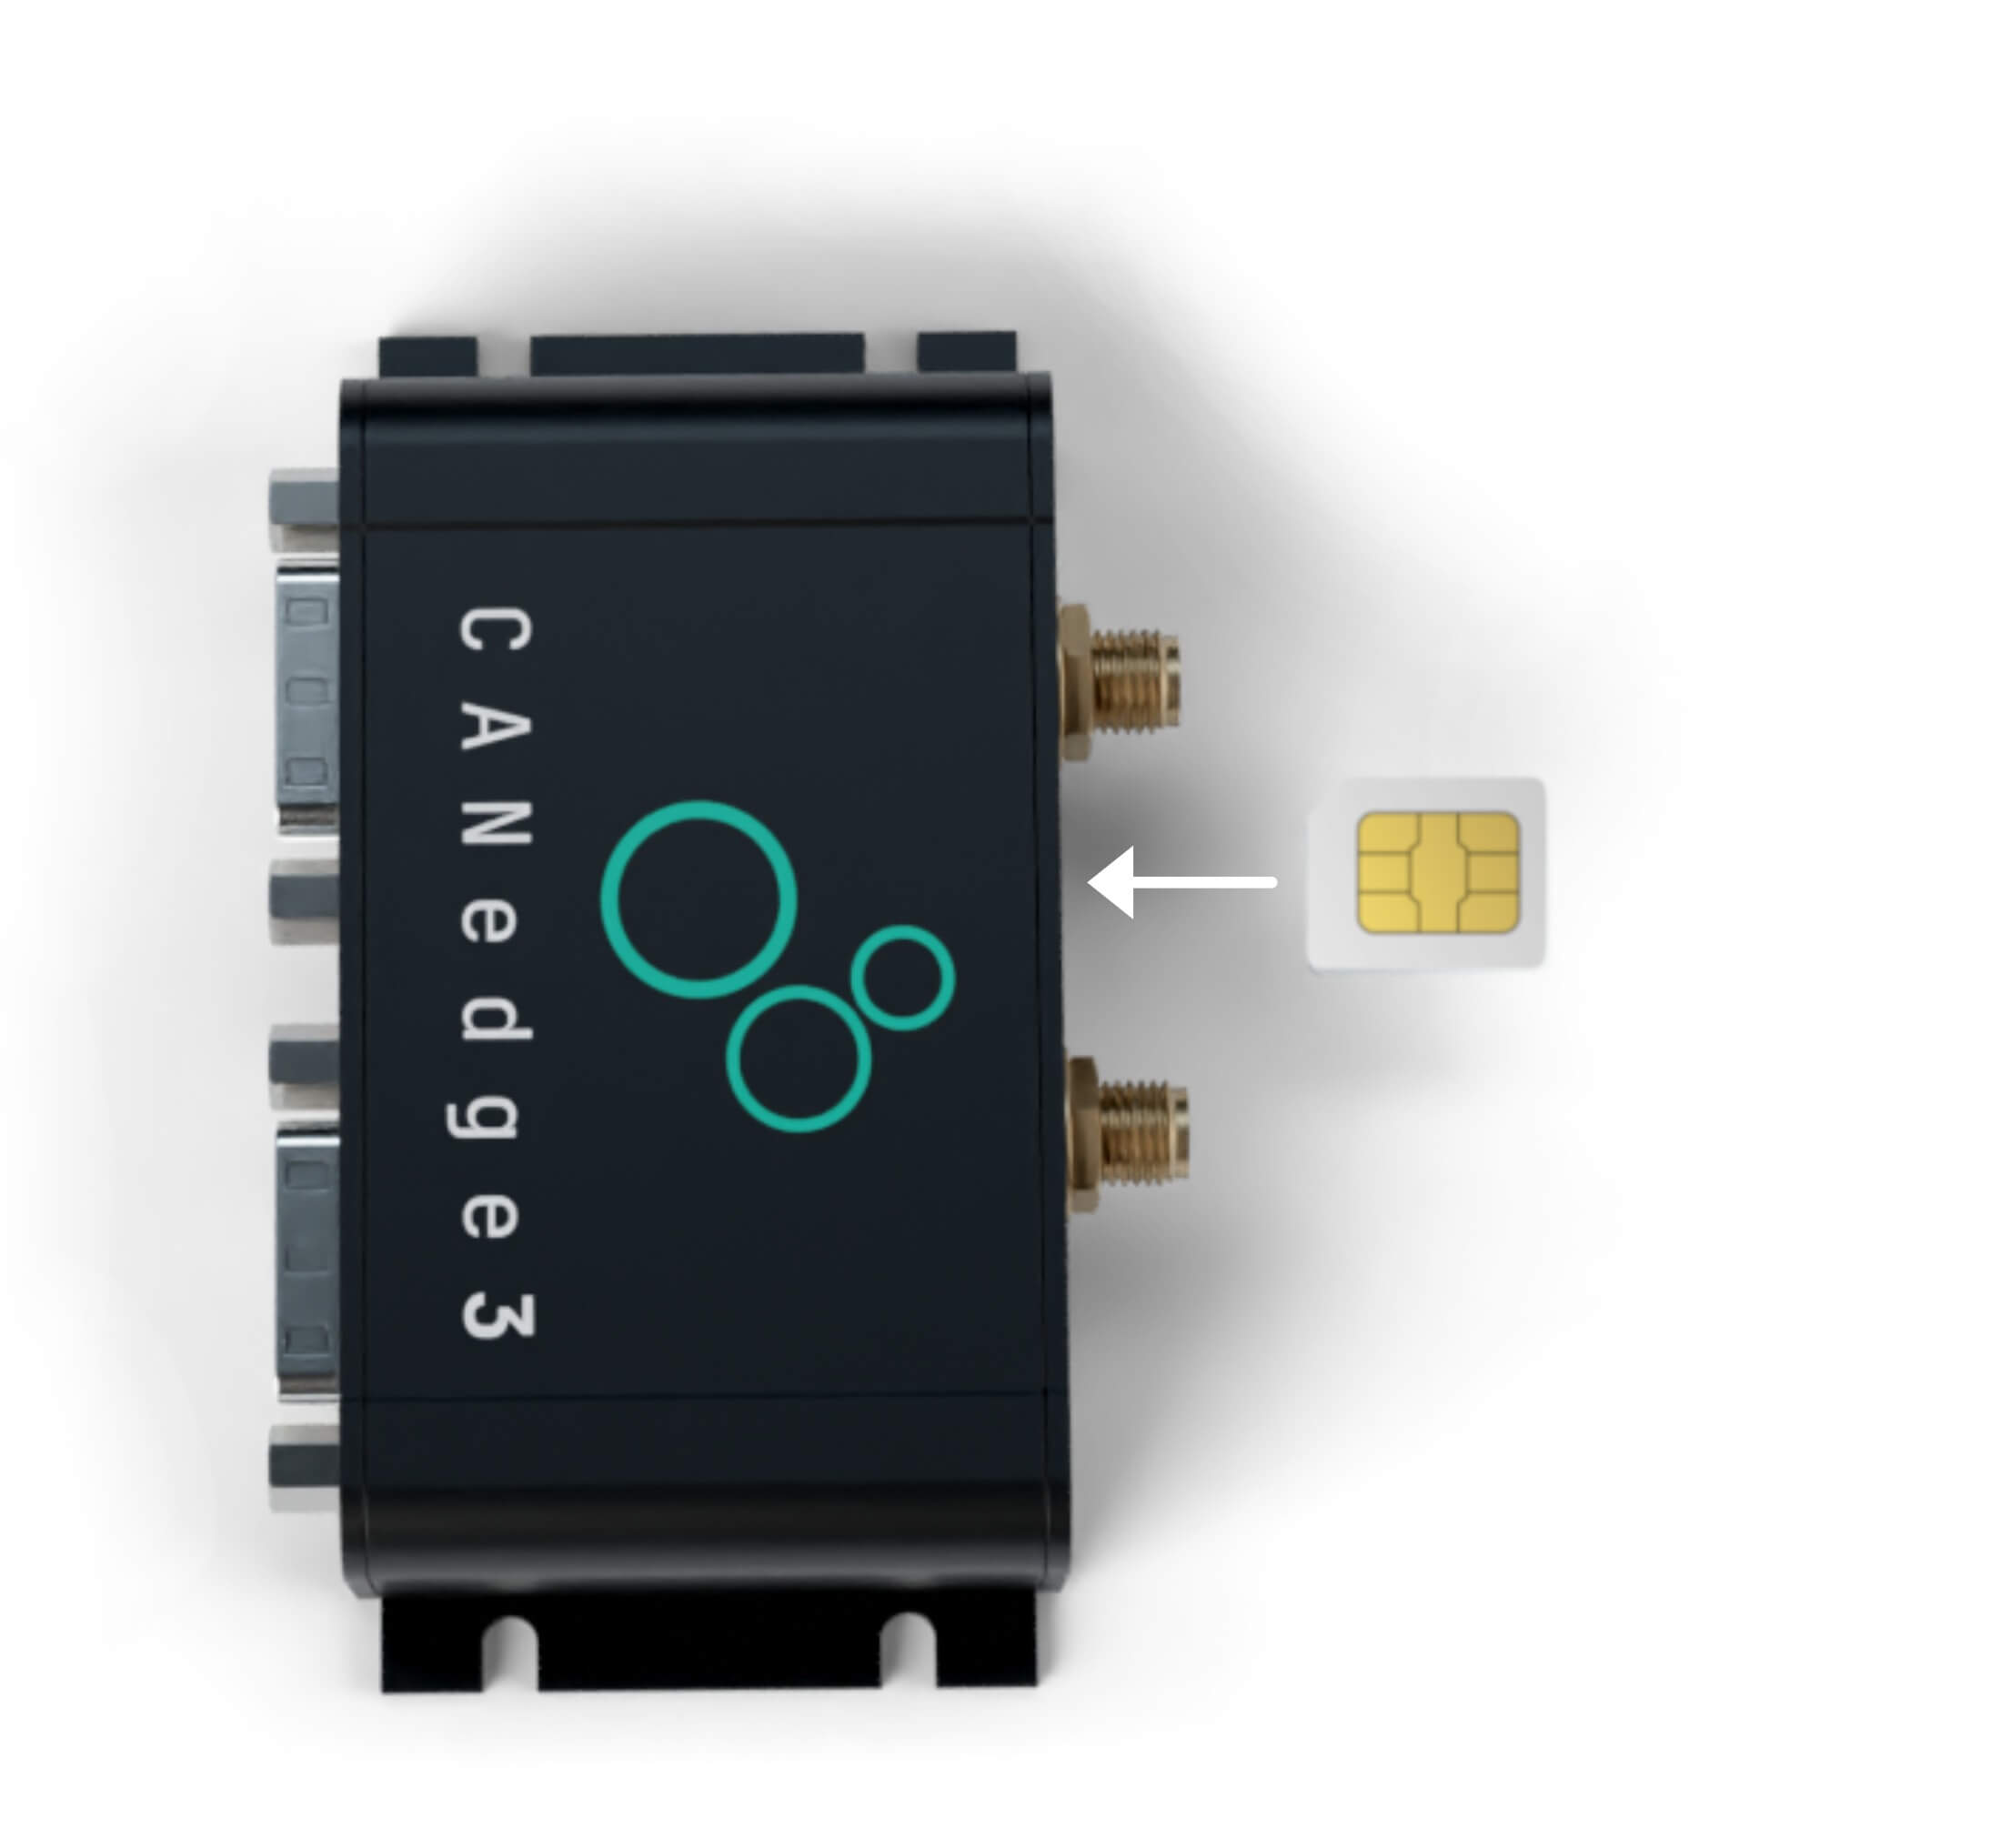
---
## AT&T SIM card registration
The CANedge3 is PTCRB and AT&T certified[4](#fn-certification). To use AT&T SIM cards in USA, you may need to register the IMEI of the device with AT&T.
If your device IMEI is not already registered in the AT&T portal, please follow below steps[5](#fn-periodic-upload):
1. Ensure your device uses firmware `01.08.01` (or newer)
2. Open your `device.json` from the SD and copy the values of the `id` and `cellular_imei` fields
3. Send the values to us by email via our [contact form](https://www.csselectronics.com/pages/contact-us) with subject `CANedge3 AT&T IMEI`
We will then ensure the IMEIs are uploaded through the AT&T platform to enable registration.
---
* **[1]** You should hear/feel a ‘click’ when the SIM is correctly inserted and it will be fully inside the device. The ‘cut corner’ should be facing the LTE antenna connector. A small tool (e.g. a toothpick) may be required to fully insert/eject the SIM card. If you are in doubt if the SIM is correctly inserted, you can check if the SIM card identifier, ICCID, shows up in the CANedge3 `device.json` field `cellular_iccid` after a power cycle with the SIM inserted. We strongly recommend to not use already-ejected nano SIM cards (even via nano-to-micro SIM card adapters) as these may get stuck within the SIM slot holder. This can cause damage to the device, which is not covered by the warranty
* **[2]** You can typically find your APN via an online search or via your SIM provider’s website. For some SIM cards no PIN is required (in this case leave the PIN field blank). Similarly, some SIM cards may work without entering the APN
* **[3]** The SIM slot ejection mechanism and interface may get damaged if a SIM is inserted incorrectly. Ensure that your SIM is inserted as per the instructions. Further, if your micro SIM has an extractable embedded nano SIM, we recommend to use a proper plastic micro SIM card adapter instead. In particular, do not insert a micro SIM in which the embedded nano SIM has been extracted and subsequently manually reinserted. Damage from incorrect SIM insertion is not covered by the warranty
* **[4]** The certifications assume the device is installed with an extension antenna (>20 cm from the device) and that the device is configured to behave reasonably. In particular, it is recommended to avoid very high frequency connect/disconnect events (e.g. from very small log file splits or high-frequency heartbeat/sync)
* **[5]** We will periodically upload all produced CANedge3 IMEI numbers to AT&T, but depending on timing your specific device IMEI may not yet be registered in the portal
# index.html.md
# AWS S3 - manual deployment
When you need to create an AWS S3 bucket and user, we strongly recommend to use our template approach. It is a fast method that results in a consistent deployment without errors.
However, if you wish to perform the steps manually, you can follow the guide below.
1. [Sign up](https://portal.aws.amazon.com/billing/signup#/start) for a free account
2. Log in and go to ‘Services/S3/Buckets’
3. Click ‘Create bucket’, add a name and select a nearby region
4. In your bucket go to ‘Permissions/CORS’ and paste [this JSON](https://canlogger1000.csselectronics.com/files/cors-config.json)
5. Go to ‘Services/IAM/Users’, click ‘Add users’, add a name and click ‘Next’
6. Select ‘Attach policies directly’, choose ‘AdministratorAccess’, then ‘Next’ and ‘Create user’
7. In the user, go to ‘Security credentials/Create access key’, select ‘Other’ then ‘Next’
8. Save your AccessKey, SecretKey
9. Also note your region (e.g. `us-east-1`) and endpoint (`http://s3.[region].amazonaws.com`)
### Example: CANedge3 AWS S3 server configuration
Below are example Configuration File details for an AWS S3 server ([editor view](../../configure-device/config-tools.md#ref-configuration-tools) and JSON):
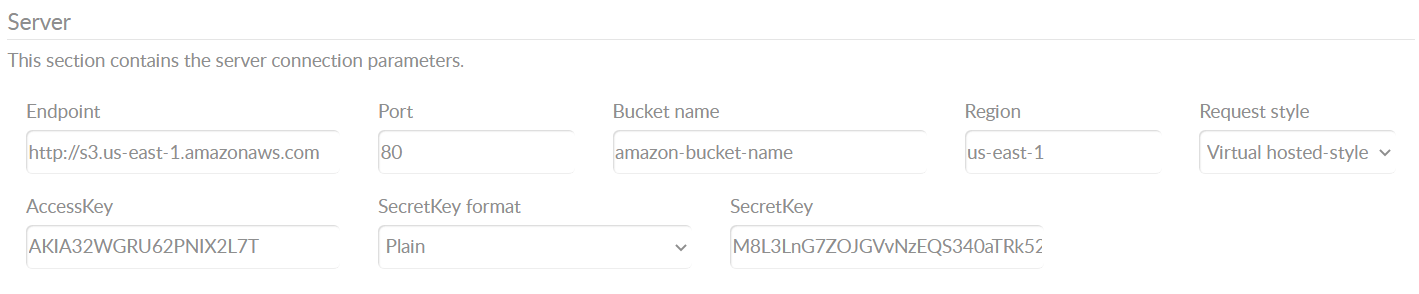
# index.html.md
# Cloud servers
The CANedge3 can be used with multiple cloud servers for convenience and scalability.
> ##### Table of Contents
>
> * [Amazon [recommended]](#amazon-recommended)
> * [Google](#google)
> * [Azure](#azure)
> * [Scaleway [EU sovereign cloud]](#scaleway-eu-sovereign-cloud)
> * [Other clouds](#other-clouds)
---
## Amazon [recommended]
1. [Sign up](https://portal.aws.amazon.com/billing/signup#/start) for a free AWS account and login
2. Open [this link](https://console.aws.amazon.com/cloudformation/home?#/stacks/create/review?templateURL=https://s3.eu-central-1.amazonaws.com/css-electronics-resources/stacks/create-s3-input-bucket-v1.4.0.json&stackName=canedge-stack) in a new tab[1](#fn-stack)
3. Specify a bucket name[2](#fn-1) and click ‘Create stack’ (wait 2 min)[3](#fn-delete)
4. Go to ‘Outputs’, copy the values into your Configuration File via the [editor](../../configure-device.md#ref-configure) and save it
5. Load the file in the [CANcloud](server-tools/cancloud-intro.md#ref-cancloud) login page and verify that you can access the S3 bucket
### Example: CANedge3 AWS S3 server configuration

### AWS S3 - user policies
The above process creates an IAM user with full S3 access to the created bucket.
For some use cases, you may want to replace this policy - or add separate users. For this purpose, we provide some example policies below (you should replace `your-bucket` with your bucket name). Make sure to fully test that the new policy works as expected.
1. [`S3-bucket-access`](/_static/files/transfer/s3-policies/aws-s3-user-policy-bucket-access.json): Only allows access to S3 calls for your bucket [DEFAULT]
2. [`S3-bucket-access-restrictive`](/_static/files/transfer/s3-policies/aws-s3-user-policy-bucket-access-restrictive_v3.json): As above, but only the S3 calls required by the CANedge3
3. [`S3-bucket-access-upload-only`](/_static/files/transfer/s3-policies/aws-s3-user-policy-bucket-access-upload-only_v2.json): As above, but only upload of files (disabling OTA support)
4. [`S3-bucket-access-read-only`](/_static/files/transfer/s3-policies/aws-s3-user-policy-bucket-access-read-only.json): Read-only access for your bucket [not for use on CANedge3]
---
## Google
1. [Sign up](https://cloud.google.com/products/storage/?authuser=0) for a free account (this requires your card details, but no charges are made)
2. Open the [canedge-google-cloud-terraform](https://github.com/CSS-Electronics/canedge-google-cloud-terraform) repository
3. Go through the ‘setup instructions’ to open your Cloud Shell and clone the repository
4. Go through step 1 (input bucket)
5. Copy the S3 details into your Configuration File via the [editor](../../configure-device.md#ref-configure) and save it
6. Load the file in the [CANcloud](server-tools/cancloud-intro.md#ref-cancloud) login page and verify that you can access the bucket
### Example: CANedge3 Google Cloud S3 server configuration
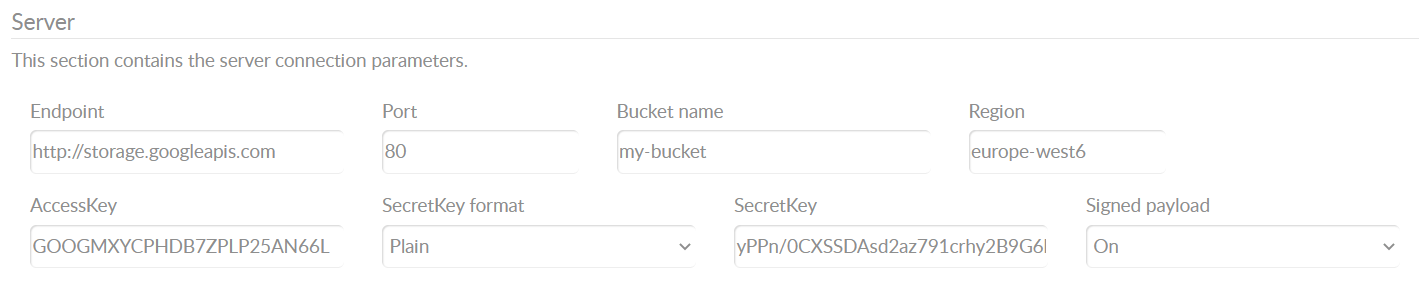
---
## Azure
Azure does not support S3 natively - but you can add a [Flexify S3 gateway](https://flexify.io/) for your Blob Storage container in 1 min. It is easy, secure and practically free[5](#fn-flexify-costs).
1. [Sign up](https://azure.microsoft.com/en-us/) for an Azure cloud account
2. Open the [canedge-azure-cloud-terraform](https://github.com/CSS-Electronics/canedge-azure-cloud-terraform) repository
3. Go through the ‘setup instructions’ to open your Cloud Shell and clone the repository
4. Go through step 1 (input container) and note down the output details incl. the SAS token
5. [Sign up](https://flexify.io/) for a free Flexify account and login (no credit card required)
6. In Flexify, go to ‘Data/Add storage account’, select Azure and add your token and container[4](#fn-flexify-warning)
7. Next, go to ‘Endpoints/New endpoint’ and attach your storage account
8. Use the `http://s3.flexify.io` endpoint for initial testing
9. Copy the S3 details into your Configuration File via the [editor](../../configure-device.md#ref-configure) and save it
10. Load the file in the [CANcloud](server-tools/cancloud-intro.md#ref-cancloud) login page and verify that you can access the S3 bucket
### Example: CANedge3 Azure-Flexify Cloud S3 server configuration
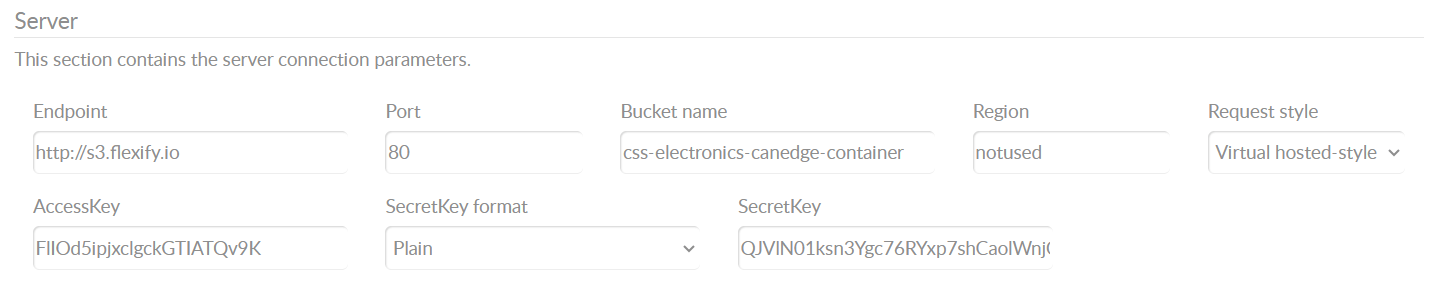
#### NOTE
Once you’ve verified the initial connection, select the endpoint with the most nearby region[6](#fn-region-azure). Note that for the regional Flexify endpoints, you must [enable TLS to connect](https/cloud.md#ref-cloud-tls)
#### NOTE
You can also self-host Flexify in your Azure account via [this guide](https://flexify.io/how-to-run-amazon-s3-apps-on-azure) [advanced][7](#fn-flexify-selfhosted)
---
## Scaleway [EU sovereign cloud]
If you prefer to use a 100% EU sovereign cloud, we recommend Scaleway[9](#fn-clouds):
1. [Sign up](https://www.scaleway.com/en/) for an account
2. Click ‘Create/Object Storage Bucket’ in the top menu
3. Select a [region](https://www.scaleway.com/en/docs/object-storage/quickstart/#how-to-create-a-bucket) and bucket name (use defaults for the rest) and click ‘Create bucket’
4. Click your account icon and select ‘API Keys’
5. Click ‘Policies/Create policy’ with name `s3-access`
6. In ‘Access to resources’ select `default` and click ‘Validate’
7. Select ‘Storage/ObjectStorageFullAccess’ and click ‘Validate’ and ‘Create policy’
8. In the IAM overview click ‘Applications/Create application’ with name `canedge`
9. Attach the `s3-access` policy and click ‘Create application’
10. In the IAM overview click ‘API keys/Generate an API key’
11. Select the `canedge` application, select ‘Yes, …’, click ‘Generate API key’ and store the details
12. Copy the S3 details into your Configuration File via the [editor](../../configure-device.md#ref-configure) and save it
### Example: CANedge3 Scaleway S3 server configuration
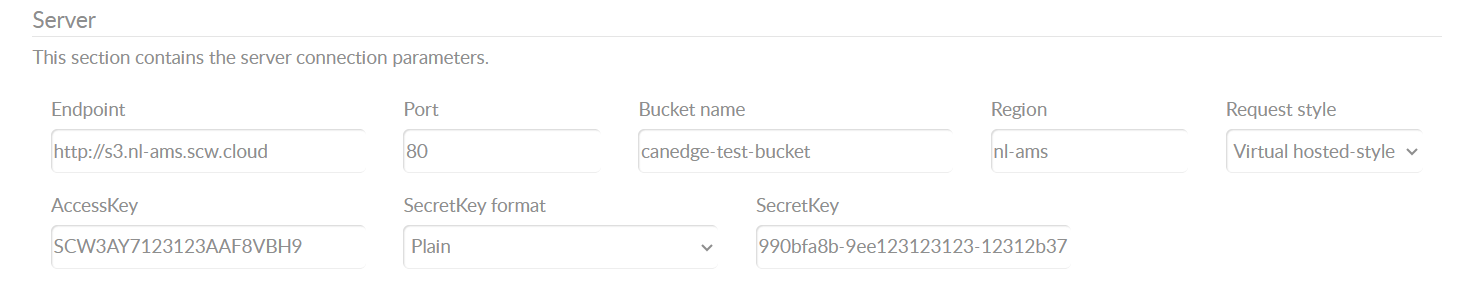
### Update bucket CORS to use CANcloud (optional)
1. Download [S3 Browser](https://s3browser.com/download.aspx) and add your Scaleway account as an ‘S3 Compatible Storage’
2. Select your account, right-click your bucket and select ‘CORS Configuration’
3. Copy/paste [`this CORS XML`](/_static/files/transfer/clouds/scaleway/cors-scaleway-cancloud.xml) and click ‘Save changes’
4. Verify that you can now login to your S3 bucket via [CANcloud](server-tools/cancloud-intro.md#ref-cancloud)
### Restrict bucket access (optional)
If you set up multiple buckets, you can follow below steps to manage bucket access:
1. In ‘Storage/Object Storage’ click the ‘…’ next to your bucket and ‘Create bucket policy’
2. Add the name `bucket-policy` and select ‘JSON editor’
3. Download [`this bucket policy`](/_static/files/transfer/clouds/scaleway/scaleway-bucket-policy.json) and update the bucket name, application ID and user ID[8](#fn-scaleway-ids)
---
## Other clouds
You can also use other S3 clouds like [Wasabi](https://wasabi.com/) or [DigitalOcean](https://www.digitalocean.com/products/spaces/). Setting these up is similar to e.g. AWS and hence not described in detail here. Note that if you aim to setup e.g. automated data processing, data lakes or dashboards, we recommend using Amazon S3[9](#fn-clouds).
---
* **[1]** The link opens an AWS CloudFormation ‘quick-create’ stack. This is a concept that allows for deploying pre-defined resources within your AWS account. The linked template creates an S3 bucket and a new IAM user with full access to the S3 bucket (but nothing else). The template also adds the CORS policy required for you to access the S3 bucket via CANcloud. If you are not the AWS account owner, you can forward the guide to the relevant persons. If you prefer a more ‘manual’ setup, see our [original step-by-step guide](aws-s3-manual-setup.md#ref-aws-s3-manual)
* **[2]** The bucket will be created in the region that is currently active in your AWS console, which will generally be recommended if your deployment is near your own location. You can optionally change the region by changing this in the AWS console upper right corner. Selecting a region near your device deployment is key to ensuring fast data transfer rates
* **[3]** We recommend to keep the AWS stack, as it makes it quicker to later on deploy e.g. automation workflows. If you do delete it, however, your deployed S3 input bucket and IAM user remain as-is
* **[4]** Flexify may give a warning regarding invalid credentials when you attach the storage account, but this can be ignored
* **[5]** Flexify charges an insignificant 0.04$/GB uploaded/downloaded (zero fixed fees). Your account will start with 20$ free credits (~500 GB data) without the need for adding a credit card up front. You can add more credits as you progress
* **[6]** If you are e.g. in EU and only have US based Flexify endpoints available, consider creating an Azure Blob Storage container in a US region as well to minimize the total latency for the CANedge
* **[7]** If possible, we recommend using the Flexify service option as it is easy to set up. However, if you strictly need to self-host Flexify you can follow the guide. Note, however, that this setup is much more advanced and that we cannot support on e.g. enabling TLS on self-hosted Flexify gateways. If you use the self-hosted setup, ensure you select ‘path-style’ in the CANedge S3 configuration
* **[8]** To find the Scaleway user/app IDs click your account icon and select ‘IAM’. Select your user and click ‘Copy ID’ to get the ``. Next, navigate to your application and copy the ID as your ``
* **[9]** We enable plug & play automation work flows for the top 3 clouds (Amazon, Google Cloud, Azure) with particular support for Amazon. This is useful if your use case requires automated data processing, the creation of data lakes and/or dashboard visualization. Here we strongly recommend to use Amazon S3, though Google Cloud and Azure can also be used. However, using other clouds are not recommended in this case as you will need to setup any automation from scratch on your own
# index.html.md
# Self-hosted server
> ##### Table of Contents
>
> * [Setting up a local MinIO server](#setting-up-a-local-minio-server)
> * [Using the MinIO console](#using-the-minio-console)
> * [Using the MinIO client tool](#using-the-minio-client-tool)
> * [Port forwarding your MinIO server](#port-forwarding-your-minio-server)
---
## Setting up a local MinIO server
Below we outline how you can set up a **local server** on your Windows PC:
1. Update the host PC firewall to allow traffic on port 9000 (see [video](https://canlogger1000.csselectronics.com/img/update-firewall-settings.mp4))
2. Download the MinIO S3 server ([Windows](https://canlogger.csselectronics.com/files/minio/windows/2023-04-20T17-56-55Z/minio.exe), [Linux AMD64](https://canlogger.csselectronics.com/files/minio/linux-amd64/2023-04-20T17-56-55Z/minio))[1](#fn-1)
3. Open the command prompt in the folder, paste in the below and hit enter
```text
SET MINIO_ROOT_USER=YourAccessKey
SET MINIO_ROOT_PASSWORD=YourSecretKey
minio.exe server C:\DATA --console-address ":9001"
```
1. Open the ‘MinIO console’ by entering the *console address* in your browser (port `9001`)
2. Login to the console, go to “Buckets” and create a new bucket (default settings)
3. You now have your endpoint, port (`9000`), bucket and credentials[2](#fn-2)
4. Check if you can login via [CANcloud](server-tools/cancloud-intro.md#ref-cancloud) on *the host PC* (using Firefox[3](#fn-3))
5. Check if you can login via CANcloud on *another PC* on the network (using Firefox[3](#fn-3))
#### NOTE
If you do not update your firewall settings, the CANedge will be unable to connect
#### NOTE
It is strongly recommended that the host PC/system is continuously active to ensure that the self-hosted MinIO S3 server is always available
### Creating a bat file
If you later need to start this server again, you can optionally create a `*.bat` file with the lines from earlier, which you can then double-click to start your server. This bat file can also be setup to run when your machine boots.
---
## Using the MinIO console
MinIO supports a powerful ‘console’ view that offers a graphical user interface for controlling your MinIO S3 settings and monitoring your data flow. This can be viewed as a ‘server management tool’, while CANcloud can be viewed as a ‘device & data management tool’.
---
## Using the MinIO client tool
The MinIO Client tool lets you perform various operations on your MinIO server via the command line. It provides a modern alternative to UNIX commands like `ls`, `cat`, `cp`, `mirror`, `diff` etc.
To get started with this tool, follow the below steps:
1. Download the [MinIO client](https://min.io/download#/windows)
2. Open your command line and enter the below (`` is a nickname for your server)
`mc config host add `
3. You can now e.g. create a bucket on your server as follows:
`mc mb /`
### Example
Adding a HTTP trace for your MinIO server:
```text
mc config host add myserver http://192.168.1.179:9000 YourAccessKey YourSecretKey
mc mb myserver/mybucket
mc admin trace myserver
```
For a full list of MinIO Client commands, see the [MinIO Client quickstart](https://docs.min.io/docs/minio-client-quickstart-guide.html).
---
## Port forwarding your MinIO server
Below we describe how to port forward your MinIO S3 server to access it via the internet.
#### WARNING
If you’re new to servers, we recommend setting up an [AWS S3 cloud](clouds.md#ref-clouds). This way you do not have to consider port forwarding, firewalls etc. Once your setup is in place, you can always switch to a MinIO server later via an over-the-air update
To port forward your MinIO S3 server, follow the below steps:
1. Log into your router settings (often via `http://192.168.0.1`)
2. Go to the Port Forwarding section (often under WAN or Advanced)
3. Create a new port forward entry (IPv4)
4. In the ‘Local IP’, add the local network MinIO endpoint (e.g. `192.168.0.178`)
5. In the local start/end port, add the MinIO endpoint port (e.g. `9000`)
6. Use the same MinIO port for the external start/end port (if relevant)
7. Find your public WAN IP by googling “My IP” (e.g. `176.21.122.154`)
8. Combine your public WAN IP with the MinIO port (e.g. `176.21.122.154:9000`)
9. Verify that you can connect to the server via e.g. your smartphone or other external network
#### WARNING
The basic setup is intended for small-scale use. For use cases involving a larger number of CANedge3 devices, the setup may need to be modified for scalability
---
* **[1]** The download links are for release `2023-04-20T17-56-55Z`, which we use as basis for this guide. For later releases and e.g. other Linux builds, see the [release page](https://dl.min.io/server/minio/release/)
* **[2]** MinIO provides multiple IP endpoints - for running a local server setup, use the one corresponding to your router’s IP structure (see ‘Default Gateway’ when running ipconfig in the command prompt) - e.g. 192.168.0.178. The port should be `9000` when you log in via CANcloud or configure your CANedge3. Once you’re done testing, you can update your SecretKey e.g. via [Norton’s password generator](https://my.norton.com/extspa/passwordmanager?path=pwd-gen). You can then update it by using `SET MINIO_ROOT_PASSWORD=YourNewSecretKey`
* **[3]** Chrome recently blocked access to non-TLS endpoints. By default, your MinIO S3 server is setup to run without TLS enabled. This means that if you wish to login to your MinIO S3 server via CANcloud using Chrome, you will need to enable TLS on your MinIO server and CANedge3 devices (as per our separate guide). Since TLS is an advanced topic, we recommend that you initially use Firefox to login via CANcloud, as Firefox does not block access. If you wish to login via Chrome on the *host PC*, you can also download and unzip the [latest CANcloud release](https://github.com/CSS-Electronics/cancloud/releases) and open the `index.html` file via Chrome. Finally, you can use Chrome with a non-TLS MinIO server if you have administrative access as outlined [here](https://developer.chrome.com/blog/private-network-access-update/#policies) (though this is an advanced topic)
# index.html.md
# S3 tools
The CANedge3 uploads files to an S3 server. This enables the use of any S3 compatible tool/API in managing files on the server - including below:
1. [CANcloud](server-tools/cancloud-intro.md#ref-cancloud) - manage your S3 server log files & devices directly from your browser
2. [Mount S3 as local drive](server-tools/other-s3-tools.md#ref-other-s3-tools) - map your S3 server as a local drive for easier access
3. [OTA batch tool](server-tools/s3-ota-batch-manager.md#ref-ota-batch-manager) - batch-update your Configuration Files and Firmware over-the-air
4. [S3 API](server-tools/s3-api.md#ref-s3-api) - automate e.g. log file processing and over-the-air updates via the S3 API
#### NOTE
Note that the above tools are 100% optional. You can use any other S3 compatible tools to manage your server (e.g. MinIO client, AWS CLI, …)
# index.html.md
# Tips & tricks
Below we’ve collected tips & tricks on the remote transfer based on user experiences:
> ##### Table of Contents
>
> * [Test your setup](#test-your-setup)
> * [Optimize your file size](#optimize-your-file-size)
> * [Compare logging vs. upload rates](#compare-logging-vs-upload-rates)
> * [Match file split size vs. your use case](#match-file-split-size-vs-your-use-case)
> * [Encrypt your passwords](#encrypt-your-passwords)
> * [Use the CANcloud status dashboard](#use-the-cancloud-status-dashboard)
> * [Avoid OTA update confusion](#avoid-ota-update-confusion)
> * [Use OTA updates carefully](#use-ota-updates-carefully)
---
## Test your setup
We strongly recommend that you familiarize yourself with the CANedge3 before you deploy it in the field. In particular, make sure to test your configuration (see also below points) and ensure that you get familiar with over-the-air updates of configuration and firmware.
---
## Optimize your file size
We strongly recommend that you reduce your file size as per our [step-by-step guide](../../record-data/reduce-file-size.md#ref-reduce-file-size). This reduces your server storage costs and data processing time. Further, if you’re uploading via 3G/4G, it can significantly reduce your data transfer costs. In most use cases, you can achieve a 90% reduction in file size without loosing relevant data insight.
---
## Compare logging vs. upload rates
The amount of data logged by the CANedge3 can differ dramatically. In most applications the unfiltered log rate will be about 0.5-1.5 MB/minute.
---
## Match file split size vs. your use case
The CANedge3 does not support resumable file uploads. This means that if a large file transfer fails, the device will have to start from scratch. In use cases with constant and stable connectivity this is typically not an issue. However, if data is uploaded periodically (e.g. when a vehicle returns to a specific area), it is recommended to use a small split size - e.g. 5 MB.
On the other hand, we do not recommend to use e.g. 10-30 second split sizes. While it enables “near real-time upload” it will cause large overheads on your data and post processing will be less efficient. If you do decide to use very small split sizes, we recommend to use event based data processing (e.g. AWS Lambda functions) to process each file as soon as it gets uploaded.
---
## Encrypt your passwords
We recommend to encrypt your passwords before deploying the unit in the field. Without this, others can access your sensitive passwords by extracting your device SD card. However, make sure to test your connection with the encryption enabled to ensure you perform the change correctly.
For batch encryption we recommend using the OTA batch manager tool.
---
## Use the CANcloud status dashboard
It’s generally useful to monitor your device status via the CANcloud status dashboard, e.g. to watch out for bottlenecks, unexpected delays in your device heartbeats or issues with declining SD card capacity (indiciating an issue with your log rate vs. upload rate).
---
## Avoid OTA update confusion
Using over-the-air updates can be a bit confusing at first. In particular, note that once your CANedge3 has connected to your server, it will upload the Configuration File to the device folder. If you then manually update the Configuration File on the SD card of the device, you’ll experience that the changes you made get overwritten. This is because the CANedge3 recognizes that there is a different Configuration File on your server - which triggers an over-the-air update. In other words this is working as intended - but may be confusing the first time.
---
## Use OTA updates carefully
Over-the-air updates are powerful, but they should be used carefully. Performing an update can lead to the CANedge3 getting disconnected from your server, e.g. if you tweak a setting without knowing the full extent of what effect this has.
In particular, be careful in changing the following settings over-the-air:
1. Real-time clock: The device requires that the RTC is synced at all times to communicate with your server. Therefore we strongly recommend to keep the Network RTC sync enabled at all time and avoid modifying the RTC Adjustment field
2. Split size: Changing the split size to a large file size can block the data upload if you e.g. have an unstable connection as explained further above.
3. Connect: Most of the `connect` section is sensitive. Fully understand each field before changing anything. For details, hover fields in CANcloud or review the field in the CANedge Docs
# index.html.md
# Cloud server TLS
The CANedge3 lets you upload data via HTTP or HTTPS. HTTP is simpler to setup/maintain, but if security is a priority you can use HTTPS data transfer.
#### NOTE
HTTPS is an advanced topic. Ensure that your HTTP upload works first and read the S3 security section in the CANedge3 Docs before proceeding. The CANedge3 Docs also describe bundled certificates and over-the-air certificate updates
#### WARNING
Make sure to have physical access to your CANedge3 when testing HTTPS. Note also that enabling TLS may reduce your upload speed
#### WARNING
Note that the default root CA may change for a cloud endpoint. For production setups we strongly recommend using a custom endpoint & certificate to ensure full control
> ##### Table of Contents
>
> * [Ready-to-use TLS certificates (AWS, Google, Azure, Scaleway)](#ready-to-use-tls-certificates-aws-google-azure-scaleway)
> * [Manually download TLS certificate (other clouds)](#manually-download-tls-certificate-other-clouds)
> * [Custom domain & certificate](#custom-domain-certificate)
## Ready-to-use TLS certificates (AWS, Google, Azure, Scaleway)
Here we describe how to enable TLS for AWS, Google Cloud, Azure-Flexify[3](#fn-azure-flexify) and Scaleway:
1. Download the relevant pre-built from below to your device SD card root
2. Update your Configuration File endpoint with `https://` and port `443`[1](#fn-2)
3. Test your connectivity before final deployment[2](#fn-3)
[`AWS`](/_static/files/transfer/https-certificates/aws/certs_server.p7b) | [`Google Cloud`](/_static/files/transfer/https-certificates/google/certs_server.p7b) | [`Azure-Flexify`](/_static/files/transfer/https-certificates/flexify/certs_server.p7b) | [`Scaleway`](/_static/files/transfer/https-certificates/scaleway/certs_server.p7b)
---
## Manually download TLS certificate (other clouds)
1. Copy your S3 server `[endpoint]/[bucket]` into your browser. For AWS, this could e.g. be:
`https://s3.us-east-1.amazonaws.com/canedge-test-bucket`
2. In Chrome, click the lock-icon next to the URL
3. Go to the certificate details page and select the top root certificate
4. Export the single certificate as `.crt` and open the file
5. Go to the Details tab and verify that it is an `RSA` type (not e.g. `ECC`)
6. Rename it to `certs_server.p7b`[1](#fn-2) and save the file to the root of your device SD
7. Update the Configuration File to use `https://` and port `443` in your server details
---
## Custom domain & certificate
As outlined above, if you wish to use a cloud server endpoint like e.g. AWS S3, you can use the default certificate to enable TLS. This can be OK for small scale, local setups and tests.
For production setups and large scale applications, it is recommended that you ensure full control over the certificate chain as the cloud server provider may decide to change the root CA without notice. While rare, it is a risk. To avoid this, you can use a custom domain as your end point and enable TLS by importing your preferred certificate. This is an advanced topic and we recommend involving technical staff from your cloud server provider and/or your company.
---
* **[1]** When updating the Configuration File of an already-connected CANedge, ensure that you’re updating the S3 Configuration File rather than the SD. Otherwise the SD changes will be over-written by an OTA update when the device connects to S3. Alternatively, delete the S3 Configuration File before making changes to the SD Configuration File
* **[2]** Note that deployment with our TLS bundle is still subject to the risk of a change in the default root CA - so make sure to check if any CA changes are scheduled and deploy at your own risk
* **[3]** The Azure-Flexify certificate assumes that you are running the integration as per our [guide](../clouds.md#ref-clouds) (not via a self-hosted VM in Azure)
# index.html.md
# MinIO server TLS
The CANedge3 lets you upload data via HTTP or HTTPS. HTTP is simpler to setup/maintain, but if security is a priority you can use HTTPS data transfer.
#### NOTE
HTTPS is an advanced topic. Ensure that your HTTP upload works first and read the S3 security section in the CANedge3 Docs before proceeding. The CANedge3 Docs also describe bundled certificates and over-the-air certificate updates
#### WARNING
Make sure to have physical access to your CANedge3 when testing HTTPS. Note also that enabling TLS may reduce your upload speed
If you run a MinIO server, TLS is disabled by default and you’ll be using a `http://` endpoint. To enable TLS on your server, you can follow the [MinIO quickstart guide](https://docs.min.io/docs/how-to-secure-access-to-minio-server-with-tls.html).
Below we use one of the examples from their guide (OpenSSL with IP address on Windows):
1. Download and extract [OpenSSL](https://www.openssl.org/source/)
2. Create a new text file named `openssl.conf` in the folder with the `openssl.exe` file
3. Paste below into `openssl.conf`, update `IP.1` to your MinIO endpoint (excl. `http://` and port):
```text
[req]
distinguished_name = req_distinguished_name
x509_extensions = v3_req
prompt = no
[req_distinguished_name]
C = US
ST = VA
L = Somewhere
O = MyOrg
OU = MyOU
CN = MyServerName
[v3_req]
subjectAltName = @alt_names
[alt_names]
IP.1 = 127.0.0.1
```
4. Open the command prompt in the folder and enter the below:
> ```text
> openssl req -x509 -nodes -days 2730 -newkey rsa:2048 -keyout private.key -out public.crt -config openssl.conf
> ```
1. Copy the resulting `private.key` and `public.crt` files into `C:\Users\[your_user_name]\.minio\certs`
2. Rename the `public.crt` to `certs_server.p7b`[1](#fn-2) and copy it to the root of your device SD card
3. Update your device Configuration File to use `https://` in front of the MinIO IP endpoint
Test if the certificate is loaded in the `device.json` file and if the CANedge3 correctly uploads data. To avoid browser warnings, you can [install the self-signed certificate](self-signed-pc.md#ref-self-signed-pc) on your PC.
---
* **[1]** Before renaming the certificate, ensure that your File Explorer [displays file extensions](https://support.winzip.com/hc/en-us/articles/115011457948-How-to-configure-Windows-to-show-file-extensions-and-hidden-files)
# index.html.md
# Install self-signed certificates on PC
### Install self-signed certificate on PC (Windows)
If you enable TLS on your S3 server and your CANedge3 via a self-signed certificate, your browser/PC will typically not recognize the self-signed certificate. Hence you’ll see warnings in your browser - and e.g. the MinIO client and our OTA batch manager tool may not work.
To solve this, you can add the certificate to your PC’s trusted list via the below steps:
1. Open the command prompt from your start menu (type `cmd` then enter), then enter `mmc`
2. In the Microsoft Management Control window, open `File/Add/Remove Snap-in...`
3. From the list select `Certificates`, then Add. Select `Computer account`, Next and Finish
4. In the main view, right-click `Trusted Root Certification Authorities` and click `All Tasks/Import`
5. Browse to your `public.crt` self-signed certificate and add go to Finish
6. Verify that your browser no longer warns you when accessing the TLS-enabled MinIO server
---
### Install self-signed certificate on PC (Linux - tested with Ubuntu 19.04)
1. Create a new certificate directory (e.g. `s3_cert`):
`$ sudo mkdir /usr/local/share/ca-certificates/s3_cert`
2. Copy the public server certificate to the new directory:
`$ sudo cp public.crt /usr/local/share/ca-certificates/s3_cert`
3. Load the new certificate:
```text
$ sudo update-ca-certificates
Updating certificates in /etc/ssl/certs...
1 added, 0 removed; done.
Running hooks in /etc/ca-certificates/update.d...
done.
```
# index.html.md
# CANcloud - manage devices & log files
[About](https://www.csselectronics.com/screen/page/cancloud-telematics-platform) |
[Playground](https://canlogger.csselectronics.com/cancloud-demo/#/)
---
[CANcloud](https://canlogger.csselectronics.com/cancloud/#/-telematics-platform/language/en) is an open source browser tool for managing your CANedge3 devices & log files.
Open CANcloud
In this section we outline the basic functionality of CANcloud. Note that this is an optional tool for browsing your S3 data - see e.g. also our guide on [mounting your S3 server](other-s3-tools.md#ref-other-s3-tools) as a local drive.
> ##### Table of Contents
>
> * [Logging into CANcloud](#logging-into-cancloud)
> * [Managing files](#managing-files)
> * [Status dashboard](#status-dashboard)
> * [Over-the-air updates (device-by-device)](#over-the-air-updates-device-by-device)
> * [OTA batch manager](#ota-batch-manager)
> * [Device meta data & image](#device-meta-data-image)
> * [Start Time vs. Last Modified (S3)](#start-time-vs-last-modified-s3)
> * [Hosting CANcloud yourself](#hosting-cancloud-yourself)
---
## Logging into CANcloud
To log into CANcloud, simply go to the [login page](https://canlogger.csselectronics.com/cancloud/#/) and add your S3 server details.
#### NOTE
You can use ‘Load from config’ to load the login details from your CANedge Configuration File
* If using a MinIO IP endpoint include the port (e.g. `http://192.168.0.174:9000`)
* If logging into a MinIO server without TLS, open CANcloud via [this link](http://canlogger.csselectronics.com/cancloud/#/) instead (using `http://`)
---
## Managing files
When your CANedge3 connects to your server, it’ll push files with S3 object names as below:
```text
[serialno]/[config-XX.YY.json]
[serialno]/[schema-XX.YY.json]
[serialno]/[device.json]
[serialno]/[session]/[split]-[epoch].MF4
```
In CANcloud, the `/` is presented as a folder structure, providing an easy overview of your data. Further, connected devices are automatically listed in the left sidebar.
* If you download a file in CANcloud, the `/` becomes a `_`
* If you upload a file in CANcloud, any `_` in the filename becomes a `/`
Example: You can upload a local file `firmware.bin` to a device folder `312AC432` in two ways:
1. Navigate to the folder `312AC432` in CANcloud and upload the file
2. Rename the file to `312AC432_firmware.bin` and upload it from the `Home` folder
---
## Status dashboard
The CANcloud status dashboard helps you keep track of your connected devices:
* Check when each device last connected to your server (based on the Device File)
* Check the Firmware version of each device and whether the Configuration File is synced
* Check the free storage on your device SD cards (based on the Device File)
* View various overviews of the amount of data uploaded by your devices[3](#fn-2)
You can access the CANcloud status dashboard via the upper right menu.
---
## Over-the-air updates (device-by-device)
### Configuration over-the-air
CANcloud uses the config editor tool for quick configuration of connected devices:
1. Click ‘Configure’ next to a device in the sidebar to open the editor
2. This will auto-load the uploaded Rule Schema and Configuration File
3. You can now make edits, review changes and submit to S3 to perform an update over-the-air
### Firmware over-the-air
You can also perform firmware updates over-the-air through CANcloud.
- To perform a `PATCH` update (e.g. from `01.07.01` to `01.07.03`) simply upload the `firmware.bin` to the device folder via the CANcloud upload button
- To perform a `MAJOR` / `MINOR` update (e.g. from `01.07.03` to `01.08.01`), first add a valid Configuration File in the device folder for the new firmware and then upload the `firmware.bin`
For more on this see the CANedge Docs (Configuration/Connect).
#### NOTE
Over-the-air updates are powerful, but require caution. Pushing e.g. the wrong S3 details will disconnect the device until you manually reconfigure it by extracting the SD
To update many devices in one operation, see the [OTA batch manager](#ref-cancloud-ota-batch) below.
---
## OTA batch manager
The OTA batch manager lets you deploy an update across your entire device fleet in one operation. You can access it via the upper right menu.
1. Load an update: A full/partial Configuration File, a `firmware.bin` or a TLS certificate bundle
2. Select the target devices in the device table (incompatible devices cannot be selected)
3. Review the batch changes and submit to S3
Each device is evaluated individually against its own Rule Schema - and re-validated on fresh data immediately before each update is written. The device table lets you search/sort your fleet (e.g. by last heartbeat, firmware or config sync state).
#### NOTE
Test an update on a single device first - once verified, you can deploy it across larger batches
### Example 1: Update partial configs across your fleet
You may want to change e.g. the log file split size or filters across a set of devices - without altering other settings. To do so, simply make the changes in the config editor of one device, review the changes and transfer them to the OTA batch manager. The transferred partial config contains only your edits, letting you deploy these across the relevant devices - all other settings are preserved per device[1](#fn-update-risk).
### Example 2: Rotate passwords across your fleet
To quickly update passwords for a batch of devices, add the updated plain text passwords in CANcloud’s config editor of one device (setting the relevant fields to plain instead of encrypted), then transfer the partial config to the OTA batch manager. Here, you can enable ‘Encrypt passwords’ as part of the deployment - the new passwords are then encrypted separately for each device using the device’s own public key, ensuring that no unencrypted passwords are deployed on devices in the field.
### Example 3: Update firmware across your fleet
Updating the firmware of multiple devices can be a complex process - in particular if the firmware update also requires migrating the Configuration Files from an older schema revision. With the OTA batch manager, you simply upload the new `firmware.bin` and select the relevant devices (only compatible devices can be selected). The manager automatically ensures that the Configuration File of each device is migrated (if required) before the firmware update is performed.
### Example 4: Update TLS certificates
If you need to update TLS certificates over-the-air, you can load the new `certs_server.p7b` bundle via the OTA batch manager and deploy it across relevant devices. If you are ‘transitioning’ from an older certificate to a new one, make sure your bundle includes both certificates to ensure devices can connect both before and after the update.
---
## Device meta data & image
CANcloud automatically displays meta data from your uploaded Device File. In particular, the `log_meta` field is displayed on the device page and in the sidebar (where it is searchable).
You can add a device image by uploading an image file named `image.jpg` or `image.png`.
#### NOTE
You can also hover files/folders to show info based on S3 object meta data[2](#fn-1)
---
## Start Time vs. Last Modified (S3)
CANcloud will display the ‘Start Time’ of uploaded log files, reflecting the 1st timestamp of each log file. It will also display the ‘Last Modified (S3)’ timestamp, reflecting when the log file was uploaded. Both can be very useful in browsing your data.
---
## Hosting CANcloud yourself
We host the latest version of CANcloud [here](https://canlogger.csselectronics.com/cancloud/#/), letting you easily log into your server.
However, you may want to host your own version of the tool for various reasons:
* To customize colors/logos to match your company branding
* To add custom functionality, building your own version
* To control the URL yourself for e.g. providing to end users
To host your own version, simply get the latest release and unzip it on your web server (*not* your S3 bucket). You can modify all basic CSS properties and logo files without building a new version.
For more advanced customization, you can of course also fork the source code.
[Source Code](https://github.com/CSS-Electronics/cancloud) | [Latest Release](https://github.com/CSS-Electronics/cancloud/releases)
---
* **[1]** The manager ensures only compatible devices can be updated and will perform various validation tests - but it will not e.g. block you from pushing an incorrect password or similar.
* **[2]** For objects, the information reflects custom S3 meta data attached to files uploaded by the CANedge3. For session folders, the information reflects a summary across the objects within. Specifically, the info includes the total number of log files, total size (as well as min/max size), the last modified S3 (time of upload to S3) and last modified SD (1st timestamp in the log file of the first and last log file in the folder)
* **[3]** If you have less than 10 connected devices, the status dashboard will load the log file data by default. For more devices, you’ll have to manually update the log file data via the dropdown menu (done to conserve API calls)
# index.html.md
# How to mount your S3 server on Linux
In this section we provide a step-by-step guide for mounting your S3 server on Linux via s3fs.
> ##### Table of Contents
>
> * [Installation (Debian based systems)](#installation-debian-based-systems)
> * [Credentials](#credentials)
> * [Mount S3 bucket](#mount-s3-bucket)
> * [Unmount](#unmount)
> * [Options (commandline / fstab)](#options-commandline-fstab)
> * [Connecting to a non-AWS server](#connecting-to-a-non-aws-server)
> * [Persist S3 mounting options](#persist-s3-mounting-options)
> * [Debugging](#debugging)
> * [HTTPS](#https)
---
## Installation (Debian based systems)
[s3fs](https://github.com/s3fs-fuse/s3fs-fuse) (free)
`sudo apt-get install s3fs`
---
## Credentials
Place a file (`.passwd-s3fs`) containing the access credentials in the home directory. Create the file using a text editor or via echo:
```text
$ echo ACCESS_KEY_ID:SECRET_ACCESS_KEY > ${HOME}/.passwd-s3fs
```
Example:
```text
ACCESS_KEY_ID = ``IXUAXUQ52BD2JQ1L1QTH``
SECRET_ACCESS_KEY= ``gYte/E87JyOf0aCK22bw9Bh6KBHQdBequAay3Vh4``
$ echo IXUAXUQ52BD2JQ1L1QTH:gYte/E87JyOf0aCK22bw9Bh6KBHQdBequAay3Vh4 > ${HOME}/.passwd-s3fs
$ cat ${HOME}/.passwd-s3fs
IXUAXUQ52BD2JQ1L1QTH:gYte/E87JyOf0aCK22bw9Bh6KBHQdBequAay3Vh4
```
Limit access to credentials file to current user only:
```text
$ chmod 600 ${HOME}/.passwd-s3fs
```
---
## Mount S3 bucket
Below assumes that the bucket is mounted by the active user.
Get the active user id and ground id:
```text
$ id
uid=1000(pi) gid=1000(pi)
```
Mount the bucket using:
```text
s3fs mybucket /path/to/mountpoint -o passwd_file=${HOME}/.passwd-s3fs -o url=https://url:port/ -o use_path_request_style -o uid=value,gid=value,umask=value
```
With:
* `uid`: User level access right
* `gid`: Group level access right
* `umask`: Level of access (read/write/execute)
*Example:*
* Bucket name: `office`
* Mount directory: `${HOME}/s3_mount/` (already created with mkdir)
* Path to credentials file: `${HOME}/.passwd-s3fs`
* S3 server url: `http://pi4server:9001/`
* User id: `uid=1000`
* Group id: `gid=1000`
* R/W/E access: `umask=0077` (Octal format = 0, Owner = 0, Group = 7, Other users = 7)
```text
s3fs office ${HOME}/s3_mount/ -o passwd_file=${HOME}/.passwd-s3fs -o url=http://pi4server:9001/ -o use_path_request_style -o uid=1000,gid=1000,umask=0077
```
The bucket is now mounted in `{HOME}/s3_mount/`:
```text
$ ls ${HOME}/s3_mount/
071E61AD 26AEB06C 51697F4D D2920F21
0DB63A93 2FB30D1C A9110452 E04A72BB
0EEBBC43 3B912722 ADC02130 F7261DAD
12C1A48D 4B23D6A0 C8B4DC35 server
```
On a system with a desktop interface, the mounted directory is listed as any other directory.
---
## Unmount
Unmount with: `fusermount -u ${HOME}/s3_mount/`
---
## Options (commandline / fstab)
The configuration options passed to s3fs take two different formats depending on the usage. When using the
commandline, options are passed using `-o option=value` - and when using the `fstab` configuration file, the options need to
be grouped together without spaces:
`option1=value,option_without_value,option3=some_other_value`
---
## Connecting to a non-AWS server
There are two methods to describe the S3 storage path:
* bucket before the hostname (bucket.host)
* bucket after the hostname (host/bucket)
AWS uses the first configuration, while MinIO uses the latter. To switch s3fs to use the latter configuration, the
option `use_path_request_style` needs to be passed.
---
## Persist S3 mounting options
To persist the mounting options on a system-wide basis, an entry with the relevant information can be added to the
`fstab` file under `/etc/fstab`.
Start by creating a file with the access information in `/etc/passwd-s3fs`.
```text
echo IXUAXUQ52BD2JQ1L1QTH:gYte/E87JyOf0aCK22bw9Bh6KBHQdBequAay3Vh4 | sudo tee /etc/passwd-s3fs
sudo chmod 600 /etc/passwd-s3fs
```
```text
s3fs#bucketname /path/to/mount/point fuse _netdev,allow_other,use_path_request_style,passwd_file=/path/to/passwd/file,uid=value,gid=value,umask=value,url=host 0 0
```
Example:
* Bucket name: `office`
* Mount directory: `/mnt/s3root/` (already created with mkdir)
* Path to credentials file: `/etc/passwd-s3fs`
* S3 server url: `https://pi4server:9001/`
* User id: `uid=1000`
* Group id: `gid=1000`
* R/W/E access: `umask=0077` (Octal format = 0, Owner = 0, Group = 7, Other users = 7)
```text
s3fs#office /mnt/s3root fuse _netdev,allow_other,use_path_request_style,passwd_file=/etc/passwd-s3fs,uid=1000,gid=1000,umask=0077,url=https://pi4server:9001/ 0 0
```
The device can now be mounted with:
```text
sudo mount /mnt/s3root
```
To unmount the drive:
```text
sudo umount /mnt/s3root
```
---
## Debugging
There are two debugging flags which can be enabled, resulting in information messages in the system log. The first flag
is only for s3fs, the second is for the underlying network tool `curl`.
* `debuglvl` (s3fs)
* `curldbg` (curl)
There are multiple log levels for s3fs, but `debuglvl=info` is a good place to start.
---
## HTTPS
When connecting to a self-hosted S3 server, it is important to setup the certificates to get the connection
to work.
Apart from the public/private keys on the S3 server (e.g. MinIO), the public key/certificate also needs to be
present on the client, and since it is self-signed it needs to be installed as a certificate authority. For debian,
this requires copying the certificate to the correct folder and repackaging the root certificates:
```text
sudo mkdir /usr/share/ca-certificates/minio-server
sudo cp public.crt /usr/share/ca-certificates/minio-server
sudo chmod 644 /usr/share/ca-certificates/minio-server/public.crt
```
Next, repackage the certificates (select `ask` and mark the new certificate manually):
```text
sudo dpkg-reconfigure ca-certificates
```
A quick test if it is installed correctly can be executed by calling `curl` directly:
```text
curl https://host:port/
```
If the certificate is not correctly installed, a message akin to the following can be observed:
```text
curl: (60) SSL certificate problem: self signed certificate
More details here: https://curl.haxx.se/docs/sslcerts.html
curl failed to verify the legitimacy of the server and therefore could not
establish a secure connection to it. To learn more about this situation and
how to fix it, please visit the web page mentioned above.
```
If the certificate is correctly installed, a response akin to the following can instead be observed:
```text
AccessDeniedAccess Denied./15C3F8CB6FAB2CC872bb169c-6b92-402f-bf26-4c5d35ad250f%
```
If the certificate is valid, but does not contain the correct hostname, the below is reported by curl:
```text
curl: (60) SSL: certificate subject name 'certificate host' does not match target host name 'host'
More details here: https://curl.haxx.se/docs/sslcerts.html
curl failed to verify the legitimacy of the server and therefore could not
establish a secure connection to it. To learn more about this situation and
how to fix it, please visit the web page mentioned above.
```
This can also occur if the IP is used instead of the hostname or the hostname instead of the IP when calling curl,
depending on what was used when generating the certificate.
# index.html.md
# Mount your S3 server as a local drive
---
Here we explain how you can mount your S3 server as a local drive. This makes it simple to manage devices, perform OTA updates and process log files - as if your data was stored locally[1](#id2).
> ##### Table of Contents
>
> * [Mount S3 on Windows (TntDrive)](#mount-s3-on-windows-tntdrive)
> * [Other mounting tools for Windows](#other-mounting-tools-for-windows)
> * [Mount S3 on Linux (s3fs)](#mount-s3-on-linux-s3fs)
---
## Mount S3 on Windows (TntDrive)
[TntDrive](https://tntdrive.com/) (free 30 day trial / ~60$ one-time license fee / [get a discount](https://37952ca6.sibforms.com/serve/MUIEAHIuKZ7f5HKZPNobSKkbxx5zC487FDat-tapq2_VKGSj_c5QrQ8G0Vd2AIsed3HZ0QkVxOM1dUnU8oUzDgF66eg2eHnz998zzNcIU4o8F7lgvkKHZKgk1ssPgYx4S15U3WP3VgS0hJMphar0FrbXoXjFwObOjzpyoedPYRZLqJzsUdQUyODBcVMffaoTjj3ay-B1L20GAIT7))
TntDrive is an S3 client for mounting your S3 bucket as a Windows network drive. You can easily add any S3 compatible server - incl. AWS S3, MinIO S3 etc.
Once mapped, you can manage files as if they were stored locally - e.g. directly opening log files in data processing tools, or referencing the drive in e.g. Python/MATLAB scripts. For details on how to mount an AWS S3 or MinIO S3 server, see the video above.
---
## Other mounting tools for Windows
We generally recommend TntDrive as it’s simple-to-use. However, below are various alternatives:
- [S3 Drive](https://www.nsoftware.com/drive/s3drive/) (beta, free for personal use)
- [Mountain Duck](https://mountainduck.io/) (~40$ one-time license fee)
- [rclone](https://rclone.org/commands/rclone_mount/) (free, but complex to setup)
---
## Mount S3 on Linux (s3fs)
You can also mount your S3 server on Linux. This can be done via a free open source tool, s3fs. Note, however, that the process is a bit more extensive - see our [step-by-step guide](mount-s3-linux.md#ref-mount-s3-linux).
---
* **[1]** If you’re mounting an S3 cloud server, you will of course still incur costs when processing files via the mounted drive. However, if you enable caching you can save costs when processing files that have been cached due to previous use.
# index.html.md
# S3 API
You can manage your S3 server objects manually via e.g. [CANcloud](cancloud-intro.md#ref-cancloud) - or programmatically via the S3 API. Below we briefly outline the S3 API use cases and tools.
---
## S3 API use cases
Typical use cases for the S3 API include:
* Performing batch over-the-air CANedge3 updates (while retaining device specific settings)
* Auto-processing log files (e.g. via event triggers) - often combined with the log file APIs
* Extracting relevant parts of e.g. large CSV databases for use in plots, reports etc
* Auto-updating Configuration Files in response to certain events/patterns
* Displaying data in e.g. your browser
---
## Tools using the S3 API
1. [CANcloud](cancloud-intro.md#ref-cancloud) is based on the Javascript S3 API
2. Our [OTA batch manager](s3-ota-batch-manager.md#ref-ota-batch-manager) lets you batch update devices over-the-air
3. Our [canedge_browser](https://github.com/CSS-Electronics/api-examples) lets you list log files on S3 for selected devices & time periods
4. Our [API examples](https://github.com/CSS-Electronics/api-examples) library on github has multiple examples of using the S3 API
# index.html.md
# Over-the-air batch manager
If you need to batch update your CANedge3 devices over-the-air, you can use the `canedge_manager` API/CLI. This makes it easy to update Configuration Files and/or Firmware of entire device fleets.
Learn more
# index.html.md
# DBC decode data
To analyse your data, you need to convert it to ‘physical values’. To do so, you need the relevant [DBC file](https://www.csselectronics.com/screen/page/can-dbc-file-database-intro) (CAN Database) or [LDF file](https://www.csselectronics.com/pages/ldf-lin-description-file) (LIN Description File) with decoding rules.
> ##### Table of Contents
>
> * [Decode an MF4 log file](#decode-an-mf4-log-file)
> * [Auto-load your DBC file(s)](#auto-load-your-dbc-file-s)
> * [Standard DBC files (J1939, NMEA 2000, ISOBUS and OBD2)](#standard-dbc-files-j1939-nmea-2000-isobus-and-obd2)
---
## Decode an MF4 log file
1. Load an MF4 with raw CAN/LIN data from the CANedge and go to ‘Bus Logging’
2. Click ‘Load CAN database’ to load your DBC(s)
3. Optionally specify which CAN channel to apply each DBC to
4. Click ‘Extract bus signals’ to save a new decoded MF4 file
The decoded MF4 will be opened as a new tab - ready for e.g. plotting or export.
#### NOTE
You can also decode raw LIN data via the ‘LIN/Load LIN database’ tab using DBC or LDF files
---
## Auto-load your DBC file(s)
1. Open ‘Managers/Bus database manager’ and load your DBC files
2. Specify which channel each DBC should be applied to, then click ‘Apply’
Your DBC files will now be automatically loaded between sessions/files.
---
## Standard DBC files (J1939, NMEA 2000, ISOBUS and OBD2)
Typically the CAN DBC is only known to the manufacturer (OEM), but exceptions exist:
### J1939 (heavy duty vehicles, agriculture, maritime)
Most heavy duty vehicles today use the standardized J1939 protocol. This means that you can typically use a J1939 DBC to decode a large share of signals across vehicle brands. We offer a [demo J1939 DBC](../../log-file-tools.md#ref-process) and a [full J1939 DBC](https://www.csselectronics.com/screen/product/j1939-dbc-file-pgn-spn/language/en).
### NMEA 2000 (boats/ships)
Most maritime vessels combine J1939 networks (e.g. for engines) and NMEA 2000 networks (e.g. for GPS, water depth, etc). We offer a full [NMEA 2000 DBC](https://www.csselectronics.com/products/nmea-2000-dbc-file-pgn-database) for this purpose.
### ISOBUS (tractors/implements)
Agriculture and forestry machines typically use ISOBUS to enable plug & play communication between e.g. tractors and implements. We offer a full [ISOBUS DBC](https://www.csselectronics.com/products/isobus-dbc-file-iso-11783) for this purpose.
### OBD2 (cars, light/medium/heavy duty vehicles)
Most cars/vans/trucks let you [request OBD2 PID data](../../record-data/obd2-data.md#ref-record-obd2-data), which can be decoded using our free [OBD2 DBC](../../log-file-tools.md#ref-process).
### Proprietary (cars, EVs)
Finally, for some cars/EVs, you can find reverse engineered DBC files online. We provide a number of these via our free [OBD2 data pack](https://www.csselectronics.com/pages/obd2-data-pack-car-dbc) and [EV data pack](https://www.csselectronics.com/pages/ev-data-pack-electric-vehicles).
# index.html.md
# Editing
The asammdf tool supports various powerful editing options.
## Converting your MDF version
You can convert your MDF4 to an older version, e.g. for software compatibility.
1. Go to the Convert tab
2. Select the preferred version (the CANedge log file format is 4.11)
3. Click Convert and save the file
## Cutting an MDF4 file
Cutting files lets you “carve out” a section of your data (e.g. from 10s to 30s).
1. Go to the Cut tab
2. Select the Start and End time in seconds
3. Click Cut and save the file
## Filtering selected channels
Filtering lets you create a new MDF4 that only includes selected signals.
1. Go to the Filter tab
2. Select the channels you want to include
3. Click Filter and save the file
## Resampling your data
Resampling lets you e.g. reduce the frequency and size of your data.
1. Go to the Resample tab
2. Choose “step” and select a frequency in seconds
3. Click Resample and save the file
You can also resample data based on a channel instead of a time raster. You can e.g. make signals match the timestamps of a specific signal (e.g. EngineSpeed) via interpolation.
# index.html.md
# Export data
The asammdf GUI lets you easily modify and export your data to other formats.
## Example: Exporting to CSV
You can export your raw or physical values to CSV for e.g. analysis in Excel.
The default CSV export settings will create a CSV file for every group of channels:
- For **raw CAN data**, consider using the `mdf2csv` MF4 converter rather than asammdf
- For **physical values** you’ll get a CSV for every CAN ID, containing the underlying signals
For physical values, you may want to use **‘Single time base’**, which combines all signals into a single file. This is achieved by resampling the signals to a common frequency - e.g. 0.5 seconds.
#### NOTE
You can enable ‘time as date’ to show the real-time clock date & time
Below is an example of a CSV from a DBC converted J1939 file using “Single time base”:

# index.html.md
# Create plots
Once you have decoded your MF4 data you can analyse it - e.g. via plots.
> ##### Table of Contents
>
> * [Enable sub windows](#enable-sub-windows)
> * [Plot parameters (drag & drop)](#plot-parameters-drag-drop)
> * [Plot parameters (via search)](#plot-parameters-via-search)
> * [Plot GPS position](#plot-gps-position)
> * [Create stack plot](#create-stack-plot)
> * [Display statistics tab](#display-statistics-tab)
> * [Add to common Y-axis](#add-to-common-y-axis)
> * [Save/load customized display views](#save-load-customized-display-views)
---
## Enable sub windows
1. Go to Settings/ and enable ‘Sub-windows’ and ‘Link sub-windows X-axis’
---
## Plot parameters (drag & drop)
1. From Channels, drag & drop a parameter into the gray area to plot it
2. Optionally click the ‘window’ icon to minimize the plot and add new signals
3. Press ‘Shift + H’ to tile the sub-plots horizontally (see Plot/ for more options)
---
## Plot parameters (via search)
1. Click ‘Ctrl + F’ to open the search window
2. Enter your signal name (optionally use \* before/after to broaden search)
3. Double click relevant signal(s) to add them to your final selection
4. Click ‘Add window’ to create a new plot window with the selected signals
---
## Plot GPS position
1. Click the ‘Create window’ icon below the channel list
2. Select GPS and click Apply (latitude/longitude signals are typically auto-loaded)
3. Optionally minimize the plot to add other signals in a time-synced grid
---
## Create stack plot
To quickly get an overview of multiple series, you can click ‘S’ to stack the plots.
---
## Display statistics tab
You can click ‘M’ to display statistical info regarding your signals.
---
## Add to common Y-axis
You can optionally add multiple signals to a common Y-axis.
---
## Save/load customized display views
You can create a multi-panel view of your data (e.g. for a specific analysis) and save the display file. This file can then later be loaded when you have another file open (e.g. from another time period) to quickly show the same analysis on the new data. To save/load a plot view, click ‘File/Save configuration’ / ‘File/Open configuration’.
---
## General plot tips
* Right click the plot to export it
* Click the Plot menu at the top for more options
* Keyboard shortcuts can be used for fast plot navigation
* Under “Plot/Insert computation” you can create custom calculated charts
* Show absolute date & time in the plot via Settings/Plot X axis
* Click the color box next to a parameter to change the plot color
* In ‘Settings/Step mode’ you can select the step mode
* Click ‘.’ to display plot dots to better distinguish actual observations
# index.html.md
# Load raw data
In this section we explain how to load and review your raw MF4 log files.
> ##### Table of Contents
>
> * [View ‘trace’ of your raw MF4 data](#view-trace-of-your-raw-mf4-data)
> * [Filter your raw data](#filter-your-raw-data)
> * [Concatenate multiple log files](#concatenate-multiple-log-files)
---
## View ‘trace’ of your raw MF4 data
To open a single file, click “File/Open” and browse to your `.MF4` log file.
You can review the loaded MF4 data in the **Channels** tab. Click the ‘Create window’ at the bottom to display a ‘CAN Bus Trace’ or ‘LIN Bus Trace’. This lets you browse your raw data, including error/remote frames[1](#fn-channels). By default, the ‘timestamps’ column show the delta time vs. the last power cycle. You can instead show the absolute date & time by clicking ‘Time as date’.
#### NOTE
If your data is compressed/encrypted (`.MFC/.MFE/.MFM`), use [mdf2mdf](../mdf4-converters.md#ref-mdf4-converters) to convert it to `.MF4`
---
## Filter your raw data
When analyzing your raw CAN/LIN data, it can be useful to apply filters. As an example, below filters will ensure we only see CAN IDs `7E8-7EF` and `18DAF100-18DAF1FF`. Note that ID filters should match whether you are using the ‘hex’ or ‘phys’ representation of IDs (see the dropdown).

---
## Concatenate multiple log files
You can combine multiple MF4 log files via the Mode/Batch processing tab view:
1. Load your log files/folders
2. Click the ‘Sort by start time’ button
3. Click Concatenate and save the combined file
The new joint file can now be loaded via the Mode/Single files tab.
---
* **[1]** The channel structure used in the CANedge MF4 files is designed for internal file optimization and is not desigend to be meaningful for end users. As such we recommend to ignore the left-panel view of the channels for your raw log files and instead focus on reviewing your file via the CAN/LIN trace functionality in the asammdf GUI, combined with the use of filters
# index.html.md
# Grafana-Athena dashboards
This integration lets you visualize your CANedge CAN/LIN data in Grafana dashboards by combining an Amazon Parquet data lake with Amazon Athena.
1. [Initial setup](grafana-athena/initial-setup.md#ref-initial-setup-grafana-athena) - set up your Amazon Parquet data lake, Athena and Grafana
2. [Customize dashboard](grafana-athena/customize-dashboard.md#ref-customize-athena-dashboard) - customize your Grafana dashboard
# index.html.md
# Grafana-BigQuery dashboards
This integration lets you visualize your CANedge CAN/LIN data in Grafana dashboards by combining a Google Parquet data lake with Google BigQuery.
1. [Initial setup](grafana-bigquery/initial-setup.md#ref-initial-setup-grafana-bigquery) - set up your Google Parquet data lake, BigQuery and Grafana
2. [Customize dashboard](grafana-bigquery/customize-dashboard.md#ref-customize-bigquery-dashboard) - customize your Grafana dashboard
# index.html.md
# Grafana-Synapse dashboards
This integration lets you visualize your CANedge CAN/LIN data in Grafana dashboards by combining an Azure Parquet data lake with Azure Synapse.
1. [Initial setup](grafana-synapse/initial-setup.md#ref-initial-setup-grafana-synapse) - set up your Azure Parquet data lake, Synapse and Grafana
2. [Customize dashboard](grafana-synapse/customize-dashboard.md#ref-customize-synapse-dashboard) - customize your Grafana dashboard
# index.html.md
# PowerBI-Synapse dashboards
This integration lets you visualize your CANedge CAN/LIN data in Power BI dashboards by combining an Azure Parquet data lake with Azure Synapse.
1. [Initial setup](powerbi-synapse/initial-setup.md#ref-initial-setup-powerbi-synapse) - set up your Azure Parquet data lake, Synapse and Power BI
# index.html.md
# MF4 decoder troubleshooting
The below provides guidance if you are not seeing the expected output when decoding your data.
> ##### Table of Contents
>
> * [Check the basics](#check-the-basics)
> * [Compare vs. asammdf](#compare-vs-asammdf)
> * [Test if invalid Parquet](#test-if-invalid-parquet)
> * [Contact us](#contact-us)
---
## Check the basics
1. Ensure that you have read the [MF4 decoder documentation](../mdf4-decoders.md#ref-mdf4-decoders)
2. Ensure that you are using the [latest MF4 decoders](../mdf4-decoders.md#ref-mdf4-decoders)
3. Ensure that your MDF is directly from the CANedge[1](#fn-direct)
4. Check if your DBC can be opened in the free [CANDB++](https://www.vector.com/se/en/download/candb-31-sp5/) tool (to check syntax errors)
5. Check that you have correctly assigned prefixes to your DBC files (e.g. `can1-`)[2](#fn-prefix)
6. Check that your min/max values are set correctly for your signals[3](#fn-min-max)
7. Drag & drop your log file onto the `mdf2parquet_decode` and review the results via [Tad](https://www.tadviewer.com/)
8. If a specific message is not as showing, double check your DBC file for that message
9. Check if your MDF raw data contains the CAN/LIN ID (e.g. via [asammdf](../asammdf-gui/raw-mdf4.md#ref-asammdf-raw-data))
10. Make sure there are no ‘message key collisions’ (the MF4 decoders will warn of this)[4](#fn-collisions)
11. Make sure none of your decoded CAN IDs have variable data length[5](#fn-length)
As a general tip, you can also try decoding your data via the [command line](https://www.youtube.com/watch?v=bgSSJQolR0E) for details as below:
```text
mdf2parquet_decode -i 00000001.MF4 --verbosity=4
```
---
## Compare vs. asammdf
If you tried the above, but you are still not seeing the expected results, you can try using the [asammdf GUI](../asammdf-gui.md#ref-asammdf-gui) to help isolate if the issue appears linked to the MF4 decoders or something else:
1. Load your raw CANedge MDF log file in the asammdf GUI
2. In the Bus Logging tab, load the DBC files you use for testing
3. Ensure that each DBC is applied as per the prefix channel (e.g. `can1-mydbc.dbc` to CAN1)
4. Decode the data in asammdf and compare it vs the MF4 decoder output
If asammdf outputs the same results as the MF4 decoders, then the issue is most likely with your DBC file, or simply that your raw data in fact has no messages matched by the DBC files. In this case, use the asammdf GUI to review your [raw CAN bus trace](../asammdf-gui/raw-mdf4.md#ref-asammdf-raw-data) to identify the root cause. You can also review the ‘Bus Logging’ summary statistics in asammdf to see which messages were matched by your DBC file(s).
If asammdf outputs the expected results, while the MF4 decoders do not, the most likely reason is a DLC mismatch[6](#fn-dlc-issue) between your DBC file and the actual message payload. You can check this by reviewing the raw data in the asammdf GUI. This should then also be reported via the ‘verbose’ output when using the MF4 decoder via the command line.
---
## Test if invalid Parquet
If you believe your issue relates to invalid Parquet files being generated, we recommend that you test this locally. Specifically, you can try opening the Parquet via [Tad](https://www.tadviewer.com/) and test if it opens as expected. If not, we recommend contacting us as per below.
---
## Contact us
If you are still unable to identify the root cause, please contact us and share the raw MF4 file, correctly named DBC file and details on the expected vs. observed output. If you are unable to share your entire DBC file, you can create a minimal/sanitized version that replicates the issue.
---
* **[1]** The MF4 decoders do not support MDF files from 3rd party hardware/software tools. For example, MDF files recorded by Vector tools are not supported. Similarly, MDF files from the CANedge which have been saved/exported/concatenated via e.g. asammdf, MATLAB or other tools will also not work. MDF files that have been finalized via the `mdf2mdf` MF4 converter are supported, however
* **[2]** The prefixes must be defined so that they match the CAN/LIN channel containing the data you’re attempting to apply the DBC file to. If you e.g. assign the prefix `can1-` to your DBC file, it will not be used for decoding any data on CAN Channel 2, for example. You can have multiple DBC files assigned to the same CAN/LIN channel
* **[3]** The MF4 decoders will deliberately ‘filter out’ decoded values that fall outside the min/max range of a signal. If you have e.g. set arbitrary min/max values in your DBC, this can result in data unexpectedly being excluded
* **[4]** If you have one or more DBC files on a single CAN channel where CAN IDs are identical, this will cause an error and the decoding will not work (the decoder will produce a warning about collisions). Note that the MF4 decoders are more ‘strict’ than asammdf in regards to this, hence you may experience that asammdf decodes your data without issues. To solve collisions, you can remove excess duplicate CAN IDs from your DBC file(s) to ensure uniqueness. As a ‘special case’ of this, if you have a J1939 DBC file with overlapping 18-bit PGNs (but unique 29-bit CAN IDs), the decoder will also consider this as a collision. As before, you can manually remove duplicate entries. Alternatively, if you do not wish to match data at the PGN level, you can change your DBC file to a non-J1939 type with exact 29-bit ID matching by changing the field `BA_ "ProtocolType" "J1939";` to `BA_ "ProtocolType" "";` in a text editor
* **[5]** If a CAN ID has variable length over time, this will result in corrupt Parquet files (which cannot be opened via Tad) and/or ‘schema issues’ in your data lake (as different files have different columns) - which will cause query issues in e.g. Grafana
* **[6]** The asammdf GUI will attempt to decode messages where the DBC file has a matching ID, even if the DLC is not matched. For example, you raw data may contain a message with DLC of 6, while your DBC file states that this message has a DLC of 8. In this case, the asammdf GUI will still decode the 6 bytes as per the DBC file, while the MF4 decoder ignores the message entirely. To resolve this, update your DBC file to have the correct DLC value for each message
# index.html.md
# Parquet data lake - advanced topics
In this section we cover some advanced topics for Parquet data lakes:
1. [Backlog processing](parquet-data-lake-advanced/backlog.md#ref-parquet-data-lake-advanced-backlog) - process a historical backlog of MDF files
2. [Device specific DBC](parquet-data-lake-advanced/device-dbc-files.md#ref-parquet-data-lake-advanced-device-specific-dbc) - add device specific DBC decoding
3. [Event detection](parquet-data-lake-advanced/alerts.md#ref-parquet-data-lake-advanced-alerts) - add event tables to your data lake and trigger email alerts
4. [Calculated signals](parquet-data-lake-advanced/custom-signals.md#ref-parquet-data-lake-advanced-custom-signals) - add calculated signal tables to your data lake
5. [Trip summaries](parquet-data-lake-advanced/aggregation.md#ref-parquet-data-lake-advanced-trip-summary) - add trip summary tables to your data lake
6. [External database](parquet-data-lake-advanced/external-database.md#ref-parquet-data-lake-advanced-external-database) - write decoded data to external database (instead of data lake)
7. [Client-specific routing](parquet-data-lake-advanced/routing.md#ref-parquet-data-lake-advanced-routing) - route data to per-client output buckets (multi-tenant, AWS only)
# index.html.md
# Parquet data lake
In this section we outline how to set up a Parquet data lake incl. automation and SQL interface.
Parquet data lakes offer a low cost, scalable and interoperable way of storing DBC decoded CAN/LIN data. The data lake can be analyzed via e.g. Python/MATLAB or SQL interfaces.
This is a prerequisite for [Grafana dashboards](../browser-dashboards.md#ref-dashboards) and some MATLAB/Python script examples.
> ##### Table of Contents
>
> * [Prepare & test DBC files](#prepare-test-dbc-files)
> * [Create a Parquet data lake](#create-a-parquet-data-lake)
---
## Prepare & test DBC files
1. Download the MF4 decoder `mdf2parquet_decode.exe` and review the documentation [here](https://canlogger.csselectronics.com/tools-docs/decoders_mf4/decoders/)
2. Rename your DBC files to add the `` prefix (`can1-.dbc`, `can9-.dbc`, …)[1](#fn-dbc-names)
3. Verify that you can decode your log file by drag & dropping it onto the `mdf2parquet_decode.exe`
#### NOTE
You can easily open Parquet files on your PC via the free Parquet viewer [Tad](https://www.tadviewer.com/)
#### NOTE
If you have issues decoding your data, see our [MF4 decoder troubleshooting guide](mf4-decoder-troubleshooting.md#ref-mf4-decoder-troubleshooting)
---
## Create a Parquet data lake
Once you have tested your setup locally, you can set up your Parquet data lake and automation.
You can set this up in multiple ways, depending on your existing environment[2](#fn-existing):
1. [Amazon](parquet-data-lake/amazon.md#ref-parquet-data-lake-aws) - create a Parquet data lake stored in an AWS S3 bucket (incl. automation)
2. [Google](parquet-data-lake/google.md#ref-parquet-data-lake-google) - create a Parquet data lake stored in a Google bucket (incl. automation)
3. [Azure](parquet-data-lake/azure.md#ref-parquet-data-lake-azure) - create a Parquet data lake stored in an Azure container (incl. automation)
4. [Local](parquet-data-lake/local.md#ref-parquet-data-lake-local) - create a Parquet data lake stored locally with manual processing
---
* **[1]** As per the MF4 decoder docs, the prefix specifies whether a DBC is applied to CAN CH1, LIN CH2 etc. You can have multiple DBC files with the same type and channel prefix. Ensure that your DBC file names use only letters, numbers and dashes
* **[2]** For example, if you are using a CANedge2/3 to upload data to Amazon or Azure, we recommend setting up a Parquet data lake in Amazon or Azure, respectively
# index.html.md
# Update your CloudFormation stack revision
In some cases you may need to update your Amazon Parquet data lake deployment e.g. to update the integration to a more recent version.
> ##### Table of Contents
>
> * [Update your CloudFormation stack](#update-your-cloudformation-stack)
> * [Note on customized Lambda/Glue](#note-on-customized-lambda-glue)
---
## Update your CloudFormation stack
1. Download the [latest Lambda zip and Python scripts](parquet-data-lake/amazon.md#ref-parquet-data-lake-aws)
2. Upload the zip/script files to your S3 input bucket root via the [S3 console](https://s3.console.aws.amazon.com/s3/buckets)
3. Select your existing stack in [AWS CloudFormation](https://console.aws.amazon.com/cloudformation)
4. Click ‘Stack actions/Create change set for current stack’
5. Click ‘Replace current template’ and enter the [‘deploy integration’ stack](parquet-data-lake/amazon.md#ref-parquet-data-lake-aws)
6. Click ‘Acknowledge’, ‘Submit’, wait ~1 min and click the upper-right refresh
7. Review that the changes in resources look as expected
8. Click ‘Execute change set’ (and click it again in the popup), then wait ~1 min
9. Verify that the deployment succeeds
After updating, we recommend to [test your Lambda function](parquet-data-lake/amazon.md#ref-parquet-data-lake-aws) and re-run your Glue mapping script.
---
## Note on customized Lambda/Glue
If you have modified your Lambda code (e.g. with [custom signals](parquet-data-lake-advanced.md#ref-parquet-data-lake-advanced)), you should include these customizations in the new Lambda zip before uploading it. Similarly, if you have made customizations to the Glue script, incorporate these into the new script before uploading.
# index.html.md
# Import your Amazon S3 input bucket
This guide explains how to proceed if you wish to [deploy an Amazon Parquet data lake](amazon.md#ref-parquet-data-lake-aws) - but you have previously deleted your S3 input bucket stack (or manually deployed your S3 input bucket).
1. Open [AWS CloudFormation](https://console.aws.amazon.com/cloudformation) and ensure you are in the same region as your input bucket
2. Verify that there are no existing stacks[1](#fn-existing-stack)
3. Click the upper-right ‘Create stack/With existing resources (import resources)’
4. Enter below in the ‘Amazon S3 URL’:
`https://css-electronics-resources.s3.eu-central-1.amazonaws.com/stacks/import-s3-bucket-v1.3.0.json`
5. Enter the name of your existing AWS S3 input bucket
6. Enter a unique ‘stack’ name (e.g. `canedge-stack`) and your input bucket name again
7. Click ‘Import resources’ once the ‘Changes’ have loaded, wait ~1 min and hit F5
#### NOTE
This only works if you use the ‘import resources’ - not if you create a new stack from scratch
* **[1]** If you have created your S3 input bucket via CloudFormation and subsequently deleted it, the stack will not appear in your overview. If the stack does appear, you should instead just follow the normal process outlined in the [Amazon Parquet data lake deployment](amazon.md#ref-parquet-data-lake-aws)
# index.html.md
# Amazon Parquet data lake

Here we explain how to deploy an Amazon Parquet data lake with automation and an interface.
This can e.g. be used in [Grafana-Athena dashboards](../../browser-dashboard/grafana-athena.md#ref-grafana-athena) or [Python/MATLAB scripts](../../mdf4-decoders.md#ref-mdf4-decoders).
> ##### Table of Contents
>
> * [Overview](#overview)
> * [1: Upload files to input bucket](#upload-files-to-input-bucket)
> * [2: Deploy integration](#deploy-integration)
> * [3: Test your cloud function](#test-your-cloud-function)
> * [4: Map your Parquet data lake to tables](#map-your-parquet-data-lake-to-tables)
---
## Overview
This guide lets you set up an automated data pre-processing workflow, including:
- An ‘input bucket’ (for MDF/DBC files) and ‘output bucket’ (for Parquet files)
- A ‘Lambda function’ (DBC decodes new MDF files and outputs them as Parquet files)
- An ‘Athena’ SQL interface for querying the data lake (e.g. from Grafana)
- Three ‘support Glue jobs’ (map data lake, process MDF backlogs, summarize trips)
#### NOTE
Ensure you [test the MF4 decoders](../parquet-data-lake.md#ref-parquet-data-lake) with your log files & DBC files locally before proceeding.
---
## 1: Upload files to input bucket
1. Upload your [prefixed DBC files](../parquet-data-lake.md#ref-parquet-data-lake) (e.g. `can1-xyz.dbc`) to your bucket root via the [S3 console](https://s3.console.aws.amazon.com/s3/buckets)[3](#fn-encrypted)
2. Upload below 4 files[4](#fn-changelog) (zip file and Python scripts) to your bucket root
[`Lambda zip`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake/mdf-to-parquet-amazon-function-v4.2.1.zip) | [`Mapping script`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake-interfaces/athena/create_glue_database_from_s3-vG.6.0.py) | [`Backlog script`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake/process_backlog_amazon_entry-v4.2.1.py) | [`Aggregation script`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake/process_aggregation_amazon_entry-v4.2.1.py)
---
## 2: Deploy integration
1. Open [AWS CloudFormation](https://console.aws.amazon.com/cloudformation) and ensure you are in the same region as your input bucket
2. Select the stack you used to create your S3 bucket (default name `canedge-stack`)[5](#fn-import-bucket)
3. Click ‘Stack actions/Create change set for current stack’
4. Click ‘Replace current template’ and enter below:
```text
https://css-electronics-resources.s3.eu-central-1.amazonaws.com/stacks/data-lake-v4.2.1-vG.6.0.json
```
1. Enter a ‘UniqueID’ (e.g. `datalake05`)[6](#fn-uniqueid)
2. Enter a valid email for notifications on Lambda errors/events[7](#fn-email)
3. Click ‘Acknowledge’, ‘Submit’, wait ~1 min and click the upper-right refresh
4. Click ‘Execute change set’ (and click it again in the popup), then wait ~1 min
#### NOTE
If the deployment fails, double check that you uploaded the zip/scripts to your S3 input bucket
#### NOTE
If you later need to update the integration with a new revision, see [this guide](../update-glue.md#ref-update-glue)
---
## 3: Test your cloud function
1. Upload a test MDF file from your CANedge into your input bucket via the [S3 console](https://s3.console.aws.amazon.com/s3/buckets)
2. Verify that the decoded Parquet files are created in your output bucket[8](#fn-suffix)
Your data lake will now get auto-filled when new MDF files are uploaded to the input bucket.
#### NOTE
If you are not seeing the expected results, review the [Lambda CloudWatch logs](https://eu-central-1.console.aws.amazon.com/cloudwatch/home?#logsV2:log-groups$3FlogGroupNameFilter$3Daws$252Flambda$252Fmdf-to-parquet)
---
## 4: Map your Parquet data lake to tables
1. Verify that your S3 output bucket contains Parquet files
2. Open [AWS Glue Triggers](https://console.aws.amazon.com/glue/home?#/v2/etl-configuration/triggers) in a new tab
3. Select the `-map-tables-on-demand` trigger and click ‘Action/Start trigger’
4. Open the trigger target Glue job, click ‘Runs’ and verify that it succeeds[10](#fn-glue-troubleshooting)
#### NOTE
Glue adds ‘meta data’ about your S3 output bucket. If new devices/messages are added to your Parquet data lake, the Glue job should be triggered again (manually or by schedule)[9](#fn-glue-trigger)
You can now use Athena as a data source in e.g. [Grafana-Athena dashboards](../../browser-dashboard/grafana-athena.md#ref-grafana-athena). See also the [advanced topics](../parquet-data-lake-advanced.md#ref-parquet-data-lake-advanced) to learn about backlog processing, event detection, trip summaries and more.
---
* **[1]** You can upgrade your account from the free tier to paid in the ‘Cost and Usage’ section by clicking ‘Upgrade Plan’
* **[2]** If you have connected a CANedge2/CANedge3 to an AWS S3 bucket then this is your input bucket
* **[3]** If your MDF files are encrypted (`MFE`, `MFM`), also upload your `passwords.json` file
* **[4]** Changelogs: [`automation scripts`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake/changelogs/mdf-to-parquet-amazon-function-changelog.txt) | [`mapping script`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake-interfaces/athena/changelogs/create-glue-database-from-s3-changelog.txt)
* **[5]** If you deleted your S3 input bucket stack (or manually deployed it), you need to import your S3 bucket as per [this guide](amazon-import.md#ref-parquet-data-lake-aws-import-input-bucket)
* **[6]** The unique ID can be useful if you e.g. need to deploy multiple separate Parquet data lakes
* **[7]** We recommend to confirm the subscription to error/event emails as it helps you monitor your workflow, but you can of course disable these emails if preferred. You can edit your SNS subscriptions within AWS
* **[8]** The output bucket will be named as `-parquet` - you can find it via the AWS S3 console
* **[9]** New Parquet files added for existing devices/messages will automatically be available for queries by Athena. A new Glue job run is only required if the new Parquet data reflects a previously ‘unmapped’ device or table. For most use cases, the manual trigger will therefore suffice. However, a scheduled trigger is recommended if you expect new devices/messages to be added frequently over time. To activate the scheduled trigger, select it and click ‘Action/Activate trigger’. A Glue job will normally cost ~0.03$/run (depending on data lake size), in which case a scheduled daily trigger would cost cost ~10$/year
* **[10]** If your Glue job fails click the ‘Output logs’ in the lower right corner to see more information
# index.html.md
# Azure Parquet data lake

Here we explain how to deploy an Azure Parquet data lake with automation and an interface.
This can e.g. be used in [Grafana-Synapse dashboards](../../browser-dashboard/grafana-synapse.md#ref-grafana-synapse), [PowerBI-Synapse dashboards](../../browser-dashboard/powerbi-synapse.md#ref-powerbi-synapse) or [Python](../../mdf4-decoders.md#ref-mdf4-decoders).
> ##### Table of Contents
>
> * [Overview](#overview)
> * [1: Upload to input container](#upload-to-input-container)
> * [2: Deploy integration](#deploy-integration)
> * [3: Test your cloud function](#test-your-cloud-function)
> * [4: Map your Parquet data lake to tables](#map-your-parquet-data-lake-to-tables)
---
## Overview
This guide lets you set up an automated data pre-processing workflow, including:
- An ‘input container’ (for MDF/DBC files) and ‘output container’ (for Parquet files)
- An ‘Azure function’ (DBC decodes new MDF files and outputs them as Parquet files)
- A ‘Synapse’ SQL interface for querying the data lake (e.g. from Grafana)
- Three ‘support jobs’ (map data lake, process MDF backlogs, summarize trips)
#### NOTE
Ensure you [test the MF4 decoders](../parquet-data-lake.md#ref-parquet-data-lake) with your log files & DBC files locally before proceeding.
---
## 1: Upload to input container
1. Upload the [prefixed DBC files](../parquet-data-lake.md#ref-parquet-data-lake) (e.g. `can1-xyz.dbc`) to your input container root via the [console](https://portal.azure.com/#browse/Microsoft.Storage%2FStorageAccounts)[1](#fn-encrypted)
2. Upload below zip[2](#fn-changelog) to your container root
[`Cloud function zip`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake/mdf-to-parquet-azure-function-v4.2.1.zip)
#### NOTE
If you later need to update the function zip, upload the new version and repeat the steps below
---
## 2: Deploy integration
1. Open the [canedge-azure-cloud-terraform](https://github.com/CSS-Electronics/canedge-azure-cloud-terraform) repository
2. Go through the ‘setup instructions’ to open your Cloud Shell and clone the repository
3. Go through step 2 (MF4-to-Parquet) with `--github-token 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`
4. Go through step 3 (Synapse) with the above token
5. Note down the Synapse connection output (for use in e.g. connecting Grafana/PowerBI)
---
## 3: Test your cloud function
1. Upload a test MDF from your CANedge into your input container via CANcloud or the console
2. Verify that the decoded Parquet files are created in your output container[3](#fn-suffix)
Your data lake will now get auto-filled when new MDF files are uploaded to the input container.
---
## 4: Map your Parquet data lake to tables
1. Verify that your output container contains Parquet files[4](#fn-parquet-files)
2. Open your ‘synapse-map-tables’ Container App Job via the console
3. Click ‘Run now’ (at the top) and then click the execution history
4. Verify that the job succeeds[6](#fn-console-logs) (the job may fail the 1st time, re-run it)
#### NOTE
The mapping script adds ‘meta data’ about your output container. If new devices/messages are added to your Parquet data lake, the script should be run again (manually or by schedule)[5](#re-run-script)
Next, you can setup [Grafana-Synapse dashboards](../../browser-dashboard/grafana-synapse/initial-setup.md#ref-initial-setup-grafana-synapse) - or check the [advanced topics](../parquet-data-lake-advanced.md#ref-parquet-data-lake-advanced) to process your historical backlog of MDF files, add custom event triggers and more.
---
* **[1]** If your MDF files are encrypted (`MFE`, `MFM`), also upload your `passwords.json` file
* **[2]** Changelogs: [`changelog`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake/changelogs/mdf-to-parquet-azure-function-changelog.txt)
* **[3]** The output container will be named as `-parquet` in the same storage account as your input container
* **[4]** If your output container is empty, you can upload a test MDF file to your input container to create some Parquet data
* **[5]** You only need to re-run the script if new tables are to be created, not if you simply add more data to an existing table
* **[6]** You can review the console output of the script under by clicking the Console Logs under the execution history. Note that these may be delayed by up to 15 min and may not be sorted in time ascending order by default
# index.html.md
# Google Parquet data lake

Here we explain how to deploy a Google Parquet data lake with automation and an interface.
This can e.g. be used in [Grafana-BigQuery dashboards](../../browser-dashboard/grafana-bigquery.md#ref-grafana-bigquery) or [Python/MATLAB](../../mdf4-decoders.md#ref-mdf4-decoders).
> ##### Table of Contents
>
> * [Overview](#overview)
> * [1: Upload files to input bucket](#upload-files-to-input-bucket)
> * [2: Deploy integration](#deploy-integration)
> * [3: Test your cloud function](#test-your-cloud-function)
> * [4: Map your Parquet data lake to tables](#map-your-parquet-data-lake-to-tables)
---
## Overview
This guide lets you set up an automated data pre-processing workflow, including:
- An ‘input bucket’ (for MDF/DBC files) and ‘output bucket’ (for Parquet files)
- A ‘cloud function’ (DBC decodes new MDF files and outputs them as Parquet files)
- A ‘BigQuery’ SQL interface for querying the data lake (e.g. from Grafana)
- Three ‘support cloud functions’ (map data lake, process MDF backlogs, summarize trips)
#### NOTE
Ensure you [test the MF4 decoders](../parquet-data-lake.md#ref-parquet-data-lake) with your log files & DBC files locally before proceeding.
---
## 1: Upload files to input bucket
1. Upload your [prefixed DBC files](../parquet-data-lake.md#ref-parquet-data-lake) (e.g. `can1-xyz.dbc`) to your bucket root via the [console](https://console.cloud.google.com/)[1](#fn-encrypted)
2. Upload below 4 files[2](#fn-changelog) to your bucket root
[`Cloud function zip`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake/mdf-to-parquet-google-function-v4.2.1.zip) | [`Mapping function zip`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake-interfaces/bigquery/bigquery-map-tables-vT.5.0.zip) | [`Backlog zip`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake/backlog-processor-google-v4.2.1.zip) | [`Aggregation zip`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake/aggregation-processor-google-v4.2.1.zip)
#### NOTE
If you later need to update the integration, upload the new files and repeat the steps below
---
## 2: Deploy integration
1. Open the [canedge-google-cloud-terraform](https://github.com/CSS-Electronics/canedge-google-cloud-terraform) repository
2. Go through the ‘setup instructions’ to open your Cloud Shell and clone the repository
3. Go through step 2 (MF4-to-Parquet) (see above video)
4. Go through step 3 (BigQuery)
---
## 3: Test your cloud function
1. Upload a test MDF from your CANedge into your input bucket via CANcloud or the [console](https://console.cloud.google.com/)
2. Verify that the decoded Parquet files are created in your output bucket[3](#fn-suffix)
Your data lake will now get auto-filled when new MDF files are uploaded to the input bucket.
---
## 4: Map your Parquet data lake to tables
1. Verify that your output bucket contains Parquet files[4](#fn-parquet-files)
2. Open [Cloud Scheduler](https://console.cloud.google.com/cloudscheduler) in your browser
3. Select ‘map-tables-scheduler’, click `RESUME` and `FORCE RUN`
4. After it completes, click `PAUSE`
Optionally review your `-bq-map-tables` function Logs/ tab via the [console (function overview)](https://console.cloud.google.com/run)
#### NOTE
The mapping script adds ‘meta data’ about your output bucket. If new devices/messages are added to your Parquet data lake, the script should be run again (manually or by schedule)[5](#re-run-script)
Next, set up [Grafana-BigQuery dashboards](../../browser-dashboard/grafana-bigquery/initial-setup.md#ref-initial-setup-grafana-bigquery) - or check the [advanced topics](../parquet-data-lake-advanced.md#ref-parquet-data-lake-advanced) to process your historical backlog of MDF files, add custom event triggers and more.
---
* **[1]** If your MDF files are encrypted (`MFE`, `MFM`), also upload your `passwords.json` file
* **[2]** Changelogs: [`changelog`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake/changelogs/mdf-to-parquet-google-function-changelog.txt) | [`changelog`](/_static/files/log-file-tools/mdf4-decoders/parquet-data-lake-interfaces/bigquery/changelogs/bigquery-map-tables-changelog.txt)
* **[3]** The output bucket will be named as `-parquet` in the same storage account as your input bucket
* **[4]** If your output bucket is empty, you can upload a test MDF file to your input bucket to create some Parquet data
* **[5]** You only need to re-run the script if new tables are to be created, not if you simply add more data to an existing table
# index.html.md
# Local Parquet data lake

The simplest way to set up a Parquet data lake is to manually create and store it locally:
1. Create a local folder (`input/`) next to your `mdf2parquet_decode.exe` and prefixed DBC files
2. Copy your MDF log files into this folder (with the CANedge path structure[1](#fn-path-structure))
3. Drag & drop this folder onto the `mdf2parquet_decode.exe` to create your data lake
If you want to use the more advanced cloud automation functionality locally, clone the [canedge-mdftoparquet-automation](https://github.com/CSS-Electronics/canedge-mdftoparquet-automation) repo and follow the README to process your local input folder.
Open source interfaces like [DuckDB](https://duckdb.org/) and [ClickHouse](https://clickhouse.com/) let query data from your [local Parquet data lake](#ref-parquet-data-lake-local) via SQL. They can be used in e.g. Grafana dashboards, Excel or Python.
Local interface are beyond the scope of this intro, but we recommend below resources:
1. [MF4 decoder Docs](../../mdf4-decoders.md#ref-mdf4-decoders) - learn how to set up Grafana-ClickHouse or use DuckDB in Python
---
* **[1]** I.e. how the files are stored in the `LOG/` folder on a CANedge SD: `[DEVICE_ID]/[SESSION_NUMBER]/[SPLIT_NUMBER].[FILE_EXTENSION]`
# index.html.md
# Add trip summaries to your data lake
---
For many use cases you will need to analyze data across devices, messages and trips. To do this at scale, it can be useful to perform periodic data aggregation and add ‘trip summary tables’ to your Amazon/Google/Azure Parquet data lake. These can e.g. be used in creating dashboard overviews across all your trips.
> ##### Table of Contents
>
> * [Setup aggregation via JSON file](#setup-aggregation-via-json-file)
> * [How it works](#how-it-works)
> * [JSON syntax](#json-syntax)
> * [How to run](#how-to-run)
> * [Amazon](#amazon)
> * [Google](#google)
> * [Azure](#azure)
---
## Setup aggregation via JSON file
To setup trip summary aggregation of Parquet files in your cloud, follow below steps:
1. Ensure you are using the latest data lake integration
2. Download our example `aggregations.json` below and modify it as per your needs
3. Once ready, upload it to your input bucket root
4. Trigger the aggregation processing as outlined for your specific cloud below
[`aggregations.json`](/_static/files/log-file-tools/mdf4-decoders/automation-json-files/aggregations.json)
### How it works
When you run the aggregation processing job, it will do the following:
1. The script will download and validate your `aggregations.json` file
2. It will go through each day of the period specified for each cluster/device
3. It will identify trip windows based on the trip identifier signal
4. For each trip window, it will calculate signal aggregations
5. The aggregations are written to your data lake in the `aggregations/tripsummary` folder
6. The resulting tables can be queried via e.g. our trip summary [Grafana dashboards](../../browser-dashboards.md#ref-dashboards)
### JSON syntax
To illustrate the JSON syntax, consider the example below:
```json
{
"config": {
"date": {
"mode": "specific_period",
"start_date": "2025-01-01",
"end_date": "2025-01-15"
},
"trip": {
"trip_gap_min": 10,
"trip_min_length_min": 1
}
},
"device_clusters": [
{
"devices": ["2F6913DB", "ABCDEF12"],
"cluster": "cluster1"
}
],
"cluster_details": [
{
"clusters": ["cluster1"],
"details": {
"trip_identifier": {"message": "CAN9_GnssSpeed"},
"aggregations": [
{
"message": "CAN9_GnssSpeed",
"signal": ["Speed"],
"aggregation": ["avg", "max"]
},
{
"message": "CAN9_GnssPos",
"signal": ["Latitude", "Longitude"],
"aggregation": ["first", "last"]
}
]
}
}
]
}
```
- **config**: Top-level configuration section
- **date**: Date range configuration
- **mode**: Either `specific_period` (use explicit dates) or `previous_day` (automatic)
- **start_date/end_date**: Required for `specific_period` mode (format: YYYY-MM-DD)
- **trip**: Trip detection parameters
- **trip_gap_min**: Minutes of inactivity to consider a new trip has started
- **trip_min_length_min**: Minimum trip length in minutes to be considered valid
- **device_clusters**: Group devices into logical clusters (e.g. by business logic)
- **devices**: List of device IDs (serial numbers) to process (if empty, all devices are processed)
- **cluster**: Name assigned to this group of devices
- **cluster_details**: Processing configuration for each cluster
- **clusters**: List of cluster names to apply these settings to
- **details**: Processing configuration
- **trip_identifier**: Message used to identify trips
- **aggregations**: List of signals to aggregate
- **message**: Parquet data lake message folder name[1](#fn-message-names)
- **signal**: List of signal names to aggregate
- **aggregation**: List of aggregation functions[2](#fn-default-aggregations)
#### NOTE
Using `specific_period` is ideal for testing/backlog processing, while `previous_day` is useful for daily scheduled automation (more below)
---
## How to run
### Amazon
1. Open [AWS Glue Triggers](https://console.aws.amazon.com/glue/home?#/v2/etl-configuration/triggers) in a new tab
2. Select the ‘process-aggregation-on-demand’ trigger and click ‘Action/Start trigger’
3. View output logs by clicking the target job and the ‘Runs’ tab
4. To schedule the job daily, activate the ‘process-aggregation-scheduled’
### Google
1. Open [Cloud Scheduler](https://console.cloud.google.com/cloudscheduler) in your browser
2. Select ‘aggregation-scheduler’, click `RESUME` and `FORCE RUN`
3. After it completes, click `PAUSE`
4. View output logs via the ‘aggregation’ function Logs/ tab in the [console (runs)](https://console.cloud.google.com/run)
5. To schedule the job daily, click `RESUME` on the scheduler
### Azure
1. Open your ‘aggregation’ Container App Job via the [console (jobs)](https://portal.azure.com/#browse/Microsoft.App%2Fjobs)
2. Click ‘Run now’ (at the top) and then click the execution history
3. View output logs via the execution console logs (may be delayed up to 15 min)
#### NOTE
When scheduling a daily job, make sure to set the `mode` to `previous_day` in your JSON
#### NOTE
If the job results in new devices/messages in your data lake, re-run your table mapping job
#### NOTE
The max run-time for a job is 60 min. For large backlogs, process a subset in each run
You can now e.g. visualize this data via our [Grafana](../../browser-dashboards.md#ref-dashboards) trip summary dashboard templates.
---
* **[1]** Message and signal names are case sensitive and must be entered correctly. We recommend copy/pasting the message names directly from the relevant folders of your data lake as they must be named identically to the folders (do not copy them from the DBC file, for example) - and to copy paste the signal names by copying them from a Parquet file within the relevant message folder (you can use the free Tad Parquet file viewer for this). Alternatively, you can copy the signal names from your DBC file
* **[2]** The default script supports the following aggregation methods: `min`, `max`, `avg`, `median`, `sum`, `first`, `last`, `delta_sum`, `delta_sum_pos`, `delta_sum_neg`. The delta sums are calculated by summing the delta signal values, optionally filtering for only positive or negative deltas. You can easily expand the list by modifying the script accordingly
# index.html.md
# Add event detection with email notifications
In this section we explain how you can enable [event detection](https://www.csselectronics.com/pages/can-bus-signal-alert-event-dashboard) in your Amazon/Google/Azure cloud function (e.g. active DTCs, high temperatures, harsh braking, …). Users can be notified via email and the events can be visualized via our [Grafana](../../browser-dashboards.md#ref-dashboards) event summary dashboard. This is useful in e.g. predictive maintenance and diagnostics.
> ##### Table of Contents
>
> * [Add event detection via JSON file](#add-event-detection-via-json-file)
> * [How it works](#how-it-works)
> * [JSON syntax](#json-syntax)
> * [Hysteresis intervals](#hysteresis-intervals)
> * [Examples](#examples)
> * [Example 1: J1939 DM1 DTCs](#example-1-j1939-dm1-dtcs)
> * [Example 2: Multiple tire pressures](#example-2-multiple-tire-pressures)
> * [Email notifications](#email-notifications)
---
## Add event detection via JSON file
To detect custom signal events via your cloud function, follow below steps:
1. Ensure you are using the latest cloud function
2. Download our example `events.json` below and modify it as per your needs
3. Once ready, upload it to your input bucket root
[`events.json`](/_static/files/log-file-tools/mdf4-decoders/automation-json-files/events.json)
### How it works
Adding the `events.json` to your input bucket will add the following cloud function behavior:
1. The function will download and validate your `events.json` file
2. For each event entry, it loads the trigger message(s) in `messages_filtered_list` into a data frame
3. It determines if/when the event occurs in the file based on specified signal thresholds
4. If events occur, meta info is added to your Parquet data lake (incl. optionally GPS data[1](#fn-gps-data))
5. Once per file/event, the function will send an email notification to the user[2](#fn-notifications)
*Below is an illustration of the function for identifying high speed events:*
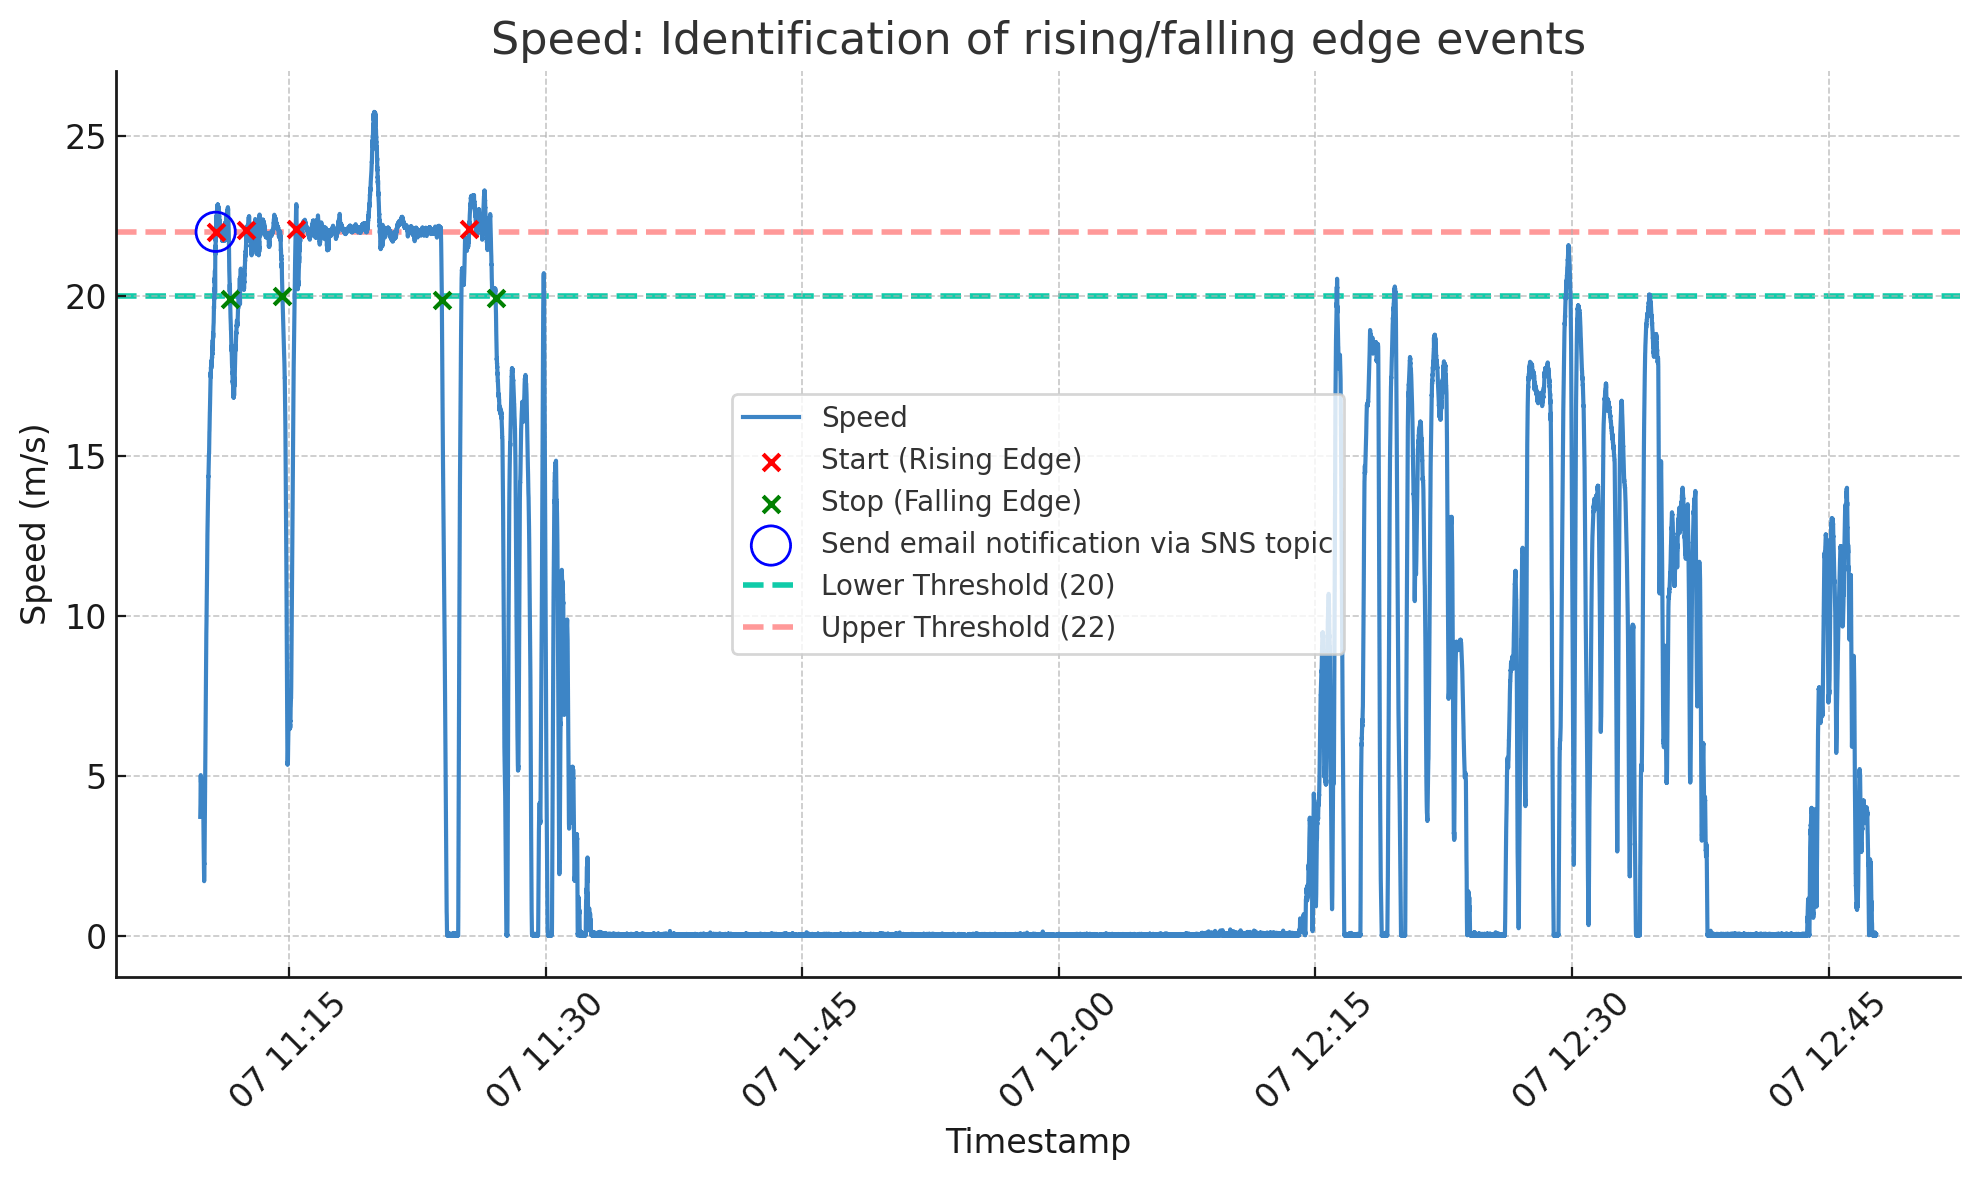
### JSON syntax
To illustrate the JSON syntax, consider the default example below:
```json
{
"general": {
"include_gps_data": true,
"signal_latitude": "Latitude",
"signal_longitude": "Longitude",
"messages_gps": ["CAN9_GnssPos"],
"static_body_content": "Review details via your event dashboard"
},
"events": [
{
"event_name": "HighSpeedAlert",
"messages_match_type": "equals",
"messages_filtered_list": [["CAN9_GnssSpeed"]],
"trigger_signals": ["Speed"],
"lower_threshold": 5,
"upper_threshold": 10,
"rising_as_start": true,
"exact_match": false,
"raster": "0.2s"
},
{
"event_name": "DM01_DTC_01_Active",
"messages_match_type": "contains",
"messages_filtered_list": "_DM01_DTC_01",
"trigger_signals": ["DM01_OC"],
"lower_threshold": 0,
"upper_threshold": 1,
"rising_as_start": true,
"exact_match": false,
"raster": "1s"
}
]
}
```
The `general` section lets you specify what CAN message/signals to use for the event GPS position data - as well as a custom message to be included in email notifications.
The `events` section contains a list of your custom events, each with an `event_name`.
The `messages_filtered_list` reflects the CAN messages that contain the event `trigger_signals`. If `messages_match_type` equals `"exact"`, the exact list of CAN messages specified is evaluated. If it equals `"contains"`, the `messages_filtered_list` should equal a string (not a list) and the event then includes all CAN messages which contain this string in their name. The function loops through each event, message and trigger signal combination as part of the evaluation.
The event detection is evaluated based on ‘rising/falling edges’. For example, a ‘rising edge’ start event (`"rising_as_start" = true`) is defined as an event where `trigger_signal >= upper_threshold` after `trigger_signal <= lower_threshold` in the period since the last event within the log file[3](#fn-log-file-size).
If `exact_match` is true, the signal must equal a specific threshold value to be triggered (e.g. for state-type signals). The `raster` allows optional resampling (e.g. to reduce jittery behavior).
### Hysteresis intervals
For continuous signals (e.g. temperature, speed) we recommend using a hysteresis interval by adding a gap between the values of `upper_threshold` and `lower_threshold`. This helps event detection when your trigger signal fluctuates around your `upper_threshold`.
For boolean signals you can e.g. set `lower_threshold = 0` and `upper_threshold = 1`. For multi-value state signals, you can use `"exact_match": true`.
---
## Examples
### Example 1: J1939 DM1 DTCs
A common message of interest for alerts and event identification is the J1939 DM1 message containing Diagnostic Trouble Code (DTC) information. The default `events.json` example will evaluate all DM01 messages (across all CAN channels and source addresses) to check if the 1st DTC occurrence count goes from 0 to 1 (or higher), reflecting the activation of the 1st DTC.
### Example 2: Multiple tire pressures
You can specify multiple trigger signals per message. For example, you may have a message with 4 tire pressure signals (one per wheel). By adding all of them in the `trigger_signals` list, the code will evaluate each signal based on the same event settings.
---
## Email notifications
By default, if the function detects a ‘start event’ in a decoded file, it publishes a message to the email used during the Parquet data lake deployment. To modify/disable this, proceed as follows:
- Amazon: Modify the event alert in [SNS subscriptions](https://console.aws.amazon.com/sns/v3/home?#/subscriptions)
- Google: Modify the event alert in [Alerting](https://console.cloud.google.com/monitoring/alerting?)
- Azure: Modify the event alert in your [resource group](https://portal.azure.com/#browse/resourcegroups)
#### WARNING
We **strongly recommend** to test your `events.json` before deployment to production[4](#fn-email-alerts)
---
* **[1]** GPS data is a ‘nice-to-have’ meta information that helps you better understand and browse events. The example function will attempt to add GPS data (if found), but the GPS data is not ‘required’ to perform the event identification
* **[2]** The event email alert functionality differs slightly between Amazon/Google/Azure and you can to some extent control the behavior of when emails are sent (e.g. to cap the number of emails per time period)
* **[3]** Importantly, the function does not have information beyond the trigger MDF log file. As a result, the example function cannot identify transitions that occur *between* log files. For example, it may be that `trigger_signal < lower_threshold` near the end of log file 1. Log file 2 may then start with `lower_threshold < trigger_signal < upper_threshold` and later go to `trigger_signal > upper_threshold`. In such a scenario, a ‘rising edge’ event occurred - but the function will not detect it. To minimize such ‘false negative’ events we recommend that you avoid using high-frequent file splitting. Alternatively, you can incorporate basic state management by storing the last value of `trigger_signal` in a object on S3 (unique per device) and fetching this as part of the function
* **[4]** If you make errors in your `events.json` or your data exhibits unexpected behavior, you can end up sending an email notification for every log file processed - which can be inconvenient to clean up in your inbox
# index.html.md
# Process backlog of MDF files

Below we describe how you can add historical MDF log files to your Parquet data lake.
#### NOTE
Optionally, you can periodically delete your Parquet data lake and re-create as below. This will concatenate smaller files, which can improve processing speed
#### WARNING
Processing a large input bucket/container backlog may be time consuming and costly - start with a small backlog during initial testing
> ##### Table of Contents
>
> * [Process backlog via JSON file](#process-backlog-via-json-file)
> * [How it works](#how-it-works)
> * [JSON syntax](#json-syntax)
> * [How to run](#how-to-run)
> * [Amazon](#amazon)
> * [Google](#google)
> * [Azure](#azure)
> * [Tips & tricks](#tips-tricks)
---
## Process backlog via JSON file
To process a backlog of MDF files to Parquet in your cloud, follow below steps:
1. Ensure you are using the latest data lake integration
2. Download our example `backlog.json` below and modify it as per your needs
3. Once ready, upload it to your input bucket root
4. Trigger the backlog processing as outlined for your specific cloud below
[`backlog.json`](/_static/files/log-file-tools/mdf4-decoders/automation-json-files/backlog.json)
### How it works
When you run the backlog processing job, it will do the following:
1. The script will download and validate your `backlog.json` file
2. It will group the log file objects you’ve specified into suitable batches
3. It then runs the same processing as your cloud automation function on each batch[1](#fn-event-detection)
### JSON syntax
To illustrate the JSON syntax, consider the example below:
```json
{
"config": {
"batch_size": {
"min": 10,
"max": 256
}
},
"files": [
"2F6913DB/",
"ABCDEF12/00000088/",
"2F6913DB/00000086/00000001-62961868.MF4",
"2F6913DB/00000086/00000003-62977DFB.MF4"
]
}
```
The `batch_size` parameters let you control the grouping of files. For example, if you have a lot of sessions with 1-2 files, setting a minimum batch size of 10 will allow the script to group up to 10 log files across sessions into a single batch. Files are never grouped across devices. If you have many small files, you may consider increasing the minimum batch size.
The `files` list contains the list of files you wish to process in a specific run. You can specify these at the device ID level, session level or object level - or a mix of these.
---
## How to run
### Amazon
1. Open [AWS Glue Triggers](https://console.aws.amazon.com/glue/home?#/v2/etl-configuration/triggers) in a new tab
2. Select the ‘process-backlog-on-demand’ trigger and click ‘Action/Start trigger’
3. View output logs by clicking the target job and the ‘Runs’ tab
### Google
1. Open [Cloud Scheduler](https://console.cloud.google.com/cloudscheduler) in your browser
2. Select ‘mdf-to-parquet-backlog-scheduler’, click `RESUME` and `FORCE RUN`
3. After it completes, click `PAUSE`
4. View output logs via the ‘mdf-to-parquet-backlog’ function Logs/ tab in the [console (runs)](https://console.cloud.google.com/run)
### Azure
1. Open your ‘backlog’ Container App Job via the [console (jobs)](https://portal.azure.com/#browse/Microsoft.App%2Fjobs)
2. Click ‘Run now’ (at the top) and then click the execution history
3. View output logs via the execution console logs (may be delayed up to 15 min)
#### NOTE
If the job results in new devices/messages in your data lake, re-run your table mapping job
#### NOTE
The max run-time for a job is 60 minutes. For large backlogs, process a subset in each run
---
## Tips & tricks
If you are processing files that have already been processed individually via your cloud automation function, it is recommended to first delete the original Parquet files related to those files from your output bucket. They will not automatically be overwritten when the backlog processing runs because the backlog process will combine multiple Parquet files when possible for efficiency.
---
* **[1]** The backlog processing essentially re-uses the same code that the single-file automation functions do (e.g. the Amazon Lambda). This means that if you have e.g. enabled event detection, custom signals or device specific DBC files, the backlog processing will also incorporate these. However, for event detection specifically, the backlog processing script will disable notifications (to avoid excessive notifications about historical events)
# index.html.md
# Customize your cloud function
In some use cases you may need to add custom code to your cloud function automation. This can e.g. be used to create custom Parquet tables with [calculated signals](custom-signals.md#ref-parquet-data-lake-advanced-custom-signals) or writing data to [external endpoints](external-database.md#ref-parquet-data-lake-advanced-external-database) (e.g. databases).
> ##### Table of Contents
>
> * [When to use custom cloud functions](#when-to-use-custom-cloud-functions)
> * [How the default cloud function works](#how-the-default-cloud-function-works)
> * [How to customize your cloud function and redeploy](#how-to-customize-your-cloud-function-and-redeploy)
---
## When to use custom cloud functions
Before you start customizing your cloud function, consider if it is the best way to achieve your intended goal. Generally, a cloud function is useful in below situations:
* If the processing has to be done *immediately upon file upload*
* If the processing has to be done on *all of your data*
* If the processing can be done *file-by-file*[1](#fn-file-by-file)
---
## How the default cloud function works
To customize your cloud function, it is useful to understand the ‘default’ workflow:
1. The function downloads the trigger MDF log file and various files (e.g. DBCs)
2. It uses `mdf2parquet_decode` to DBC decode the data into Parquet files
3. It may do message customization and event detection (if required JSON files are found)
4. It runs the function `process_decoded_data` on the Parquet data (by default uploading files to S3)
---
## How to customize your cloud function and redeploy
You may want to update certain files in this workflow, e.g. `custom_message_functions.py` (to add [custom messages](custom-signals.md#ref-parquet-data-lake-advanced-custom-signals)) or `functions.py` (to e.g. [push data to an external endpoint](external-database.md#ref-parquet-data-lake-advanced-external-database) instead of your output bucket). To do this, go through the below steps:
1. Download the cloud function zip from your input bucket and unzip it
2. Customize the code as needed, then re-zip the files correctly[2](#fn-zipping)
3. Redeploy your cloud function
In Amazon, you can follow our guide to [update your deployed Lambda function](../update-glue.md#ref-update-glue). In Google/Azure, you can update the zip name (e.g. change the last version digit) before uploading it to your input bucket/container. After this, you can re-run the Terraform deployment script with your revised function zip name.
---
* **[1]** For example, Lambda functions are not useful for performing analyses that need to aggregate data across devices, trips, days or similar as this involve multiple log files (and may exceed the max Lambda function timeout). For such use cases, a periodic Glue job is better suited (see our [trip summary](aggregation.md#ref-parquet-data-lake-advanced-trip-summary) section as an example)
* **[2]** Make sure that you include all the required files in the zip and that you do not e.g. zip a folder containing the files. If you are using Windows 11 rather than Windows 10, you may experience issues with the zip method. If so, try creating an empty zip folder and moving the files into that instead
# index.html.md
# Add calculated signals to your data lake

In this section we explain how you can customize your Amazon/Google/Azure cloud function to create custom messages - and output the results as Parquet files in your data lake.
> ##### Table of Contents
>
> * [Add calculated signals via Grafana and/or SQL](#add-calculated-signals-via-grafana-and-or-sql)
> * [Add calculated signals via cloud function](#add-calculated-signals-via-cloud-function)
> * [How it works](#how-it-works)
> * [JSON syntax](#json-syntax)
> * [Python syntax](#python-syntax)
> * [Examples](#examples)
> * [Example 1: Combine J1939 DM1 messages](#example-1-combine-j1939-dm1-messages)
> * [Example 2: Add custom geofences](#example-2-add-custom-geofences)
> * [Example 3: Combine select messages](#example-3-combine-select-messages)
> * [Example 4: Combine all messages](#example-4-combine-all-messages)
---
## Add calculated signals via Grafana and/or SQL
If you are using [Grafana](../../browser-dashboards.md#ref-dashboards), you can handle **90%+** of custom signal calculations via Grafana’s powerful transformations and/or by customizing your SQL queries.
#### NOTE
We recommend to review if your custom signals can be handled in the frontend before proceeding - feel free to contact us for sparring
---
## Add calculated signals via cloud function
If your custom signals cannot be handled in the frontend, you can instead create new Parquet data lake tables that contain your calculated signals, moving the processing to your backend.
To create a custom signal table via your cloud function, follow below steps:
1. Download our example `custom-messages.json` below and modify it as per your needs
2. Once ready, upload it to your input bucket root
3. If required, download your cloud function zip, modify the `custom_message_functions.py` and [deploy your customized cloud function](custom-function.md#ref-parquet-data-lake-advanced-custom-function)
[`custom-messages.json (J1939 DM1 example)`](/_static/files/log-file-tools/mdf4-decoders/automation-json-files/custom-messages.json)
#### NOTE
The default cloud function includes some built-in functions that do not require customizing the cloud function (see examples below)
### How it works
Adding the `custom-messages.json` to your input bucket will add the following cloud function behavior:
1. The function will download and validate your `custom-messages.json` file
2. For each entry, it loads the message(s) in `messages_filtered_list` into a data frame
3. It determines if/when the event occurs in the file based on specified signal thresholds
4. It optionally resamples the data frame (required for cross-message calculations)
5. The data frame is parsed to the `custom_message_functions.py` in the cloud function
6. The matching ‘function’ code is applied to create the custom message
7. The new custom Parquet file is uploaded to the output bucket
#### NOTE
Make sure to use valid custom message/signal names[1](#fn-names)
### JSON syntax
To illustrate the JSON syntax, consider the example below:
```json
[
{
"messages_filtered_list": [["CAN9_GnssSpeed", "CAN9_GnssDistance"]],
"messages_match_type": "equals",
"raster": "0.2s",
"custom_message_name": "CAN9_CALC_GnssDeltaDistance",
"prefix": false,
"function": "delta_distance"
}
]
```
For each entry you specify a `custom_message_name`. The `messages_filtered_list` reflects the CAN messages that will be parsed to your custom function. If `messages_match_type` is `"equals"`, the exact list of CAN messages specified is evaluated. If it equals `"contains"`, the `messages_filtered_list` should equal a string (not a list) and the event then includes all CAN messages which contain this string in their name. You can set a `raster` to resample the messages before applying the custom calculations.
The `prefix` lets you control whether you wish to update the signal names to include the message name as a prefix (this may be required for uniqueness). The `function` lets you specify what function should be applied to the data within the `custom_message_functions.py` script.
### Python syntax
The `custom_message_functions.py` can be modified to create practically any customized logic you prefer. Below is a built-in example related to the JSON entry above:
```python
# Example 3: Add trip distance delta signals
if function == "delta_distance":
df_messages['DeltaDistance'] = df_messages['DistanceTrip'].diff()
df_messages["DeltaDistanceHighSpeed"] = df_messages['DeltaDistance'].where((df_messages['Speed'] > 20) & (df_messages['SpeedValid'] == 1), None)
df_messages["DeltaDistanceLowSpeed"] = df_messages['DeltaDistance'].where((df_messages['Speed'] <= 20) & (df_messages['SpeedValid'] == 1), None)
signals_to_include = ["DeltaDistance","DeltaDistanceHighSpeed","DeltaDistanceLowSpeed"]
df_messages = df_messages[signals_to_include]
df_messages = df_messages[(df_messages.notnull()).any(axis=1)]
```
---
## Examples
### Example 1: Combine J1939 DM1 messages
Visualizing the J1939 Diagnostic Message 1 (DM1) in e.g. Grafana is normally complex as explained in our [J1939-73 intro](https://www.csselectronics.com/pages/j1939-73-dm1-diagnostic-message-dtc) and our [J1939 protocol guidance](../../../record-data/j1939-data.md#ref-record-j1939-data). This is because the DM1 data is split across multiple tables (per source addresses and DTC). To solve this, the default cloud function supports the custom function `combine_dtcs` that combines all DM1 messages into a single table per CAN channel. To add this custom table to your data lake, simply add the ready-to-use `custom-messages.json` from above to your input bucket (no cloud function customization required).
```json
[
{
"messages_filtered_list": "CAN1_DM01_DTC_",
"messages_match_type": "contains",
"raster": "",
"custom_message_name": "CAN1_CALC_DM01",
"prefix": false,
"function": "combine_dtcs"
}
]
```
### Example 2: Add custom geofences
The built-in `custom_geofences` function can be used to evaluate when your CANedge enters/exits custom geofence areas. To leverage this, you first upload a `geofences.json` file with syntax as below to your input bucket/container:
```json
[
{
"id": 1,
"name": "Home Base",
"latitude": 56.072706,
"longitude": 10.103398,
"radius": 0.2
},
{
"id": 2,
"name": "Service Center",
"latitude": 56.116626,
"longitude": 10.154564,
"radius": 0.3
}
]
```
Here the syntax is as follows:
- **id**: Numeric identifier for the geofence (used in the GeofenceId output signal)
- **name**: Descriptive name for the geofence
- **latitude**: Geographic latitude in decimal degrees (-90 to 90)
- **longitude**: Geographic longitude in decimal degrees (-180 to 180)
- **radius**: Radius of the geofence in kilometers (must be greater than 0)
Next, you can add the below to your `custom-messages.json` file. The script will now create a new Parquet table with the geofence status.
```json
[
{
"messages_filtered_list": [["CAN9_GnssPos"]],
"messages_match_type": "equals",
"raster": "0.2s",
"custom_message_name": "CAN9_CALC_CustomGeofences",
"prefix": false,
"function": "custom_geofences"
}
]
```
### Example 3: Combine select messages
You can create a single table that combines all signals across multiple messages with a shared timestamp. This can be done by using the below example JSON entry. The `"resample"` function is supported by the default cloud function.
```json
[
{
"messages_filtered_list": [["CAN1_Message1", "CAN1_Message2", "CAN1_Message3"]],
"messages_match_type": "equals",
"raster": "0.5s",
"custom_message_name": "CAN1_CALC_Combined123",
"prefix": false,
"function": "resample"
}
]
```
#### NOTE
This message is only created if all listed messages are found in the underlying data
### Example 4: Combine all messages
As a special case, you can use a variation of the above to create a single message that contains all your signals across all your messages. In this case, the `prefix` should typically be set to `true` to ensure column uniqueness.
```json
[
{
"messages_filtered_list": [[]],
"messages_match_type": "all_messages",
"raster": "1s",
"custom_message_name": "ALL_DATA_RESAMPLED",
"prefix": true,
"function": "resample"
}
]
```
#### WARNING
This example should only be used ‘ad hoc’ and not for cloud based integrations[2](#fn-column-structure)
---
* **[1]** See e.g. the [Athena naming guidelines](https://docs.aws.amazon.com/athena/latest/ug/tables-databases-columns-names.html) for tables (aka messages) and columns (aka signals)
* **[2]** This is because the Parquet data lake interfaces rely on each Parquet table having a consistent schema across all files - meaning the column structure must be identical. If you use the special case of ‘resampling all messages’, it will result in inconsistent Parquet files when one log file is e.g. lacking some CAN messages vs. another log file
# index.html.md
# Use device specific DBC files

You may have an Amazon/Google/Azure bucket/container that contains multiple device groups, each of which requires separate DBC files. Here you can use the below method[1](#fn-conflicting-dbc-ids):
1. Download below `dbc-groups.json` and update it with your device/DBC lists
2. Upload the JSON file to your input bucket/container root
3. Ensure that your log files are stored in the CANedge folder structure
4. Verify that your automation now only applies the device specific DBC files
[`dbc-groups.json`](/_static/files/log-file-tools/mdf4-decoders/automation-json-files/dbc-groups.json)
---
* **[1]** If all device groups have globally unique CAN IDs across all DBC files, you can simply add all the DBC files to the S3 input bucket root. In this case, the MF4 decoder will attempt to use all of them across all devices
# index.html.md
# Write data to external database

In this section we explain how you can customize your cloud function to write data to an external database via REST, enabling you to integrate your data with practically anything.
> ##### Table of Contents
>
> * [Write data to external database](#id1)
> * [REST vs. Python clients](#rest-vs-python-clients)
---
## Write data to external database
To write data to an external database, follow below steps:
1. Follow the steps to set up a [custom cloud function](custom-function.md#ref-parquet-data-lake-advanced-custom-function)
2. Update the `functions.py` to load the Parquet file(s) with pyarrow into a data frame[1](#fn-load-parquet-to-df)
3. Add your external database writing logic, then redeploy your function and test it
#### NOTE
You can use the built-in [custom message functionality](custom-signals.md#ref-parquet-data-lake-advanced-custom-signals) to resample all your data to a single Parquet to simplify your database injection code
---
## REST vs. Python clients
The example takes outset in the REST API for writing data, which is supported by most databases for data ingestion. Many databases also offer a ‘Python client’ which you can alternatively use - but in this case notice that you will need to create an ARN layer to enable support for the library.
Alternatively, you may be able to leverage the existing functionality within the AWS SDK ARN layer as per their [API documentation](https://aws-sdk-pandas.readthedocs.io/en/2.16.1/api.html). Examples of supported databases are below:
* Amazon Redshift
* PostgreSQL
* MySQL
* Microsoft SQL Server
* DynamoDB
* Amazon Timestream
---
* **[1]** see the utils.py function `load_parquet_to_df` for this purpose
# index.html.md
# Route data to client-specific output buckets

An OEM/integrator serving multiple end clients can route each device’s decoded data into a client-specific output bucket, so each client only sees their own decoded data. It is a layer on top of the standard [Amazon Parquet data lake](../parquet-data-lake/amazon.md#ref-parquet-data-lake-aws) deployment.
You could instead duplicate the standard deployment once per client, but a routed setup may be preferable in some scenarios:
1. Devices switch between clients over time (reassign them in `routing.json`, no data migration)
2. An in-house team wants a full-fleet view (via the default bucket) alongside client-specific views
#### WARNING
This is an advanced setup - we strongly recommend contacting us before you deploy it
#### NOTE
Routing is currently supported on Amazon only
> ##### Table of Contents
>
> * [Prerequisites](#prerequisites)
> * [Route data via routing JSON](#route-data-via-routing-json)
> * [Deploy a client-specific data lake (per client)](#deploy-a-client-specific-data-lake-per-client)
> * [Visualize per client in Grafana](#visualize-per-client-in-grafana)
---
## Prerequisites
Routing is a layer on top of the standard automation, not a replacement:
1. [Set up the Amazon Parquet data lake](../parquet-data-lake/amazon.md#ref-parquet-data-lake-aws) on the latest stack [~10 min]
---
## Route data via routing JSON
Upload a `routing.json` to your input bucket root, mapping each device serial to a client output bucket and start date:
[`routing.json`](/_static/files/log-file-tools/mdf4-decoders/automation-json-files/routing.json)
```json
{
"config": {
"mirror_to_default": true
},
"devices": {
"C077F30F": {
"output_bucket": "oem-name-clienta-parquet",
"from_date": "2026-04-05"
},
"6BBAD09E": {
"output_bucket": "oem-name-clientb-parquet",
"from_date": "2026-02-01"
}
}
}
```
For each decoded file the function then writes:
1. To the client `output_bucket` if the device’s recording date is on/after `from_date`
2. Otherwise to the default catch-all bucket
`from_date` is the recording date (not the upload date)[1](#fn-handover). Each `output_bucket` must be named `--parquet` and must already exist (see below).
The global `mirror_to_default` flag sets whether routed data is also copied to the default bucket:
1. `false` (default): Matched devices go to their client bucket only
2. `true`: Matched devices go to their client bucket and the default bucket[2](#fn-mirror)
---
## Deploy a client-specific data lake (per client)
Each client gets their own output bucket, Glue database and Athena workgroup. The table-mapping Glue script is the same shared script, just run per client, so each client gets an isolated `dbparquet` database with only their own tables.
Deploy the client stack once per client:
1. Open [AWS CloudFormation](https://console.aws.amazon.com/cloudformation) and ensure you are in the same region as your input bucket
2. Click ‘Create stack/With new resources (standard)’
3. Under ‘Specify template’, select ‘Amazon S3 URL’ and enter below:
```text
https://css-electronics-resources.s3.eu-central-1.amazonaws.com/stacks/create-customer-output-v1.0.0.json
```
1. Enter a ‘Stack name’ (e.g. `datalake-clienta`)
2. Enter a brief customer name in ‘CustomerName’ (e.g. `clienta`)[3](#fn-client-name)
3. Enter your existing S3 input bucket name as ‘InputS3BucketName’
4. Click ‘Next’, ‘Acknowledge’ the IAM resources, ‘Submit’ and wait ~1-2 min
This creates the client output bucket `--parquet` (used in the `routing.json`), a Glue database `dbparquet` + Athena workgroup `athenaworkgroup-`, and a client-scoped Athena access user (whose keys you use in that client’s Grafana).
Finally, run that client’s `-map-tables` Glue job to (re)create its tables; re-run it when new devices/messages appear.
---
## Visualize per client in Grafana
For each client, create a new dedicated Amazon Athena data source using that client’s access keys (from the client stack), named e.g. `amazon-athena-`. Then build that client’s dashboards on top of their own data source[5](#fn-dashboard-source). Further, you can create client-specific read-only users in Grafana with access to the client specific dashboards so each client only sees their own data.
The free Grafana Cloud tier is fine for initial testing. For production, we recommend self-hosting Grafana and deploying data sources, dashboards and users via e.g. Python for scalability[4](#fn-grafana).
---
* **[1]** `from_date` enables seamless client handovers. If a device moves from client A to client B on a given date, set that device’s `output_bucket` to client B’s bucket with `from_date` set to the handover date. In this case, data recorded from then on goes to client B, while earlier data stays with client A (or lands in the default catch-all if unmapped). Historic data is thus not retroactively exposed to a new client.
* **[2]** Mirroring lets in-house engineers and OEM/integrator admins see all devices in one data lake (the default bucket) while each client still sees only their own. Catch-all data (devices with no client bucket) is always written to the default bucket exactly once - it is never duplicated. Mirroring stores matched data twice, so the default bucket incurs extra S3 storage/API cost.
* **[3]** Use only lowercase letters and numbers for the client name - it feeds the bucket name, the Glue database `dbparquet` and the Athena workgroup, which each have different character rules.
* **[4]** The free Grafana Cloud tier is convenient for initial testing but limited for multi-client production use. Specifically, it is harder to strictly separate each client’s data and dashboards, and there are limits on the number of separate user accounts. Self-hosting Grafana (or using a managed 3rd-party host) lets you give each client their own organization/users with proper isolation.
* **[5]** Our default [Grafana-Athena dashboard](../../browser-dashboard/grafana-athena/customize-dashboard.md#ref-customize-athena-dashboard) templates reference a data source named `Amazon Athena`. To reuse a template for a client, open its JSON in e.g. Notepad++ and replace the data source name with the client-specific one (e.g. `amazon-athena-`).
# index.html.md
# Customize your dashboard
With your first Grafana-Athena dashboard in place, you can now start customizing.
Grafana has a [tutorial](https://grafana.com/docs/grafana/latest/panels-visualizations/) on panels, so we mainly focus on some of the basics. You can also find inspiration via our [dashboard playgrounds](https://grafana.csselectronics.stellarhosted.com/d/obd2-gps-car/obd2-gps-car).
> ##### Table of Contents
>
> * [Templates - getting started](#templates-getting-started)
> * [Templates - advanced](#templates-advanced)
> * [Variables](#variables)
> * [Create a new panel](#create-a-new-panel)
> * [Optimize performance](#optimize-performance)
> * [Transformations](#transformations)
> * [Advanced SQL queries](#advanced-sql-queries)
> * [Custom signals, trip summaries and alerts](#custom-signals-trip-summaries-and-alerts)
> * [Grafana Assistant (AI)](#grafana-assistant-ai)
---
## Templates - getting started
We recommend that you load one of the below templates to get started:
### Simple dynamic dashboard
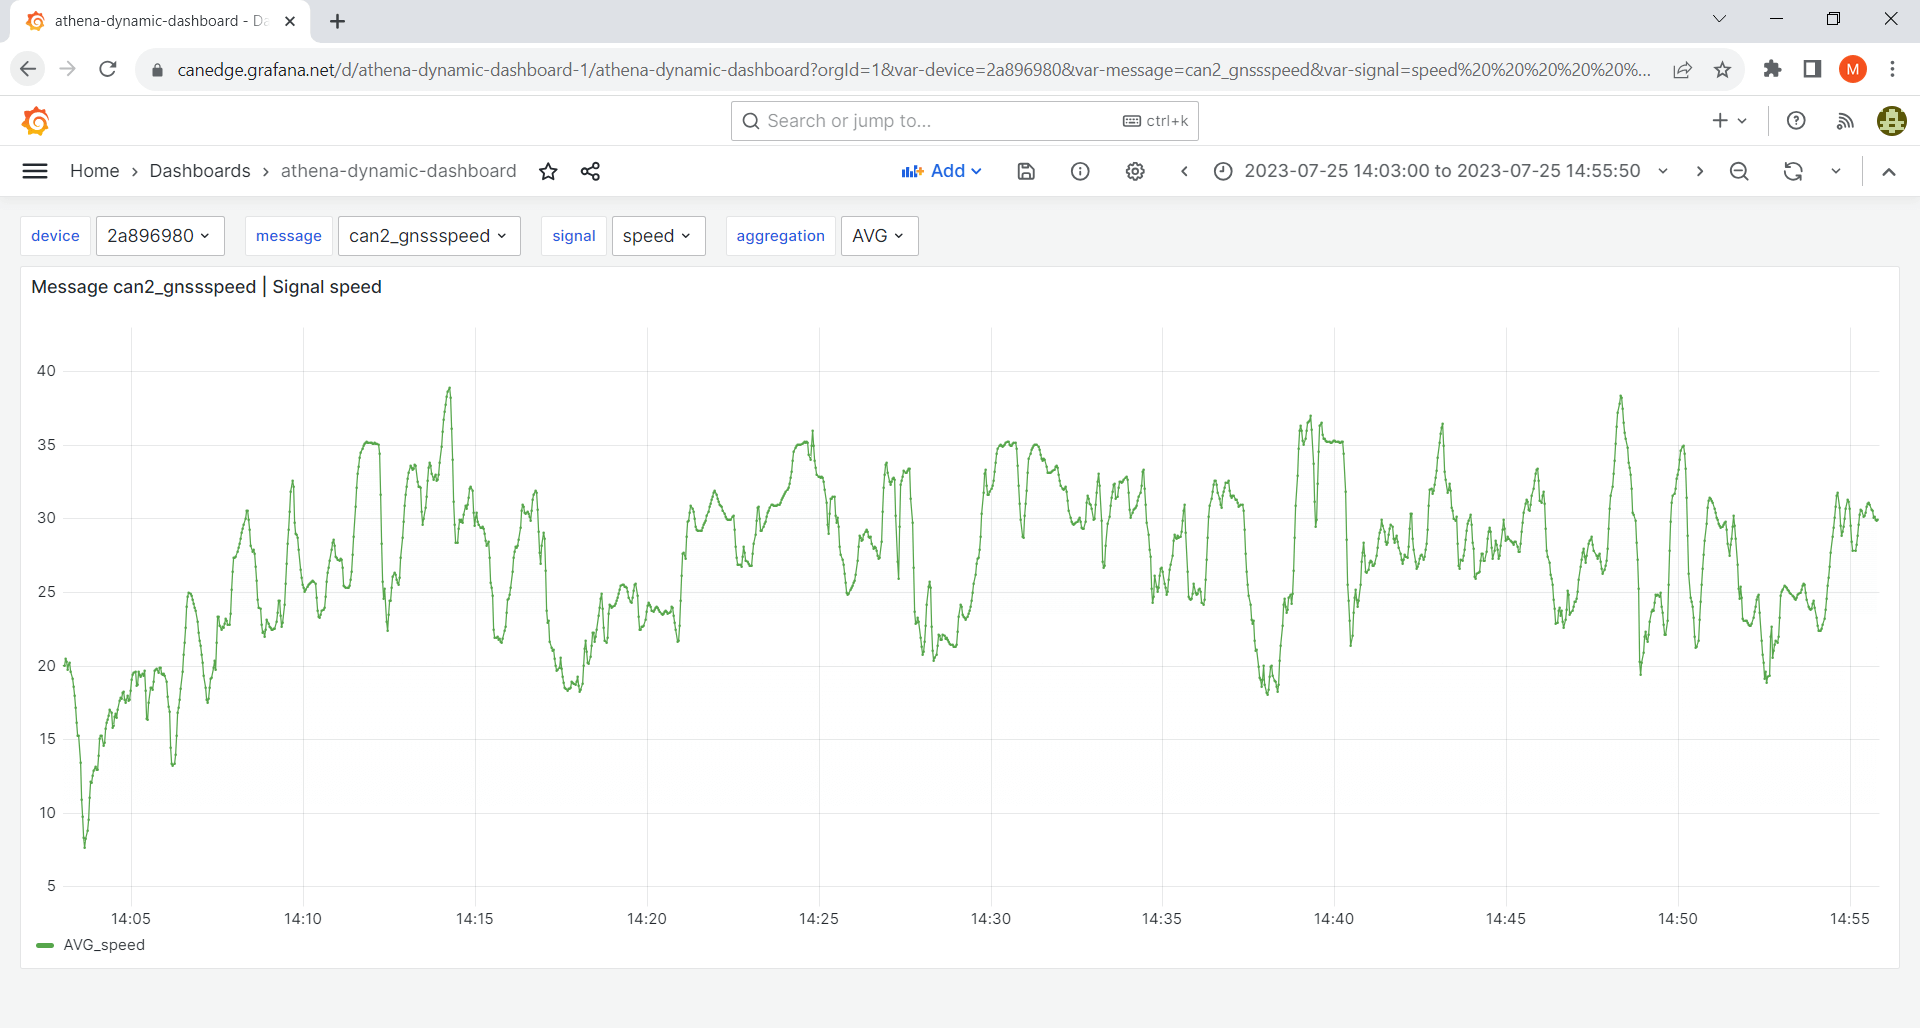
This template works for any CAN/LIN dataset and serves as a good starting point.
[`athena-dynamic-dashboard template`](/_static/files/log-file-tools/grafana-athena/templates/athena-dynamic-dashboard-template.json)
### GPS/IMU dashboard
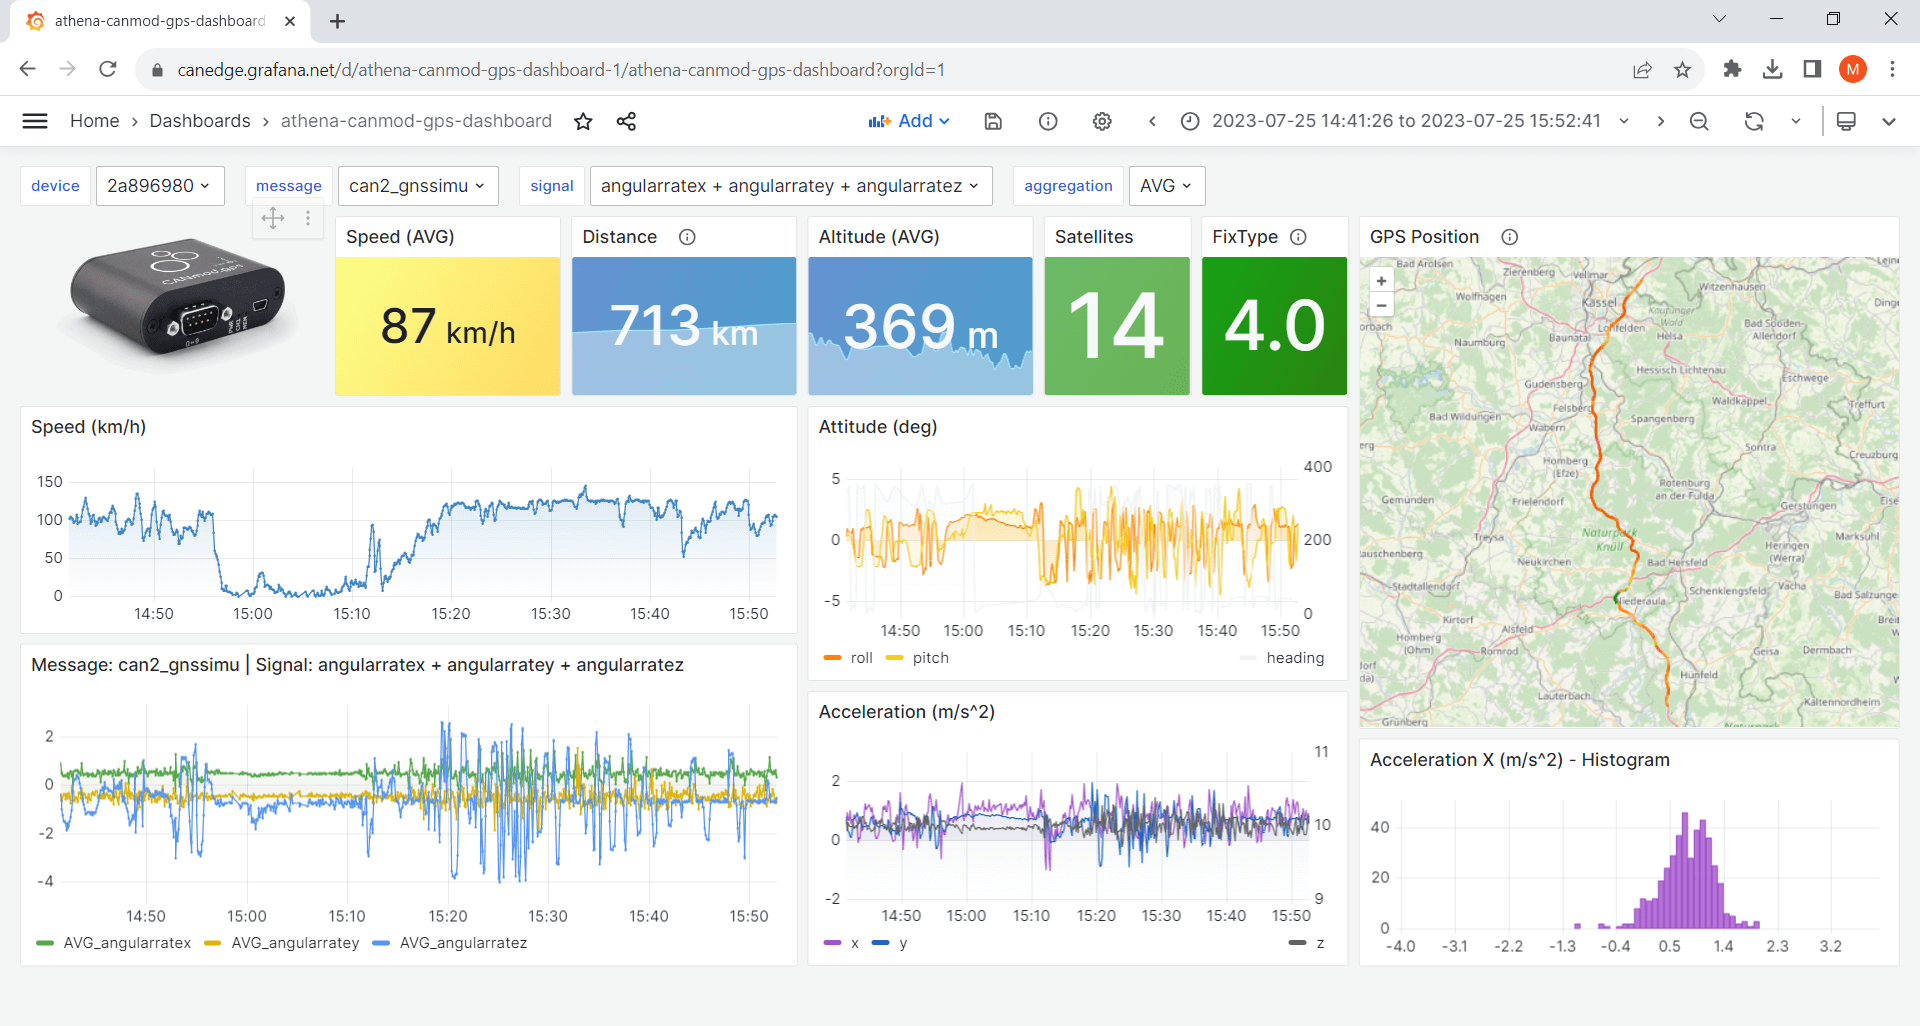
Ideal if you have a CANedge incl. GPS/IMU or CANmod.gps[1](#fn-geomap).
[`athena-internal-gps-dashboard template`](/_static/files/log-file-tools/grafana-athena/templates/athena-internal-gps-dashboard-template.json)
[`athena-canmod-gps-dashboard template`](/_static/files/log-file-tools/grafana-athena/templates/athena-canmod-gps-dashboard-template.json)
---
## Templates - advanced
### Trip summary dashboard
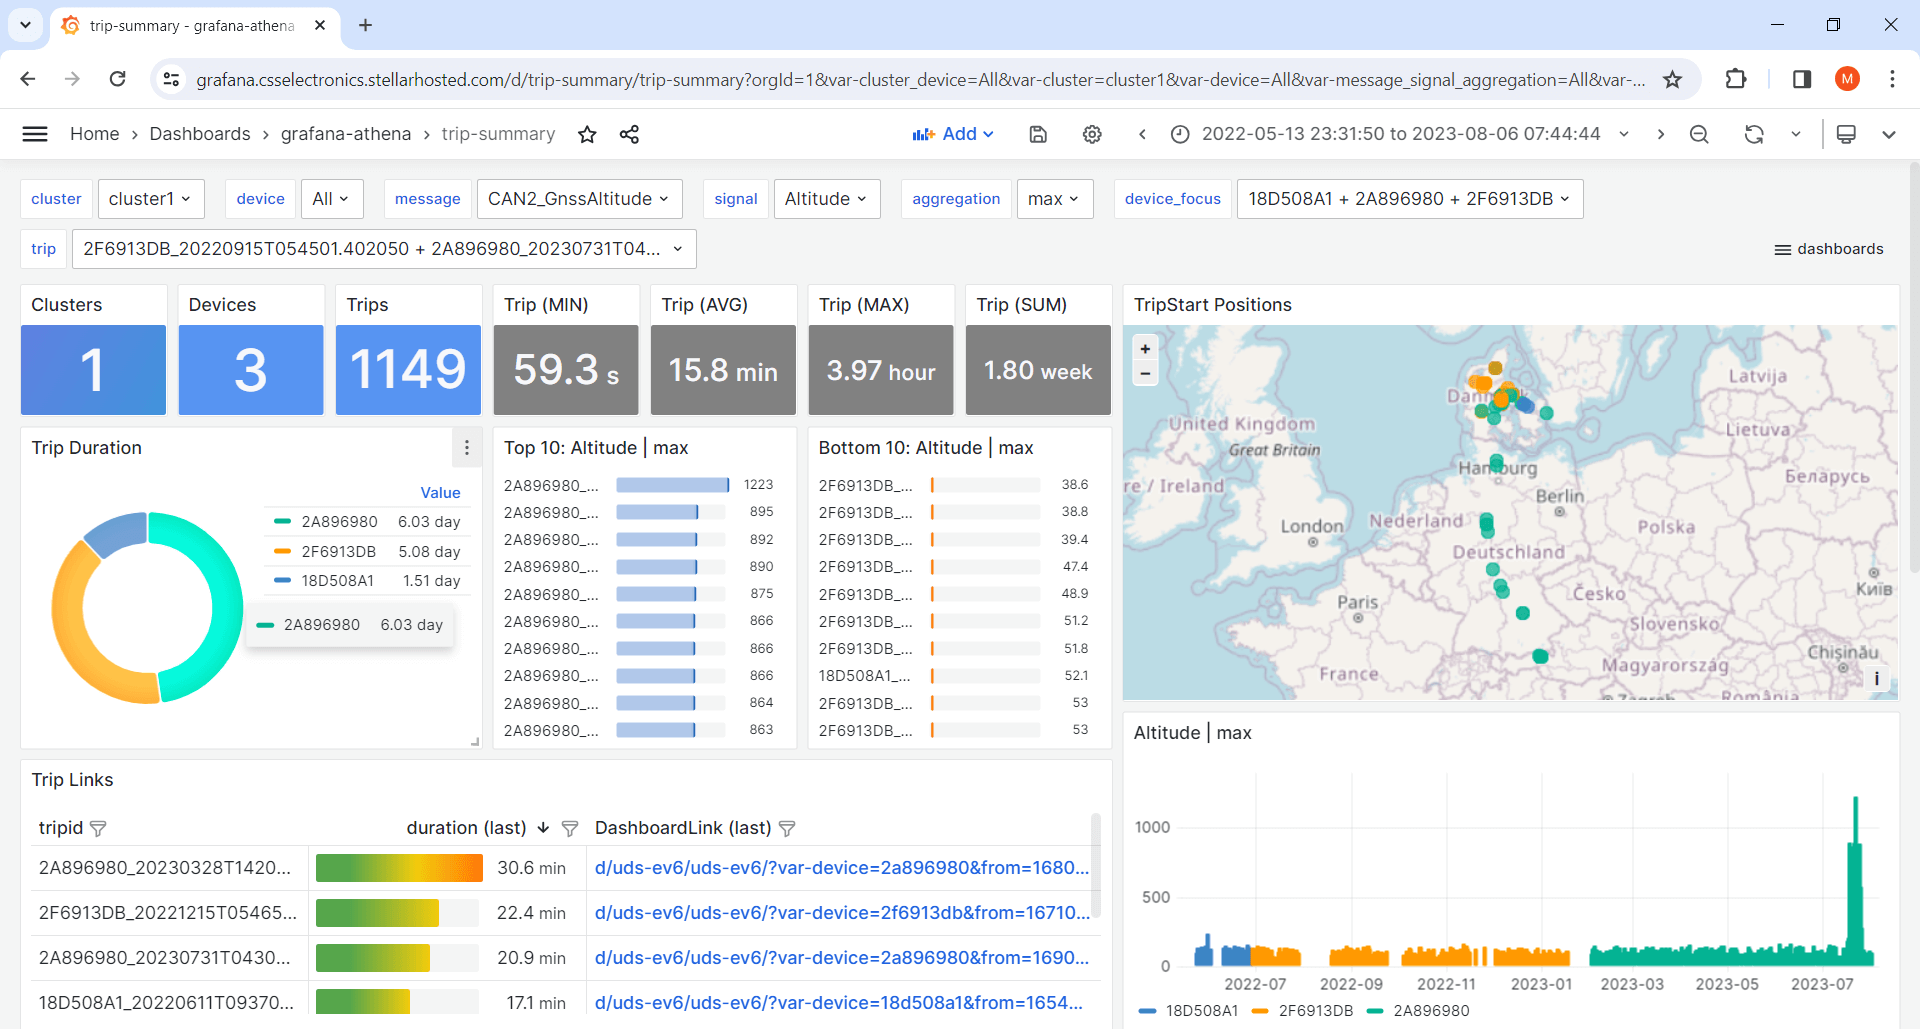
This template lets you visualize [aggregated trip summary tables](../../mdf4-decoders/parquet-data-lake-advanced/aggregation.md#ref-parquet-data-lake-advanced-trip-summary)[7](#fn-color-coding) - ideal for fleets.
[`trip-summary-dashboard template`](/_static/files/log-file-tools/grafana-athena/templates/athena-trip-summary-template.json)
### Event summary dashboard
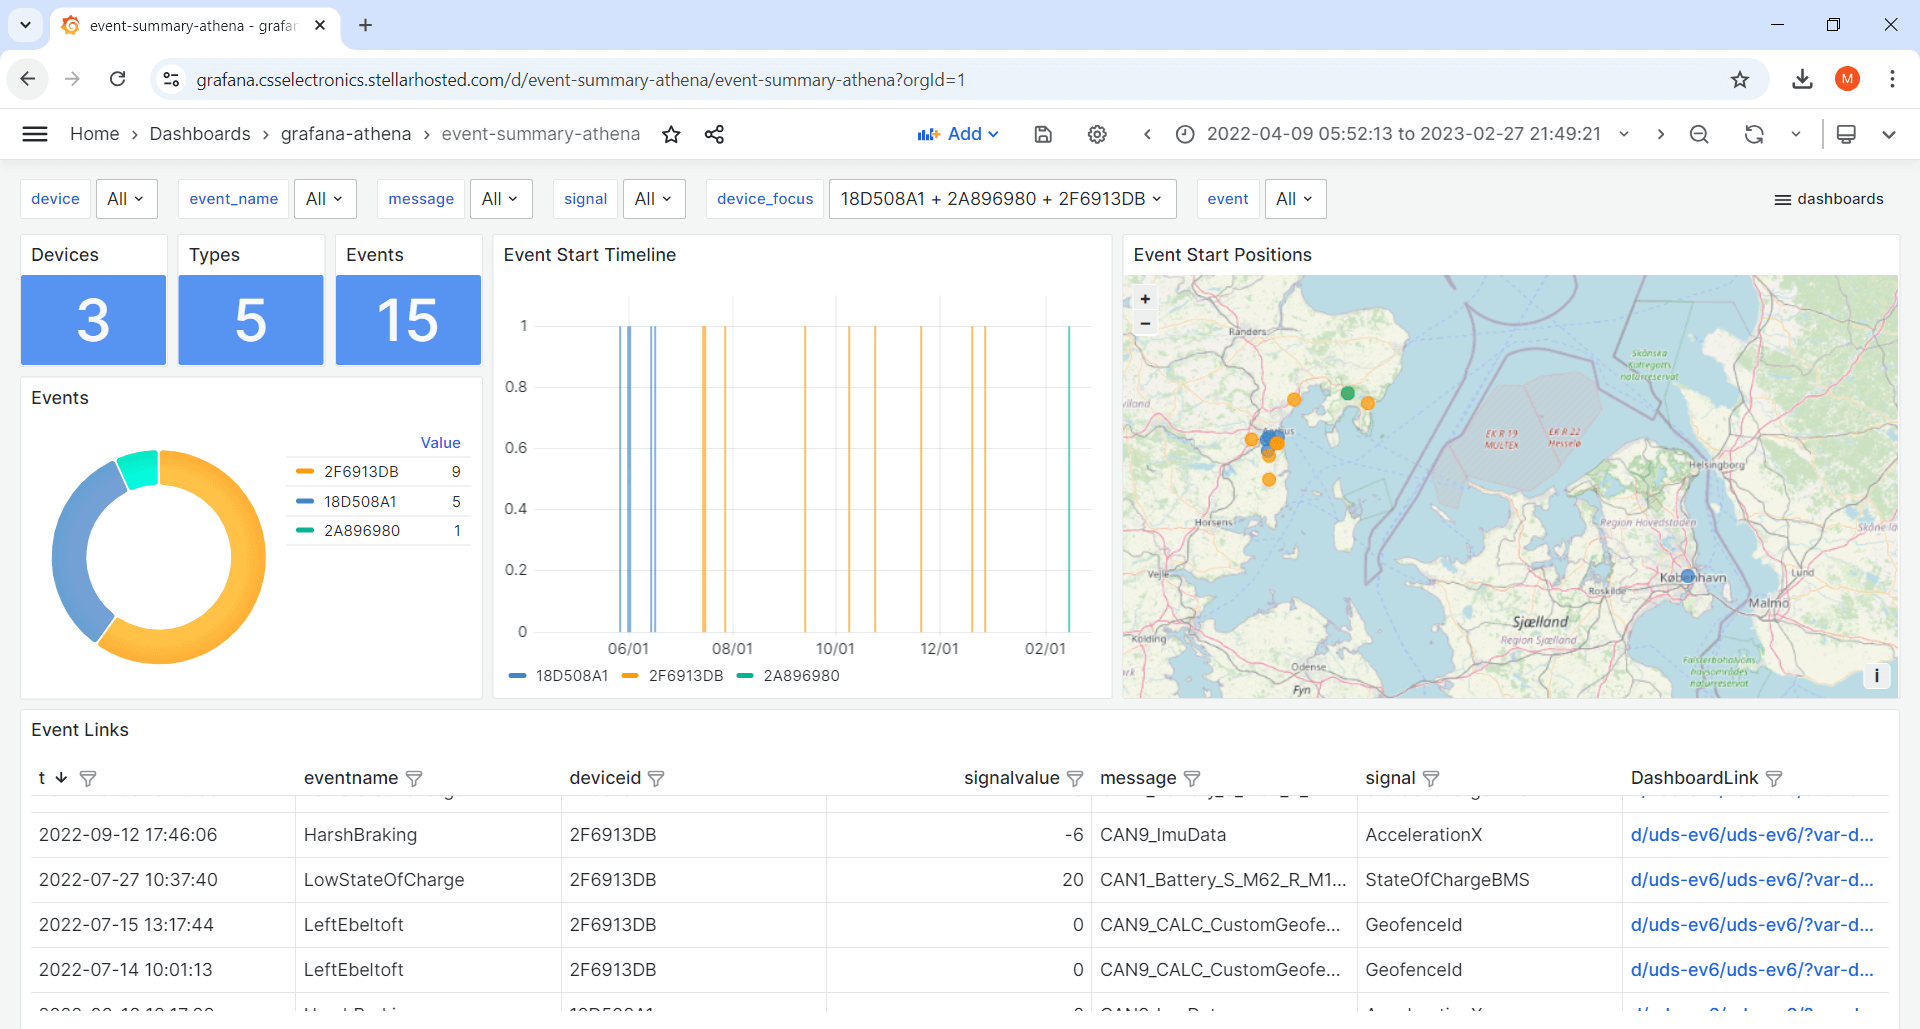
This template lets you visualize [event summary tables](../../mdf4-decoders/parquet-data-lake-advanced/alerts.md#ref-parquet-data-lake-advanced-alerts)[7](#fn-color-coding) - ideal for fleets.
[`event-summary-dashboard template`](/_static/files/log-file-tools/grafana-athena/templates/athena-event-summary-template.json)
---
## Variables
The dashboard templates all use [variables](https://grafana.com/docs/grafana/latest/dashboards/variables/). These allow end users of the dashboard to dynamically control certain values, e.g. the `device`, `message` and `signal`.
#### NOTE
By default, the `device` dropdown lists all your output bucket device IDs with a meta prefix (extracted from the `device.json` files in the input bucket)[3](#fn-device-meta)
---
## Create a new panel
The Athena data source uses standard SQL to query data.
To create a new panel, click ‘Add/Visualization’ (top middle) and paste a query as below:
```text
SELECT
$__timeGroup(t, $__interval) as time,
AVG(mysignal) as AVG_mysignal
FROM
tbl_${device:csv}_mymessage
WHERE
date_created BETWEEN $__rawTimeFrom('yyyy/MM/dd') AND $__rawTimeTo('yyyy/MM/dd')
AND
$__timeFilter(t)
GROUP BY
$__timeGroup(t, $__interval)
ORDER BY
time asc
```
Simply replace `mymessage` with your message name (e.g. `can2_gnssspeed`) and `mysignal` with a signal (e.g. `speed`) from that message[2](#fn-browse-names). You can also query multiple signals/aggregations:
```text
AVG(mysignal1) as AVG_mysignal1, MAX(mysignal2) as MAX_mysignal2
```
---
## Optimize performance
1. **Query result reuse**: We recommend to enable this in panels to ‘cache’ queries[4](#fn-query-results-reuse)
2. **Datasource caching**: Optionally enable caching in your data source[5](#fn-datasource-caching)
3. **Reuse signals**: Use existing panels as data sources to e.g. reuse signals in new panels[6](#fn-signal-reuse)
---
## Transformations
Grafana transformations allow you to create e.g. calculated signals, filters and more. In the dashboard templates, transformations are e.g. used to filter which signals are shown in certain panels - as well as scale speed (m/s) to speed (km/h).
#### NOTE
We recommend to review Grafana’s excellent [transformations docs](https://grafana.com/docs/grafana/latest/panels-visualizations/query-transform-data/transform-data/) for details
Transformations are done on the results of your SQL queries - not on the backend data. To create backend calculations, you should instead modify the SQL query (more below).
Importantly, transformations can be chained - leading to an almost limitless number of possibilities.
Below we list examples of useful Grafana transformations:
### Merge
A challenge when working with CAN data is the use of different time rasters per CAN message in the backend, which normally makes it hard to operate on signals across messages. However, the aforementioned Athena queries resample your backend data to a common time raster on-the-fly. As a consequence, you can add multiple SQL queries in the same panel and apply a ‘merge’ operation to operate on cross-message signals in a single table with a shared time raster.
### Add field from calculation
This allows you to create calculated signals via various math operations, across one or multiple signals (incl. across messages via merging).
### Filter data by values
This is great for excluding certain values from your panels (incl. e.g. null values or outliers).
### Transpose
This pivots your data frame, which is often useful in restructuring your data in a specific way.
---
## Advanced SQL queries
For many use cases, the default SQL queries in our dashboard templates will suffice for visualizing your data - in particular when combined with the powerful Grafana transformations.
However, some calculations need to be done on the ‘original’ data in the Parquet data lake at the backend. Luckily, this can often be done via a custom SQL query.
Below we list some tips on creating custom Athena SQL queries:
### Use our default queries as inspiration
The default queries do a lot of heavy-lifting that you should re-use in custom queries, in particular in regards to the dynamic behavior (Variables, timestamp functions) and filtering (as per the `WHERE` section). In addition, make sure to always return a result that is ‘aggregated’ (e.g. through `AVG`, `MAX`, `SUM`, …) to avoid returning e.g. millions of observations to Grafana.
### Leverage ChatGPT and similar tools
In our experience, tools like ChatGPT can help construct complex queries with great results. If you are not an SQL expert, this is a practical method to generate queries that you can immediately test out. Make sure to provide our default queries as a starting point for the development.
### Use sub queries for delta time operations
In CAN/LIN analysis you often need to analyse data with respect to time durations i.e. *delta time*. This is e.g. useful to understand how much time a vehicle spends charging, with active DTCs or at different RPM levels. To do this, you can use `WITH` sub queries and `DATE_DIFF` operations. For inspiration, see the ‘duty cycle’ panel in our [j1939-truck-athena](https://grafana.csselectronics.stellarhosted.com/d/j1939-truck/j1939-truck) dashboard playground.
### Perform cross-table joins
In SQL, you can query data across multiple tables (i.e. different CAN messages in our context) by using `JOIN` statements, allowing you to perfrom backend calculations of signals across messages. While powerful, such operations are drastically slower vs. returning resampled data from the two tables in parallel. We therefore recommend to always consider if your cross-table signal calculations could be done by using Grafana transformations on the resampled responses of multiple queries.
---
## Custom signals, trip summaries and alerts
In some cases, the combination of Grafana’s transformations and Athena’s SQL queries will still not suffice to enable the analysis you are looking to achieve.
For example, if you need to create complex SQL queries with many `JOIN` statements, you dashboard will become slow. Here you can instead create **custom signal tables** in your backend.
If your goal is to look at **trip summaries/benchmarking** across devices/messages we recommend to see our section on creating trip summary tables.
Further, you may want to set up **event notifications/alerts** and visualize the historical events.
These topics are covered in our [advanced topics](../../mdf4-decoders/parquet-data-lake-advanced.md#ref-parquet-data-lake-advanced) section.
---
## Grafana Assistant (AI)
When exploring data and building dashboards, it can be useful to leverage Grafana Assistant - Grafana’s built-in LLM tool. We explain how this works in our [Grafana Assistant + CAN bus](https://www.csselectronics.com/pages/grafana-assistant-can-bus-data-ai-llm-dashboards) intro article. In particular we recommend to leverage our ‘startup prompt’:
[`Grafana Assistant + Athena system prompt`](https://canlogger1000.csselectronics.com/files/guides/grafana-assistant-intro/startup-prompt-athena.md)
---
* **[1]** These templates use Grafana’s powerful Geomap panel (specifically the ‘Route’ layer). You can add multiple layers, incl. markers, heatmaps etc. as described in the [Geomap docs](https://grafana.com/docs/grafana/latest/panels-visualizations/visualizations/geomap/). The template panel executes two queries (position, speed) from separate tables, then merges the results to allow using the speed result as color coding for the route
* **[2]** If in doubt on message/signal names, you can browse them via the variable dropdowns
* **[3]** If you wish to update the meta prefix, simply update the relevant device Configuration File to trigger a change in the `device.json` once synced. After this, you can re-run the Glue script to update the mapping table queried by the `device` Variable dropdown. If you prefer to only display the device IDs, simply remove the `metaname AS text` section of the query (or hardcode the list entirely using the ‘Custom’ Variable type)
* **[4]** This is enabled by default in the dashboard templates
* **[5]** Data source caching implies that if a query has been run previously in Grafana it will be cached for a period - implying that no query is made against AWS Athena. This adds an extra layer of speed and cost reductions. However, it can cause confusion if you’re actively expanding your data lake with new devices/tables - so consider enabling this as you enter ‘production’
* **[6]** This is an important trick to avoid querying the same data twice. Simply select `-- Dashboard --` as data source in a panel, then use ‘Transform data/filter by name’ to control which of the already-queried signals to display in the new panel. This is particularly useful as you can query multiple signals for a given message in one panel - and then visualize them across multiple panels. You can see this used in the GPS/IMU templates for e.g. speed, satellites/fix and acceleration
* **[7]** The trip summary template works best if you align the color coding of devices across plots. We provide a small [`'device-color-generator' script`](/_static/files/log-file-tools/grafana-athena/templates/device-color-generator/device_color_generator.zip) that can be used in facilitating this. This script is provided without support
# index.html.md
# Set up Grafana-Athena
Grafana lets you build custom dashboards to visualize data. In this section we explain how you set up Grafana with Amazon Athena as the data source.
> ##### Table of Contents
>
> * [Prerequisites: Amazon Parquet data lake](#prerequisites-amazon-parquet-data-lake)
> * [Set up Grafana and add Athena data source](#set-up-grafana-and-add-athena-data-source)
> * [Deploy your first dashboard](#deploy-your-first-dashboard)
---
## Prerequisites: Amazon Parquet data lake
1. [Set up Amazon Parquet data lake](../../mdf4-decoders/parquet-data-lake.md#ref-parquet-data-lake) [~10 min]
#### NOTE
The above steps are required before proceeding
---
## Set up Grafana and add Athena data source
1. Make sure you have completed the prerequisites above
2. Set up a [Grafana Cloud](https://grafana.com/signup/starter/connect-account) starter account (100% free) and login
3. Go to the [Amazon Athena plugin](https://grafana.com/grafana/plugins/grafana-athena-datasource/?tab=installation) and click ‘Install plugin’
4. In Grafana go to ‘Connections/Data sources/Add new data source’ and select Athena
5. Ensure ‘Name’ is `Amazon Athena`, add the relevant [AWS stack ‘Outputs’](../../mdf4-decoders/parquet-data-lake/amazon.md#ref-parquet-data-lake-aws) and click ‘Save & test’
#### NOTE
The name of the data source must be `Amazon Athena` for our template dashboards to work
---
## Deploy your first dashboard
1. Download our [`athena-dynamic-dashboard template`](/_static/files/log-file-tools/grafana-athena/templates/athena-dynamic-dashboard-template.json)
2. Go to ‘Dashboards/New/Import’, upload the template and click ‘Load’
3. Verify that your data is loaded in the dashboard as expected[1](#fn-timeperiod)
You are now ready to [customize your dashboard](customize-dashboard.md#ref-customize-athena-dashboard).
---
* **[1]** You may need to change the time period via the upper-right menu to navigate to your data
# index.html.md
# Customize your dashboard
With your first Grafana-BigQuery dashboard in place, you can now start customizing.
Grafana has a [tutorial](https://grafana.com/docs/grafana/latest/panels-visualizations/) on panels, so we mainly focus on some of the basics. You can also find inspiration via our [dashboard playgrounds](https://grafana.csselectronics.stellarhosted.com/d/obd2-gps-car/obd2-gps-car).
> ##### Table of Contents
>
> * [Templates - getting started](#templates-getting-started)
> * [Templates - advanced](#templates-advanced)
> * [Variables](#variables)
> * [Create a new panel](#create-a-new-panel)
> * [Transformations](#transformations)
> * [Advanced SQL queries](#advanced-sql-queries)
> * [Custom signals, trip summaries and alerts](#custom-signals-trip-summaries-and-alerts)
> * [Grafana Assistant (AI)](#grafana-assistant-ai)
---
## Templates - getting started
We recommend that you load one of the below templates to get started:
### Simple dynamic dashboard
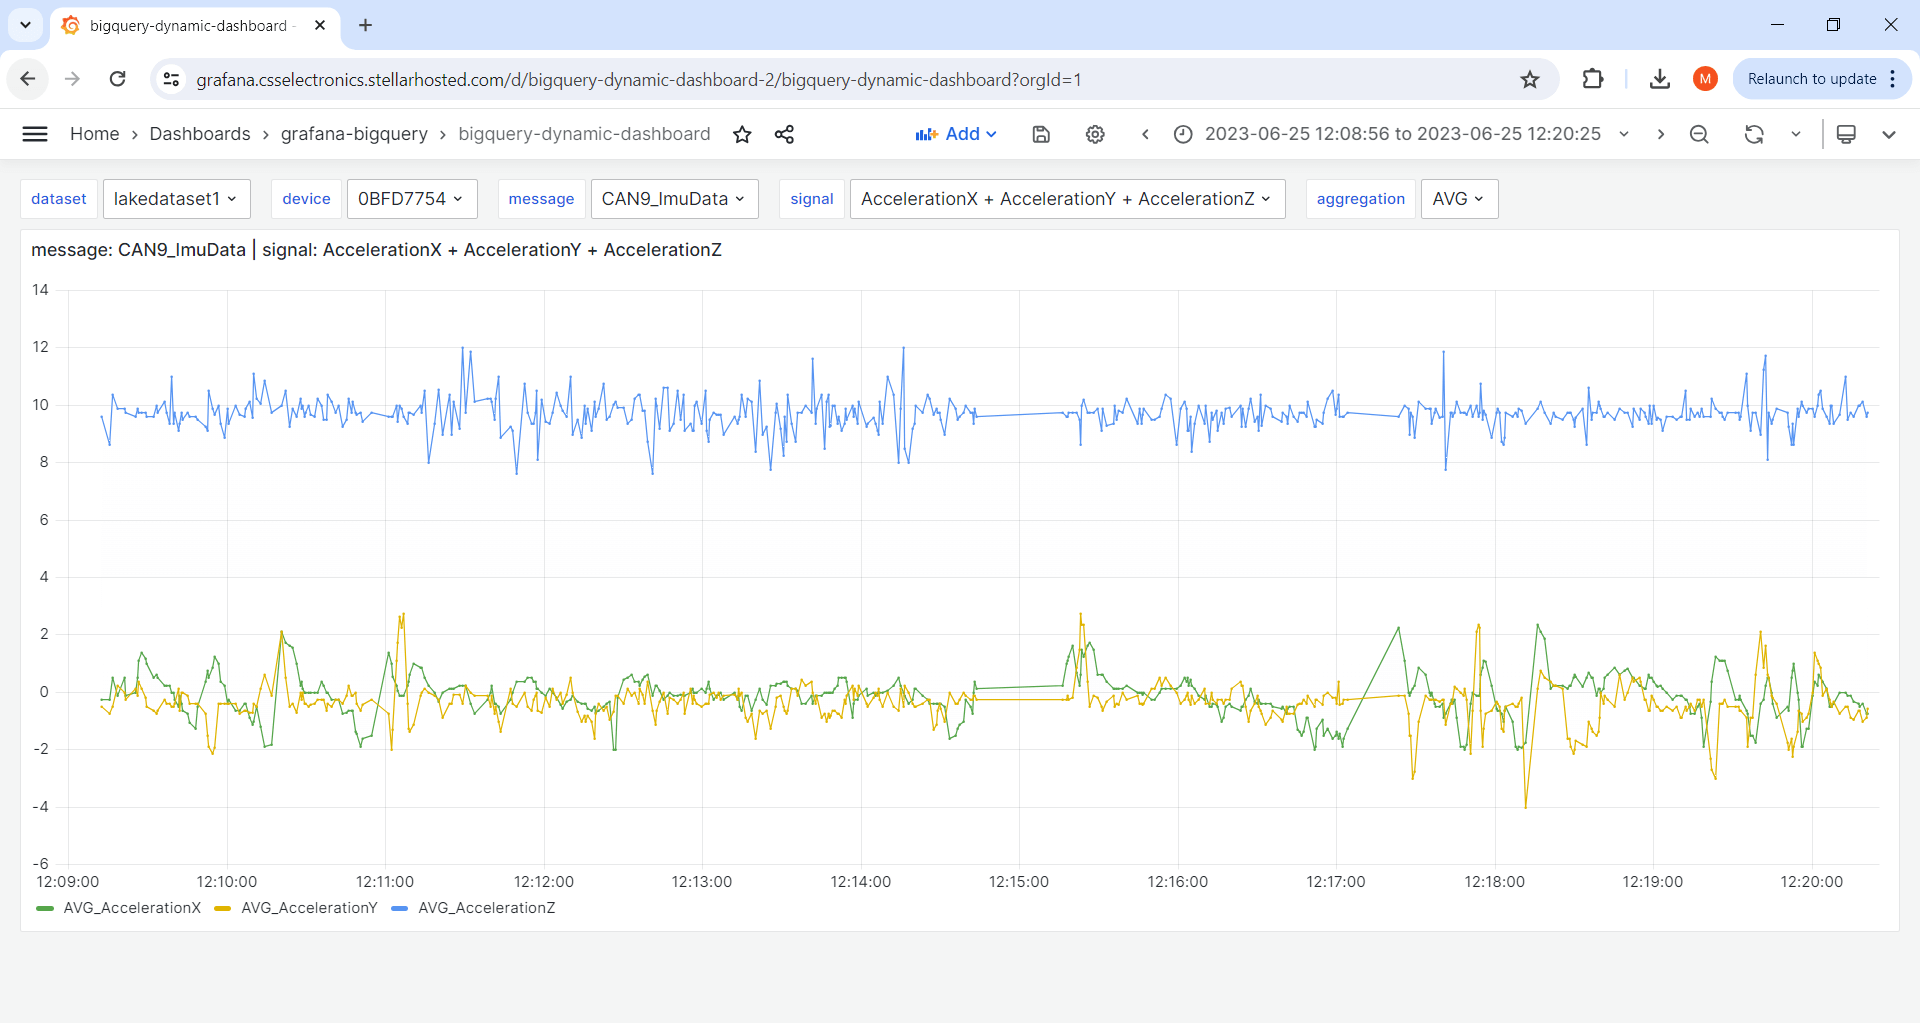
This template works for any CAN/LIN dataset and serves as a good starting point.
[`bigquery-dynamic-dashboard template`](/_static/files/log-file-tools/grafana-bigquery/templates/bigquery-dynamic-dashboard-template.json)
### GPS/IMU dashboard

This template is ideal if you have a CANedge incl. GPS/IMU[1](#fn-geomap).
[`bigquery-internal-gps-dashboard template`](/_static/files/log-file-tools/grafana-bigquery/templates/bigquery-internal-gps-dashboard-template.json)
---
## Templates - advanced
### Trip summary dashboard

This template lets you visualize [aggregated trip summary tables](../../mdf4-decoders/parquet-data-lake-advanced/aggregation.md#ref-parquet-data-lake-advanced-trip-summary)[5](#fn-color-coding) - ideal for fleets.
[`trip-summary-dashboard template`](/_static/files/log-file-tools/grafana-bigquery/templates/bigquery-trip-summary-template.json)
### Event summary dashboard

This template lets you visualize [event summary tables](../../mdf4-decoders/parquet-data-lake-advanced/alerts.md#ref-parquet-data-lake-advanced-alerts)[5](#fn-color-coding) - ideal for fleets.
[`event-summary-dashboard template`](/_static/files/log-file-tools/grafana-bigquery/templates/bigquery-event-summary-template.json)
---
## Variables
The dashboard template uses [variables](https://grafana.com/docs/grafana/latest/dashboards/variables/). These allow end users of the dashboard to dynamically control certain values, e.g. the `device`, `message` and `signal`.
#### NOTE
By default, the `device` dropdown lists all your output bucket device IDs with a meta prefix (extracted from the `device.json` files in the input bucket)[2](#fn-device-meta)
---
## Create a new panel
The BigQuery data source uses standard SQL to query data[3](#fn-query-comments).
To create a new panel, click ‘Add/Visualization’ (top middle) and paste a query as below:
```text
SELECT
TIMESTAMP_MILLIS(DIV(UNIX_MILLIS(t), $__interval_ms) * $__interval_ms) as time,
AVG(MySignal) as AVG_mysignal
FROM
${dataset}.tbl_${device:csv}_MyMessage
WHERE
$__timeFilter(t)
GROUP BY
time
ORDER BY
time asc
```
Simply replace `MyMessage` with your message name (e.g. `CAN2_gnssspeed`) and `mysignal` with a signal (e.g. `Speed`) from that message[4](#fn-browse-names). You can also query multiple signals/aggregations:
```text
AVG(MySignal1) as AVG_mysignal1, MAX(MySignal2) as MAX_mysignal2
```
---
## Transformations
Grafana transformations allow you to create e.g. calculated signals, filters and more. In the dashboard templates, transformations are e.g. used to filter which signals are shown in certain panels - as well as scale speed (m/s) to speed (km/h).
#### NOTE
We recommend to review Grafana’s excellent [transformations docs](https://grafana.com/docs/grafana/latest/panels-visualizations/query-transform-data/transform-data/) for details
Transformations are done on the results of your SQL queries - not on the backend data. To create backend calculations, you should instead modify the SQL query (more below).
Importantly, transformations can be chained - leading to an almost limitless number of possibilities.
Below we list examples of useful Grafana transformations:
### Merge
A challenge when working with CAN data is the use of different time rasters per CAN message in the backend, which normally makes it hard to operate on signals across messages. However, the aforementioned queries resample your backend data to a common time raster on-the-fly. As a consequence, you can add multiple SQL queries in the same panel and apply a ‘merge’ operation to operate on cross-message signals in a single table with a shared time raster.
### Add field from calculation
This allows you to create calculated signals via various math operations, across one or multiple signals (incl. across messages via merging).
### Filter data by values
This is great for excluding certain values from your panels (incl. e.g. null values or outliers).
### Transpose
This pivots your data frame, which is often useful in restructuring your data in a specific way.
---
## Advanced SQL queries
For many use cases, the default SQL queries in our dashboard templates will suffice for visualizing your data - in particular when combined with the powerful Grafana transformations.
However, some calculations need to be done on the ‘original’ data in the Parquet data lake at the backend. Luckily, this can often be done via a custom SQL query.
Below we list some tips on creating custom SQL queries:
### Use our default queries as inspiration
The default queries do a lot of heavy-lifting that you should re-use in custom queries, in particular in regards to the dynamic behavior (Variables, timestamp functions) and filtering (as per the `WHERE` section). In addition, make sure to always return a result that is ‘aggregated’ (e.g. through `AVG`, `MAX`, `SUM`, …) to avoid returning e.g. millions of observations to Grafana.
### Leverage ChatGPT and similar tools
In our experience, tools like ChatGPT can help construct complex queries with great results. If you are not an SQL expert, this is a practical method to generate queries that you can immediately test out. Make sure to provide our default queries as a starting point for the development.
### Use sub queries for delta time operations
In CAN/LIN analysis you often need to analyse data with respect to time durations i.e. *delta time*. This is e.g. useful to understand how much time a vehicle spends charging, with active DTCs or at different RPM levels. To do this, you can use `WITH` sub queries and date diff operations. For inspiration, see the ‘duty cycle’ panel in our [j1939-truck-athena](https://grafana.csselectronics.stellarhosted.com/d/j1939-truck/j1939-truck) dashboard playground.
### Perform cross-table joins
In SQL, you can query data across multiple tables (i.e. different CAN messages in our context) by using `JOIN` statements, allowing you to perfrom backend calculations of signals across messages. While powerful, such operations are drastically slower vs. returning resampled data from the two tables in parallel. We therefore recommend to always consider if your cross-table signal calculations could be done by using Grafana transformations on the resampled responses of multiple queries.
---
## Custom signals, trip summaries and alerts
In some cases, the combination of Grafana’s transformations and BigQuery’s SQL queries will still not suffice to enable the analysis you are looking to achieve.
For example, if you need to create complex SQL queries with many `JOIN` statements, you dashboard will become slow. Here you can instead create **custom signal tables** in your backend.
If your goal is to look at **trip summaries/benchmarking** across devices/messages we recommend to see our section on creating trip summary tables.
Further, you may want to set up **event notifications/alerts** and visualize the historical events.
These topics are covered in our [advanced topics](../../mdf4-decoders/parquet-data-lake-advanced.md#ref-parquet-data-lake-advanced) section.
---
## Grafana Assistant (AI)
When exploring data and building dashboards, it can be useful to leverage Grafana Assistant - Grafana’s built-in LLM tool. We explain how this works in our [Grafana Assistant + CAN bus](https://www.csselectronics.com/pages/grafana-assistant-can-bus-data-ai-llm-dashboards) intro article. In particular we recommend to leverage our ‘startup prompt’:
[`Grafana Assistant + BigQuery system prompt`](https://canlogger1000.csselectronics.com/files/guides/grafana-assistant-intro/startup-prompt-bigquery.md)
---
* **[1]** These templates use Grafana’s powerful Geomap panel (specifically the ‘Route’ layer). You can add multiple layers, incl. markers, heatmaps etc. as described in the [Geomap docs](https://grafana.com/docs/grafana/latest/panels-visualizations/visualizations/geomap/). The template panel executes two queries (position, speed) from separate tables, then merges the results to allow using the speed result as color coding for the route
* **[2]** If you wish to update the meta prefix, simply update the relevant device Configuration File to trigger a change in the `device.json` once synced. After this, you can re-run the mapping function to update the mapping table queried by the `device` Variable dropdown. If you prefer to only display the device IDs, simply remove the `metaname AS text` section of the query (or hardcode the list entirely using the ‘Custom’ Variable type)
* Note that the BigQuery query does not leverage partition pruning, in contrast to our Grafana-Athena and Grafana-Synapse integrations. This is because the `YYYY/MM/DD` partition structure produced by the MF4 decoder is not supported by BigQuery. However, BigQuery does use the time filter to some extent for partition pruning, ensuring that the query speed remains high and that the ‘data scanned’ does not e.g. include folders that lie outside the period of interest
* **[4]** If in doubt on message/signal names, you can browse them via the variable dropdowns. Note that message names are case sensitive in BigQuery
* **[5]** The trip summary template works best if you align the color coding of devices across plots. We provide a small [`'device-color-generator' script`](/_static/files/log-file-tools/grafana-athena/templates/device-color-generator/device_color_generator.zip) that can be used in facilitating this. This script is provided without support
# index.html.md
# Set up Grafana-BigQuery
Grafana lets you build custom dashboards to visualize data. In this section we explain how you set up Grafana with Google BigQuery as the data source.
> ##### Table of Contents
>
> * [Prerequisites: Google Parquet data lake](#prerequisites-google-parquet-data-lake)
> * [Set up Grafana and add BigQuery data source](#set-up-grafana-and-add-bigquery-data-source)
> * [Deploy your first dashboard](#deploy-your-first-dashboard)
---
## Prerequisites: Google Parquet data lake
1. [Set up Google Parquet data lake](../../mdf4-decoders/parquet-data-lake/google.md#ref-parquet-data-lake-google) [~10 min]
#### NOTE
The above steps are required before proceeding
---
## Set up Grafana and add BigQuery data source
1. Make sure you have completed the prerequisites above
2. Set up a [Grafana Cloud](https://grafana.com/signup/starter/connect-account) starter account (100% free) and login
3. Go to the [Google BigQuery plugin](https://grafana.com/grafana/plugins/grafana-bigquery-datasource/?tab=installation) and click ‘Install plugin’
4. In Grafana go to ‘Connections/Data sources/Add new data source’ and select BigQuery
5. Ensure ‘Name’ is `Google BigQuery`
6. Under ‘JWT token’ load your `-bigquery-user-account.json`[1](#fn-json-user-account), then click ‘Save & test’
7. Enable the ‘Cloud Resource Manager API’ via the URL when prompted, then click ‘Save & test’
#### NOTE
The name of the data source must be `Google BigQuery` for our template dashboards to work
---
## Deploy your first dashboard

1. Download our [`bigquery-dynamic-dashboard template`](/_static/files/log-file-tools/grafana-bigquery/templates/bigquery-dynamic-dashboard-template.json)
2. Go to ‘Dashboards/New/Import’, upload the updated template and click ‘Load’
3. Go to ‘Settings/Variables/dataset’ and set it to match the one in your BigQuery project
4. Verify that your data is loaded in the dashboard as expected[2](#fn-timeperiod)
#### NOTE
The default template `dataset` value is `lakedataset1` - if your name differs, you must update it
You are now ready to [customize your dashboard](customize-dashboard.md#ref-customize-bigquery-dashboard).
---
* **[1]** This file was stored by the Terraform deployment in your input bucket root
* **[2]** You may need to change the time period via the upper-right menu to navigate to your data
# index.html.md
# Customize your dashboard
With your first Grafana-Synapse dashboard in place, you can now start customizing.
Grafana has a [tutorial](https://grafana.com/docs/grafana/latest/panels-visualizations/) on panels, so we mainly focus on some of the basics. You can also find inspiration via our [dashboard playgrounds](https://grafana.csselectronics.stellarhosted.com/d/obd2-gps-car/obd2-gps-car).
> ##### Table of Contents
>
> * [Templates - getting started](#templates-getting-started)
> * [Templates - advanced](#templates-advanced)
> * [Variables](#variables)
> * [Create a new panel](#create-a-new-panel)
> * [Transformations](#transformations)
> * [Advanced SQL queries](#advanced-sql-queries)
---
## Templates - getting started
We recommend that you load one of the below templates to get started:
### Simple dynamic dashboard
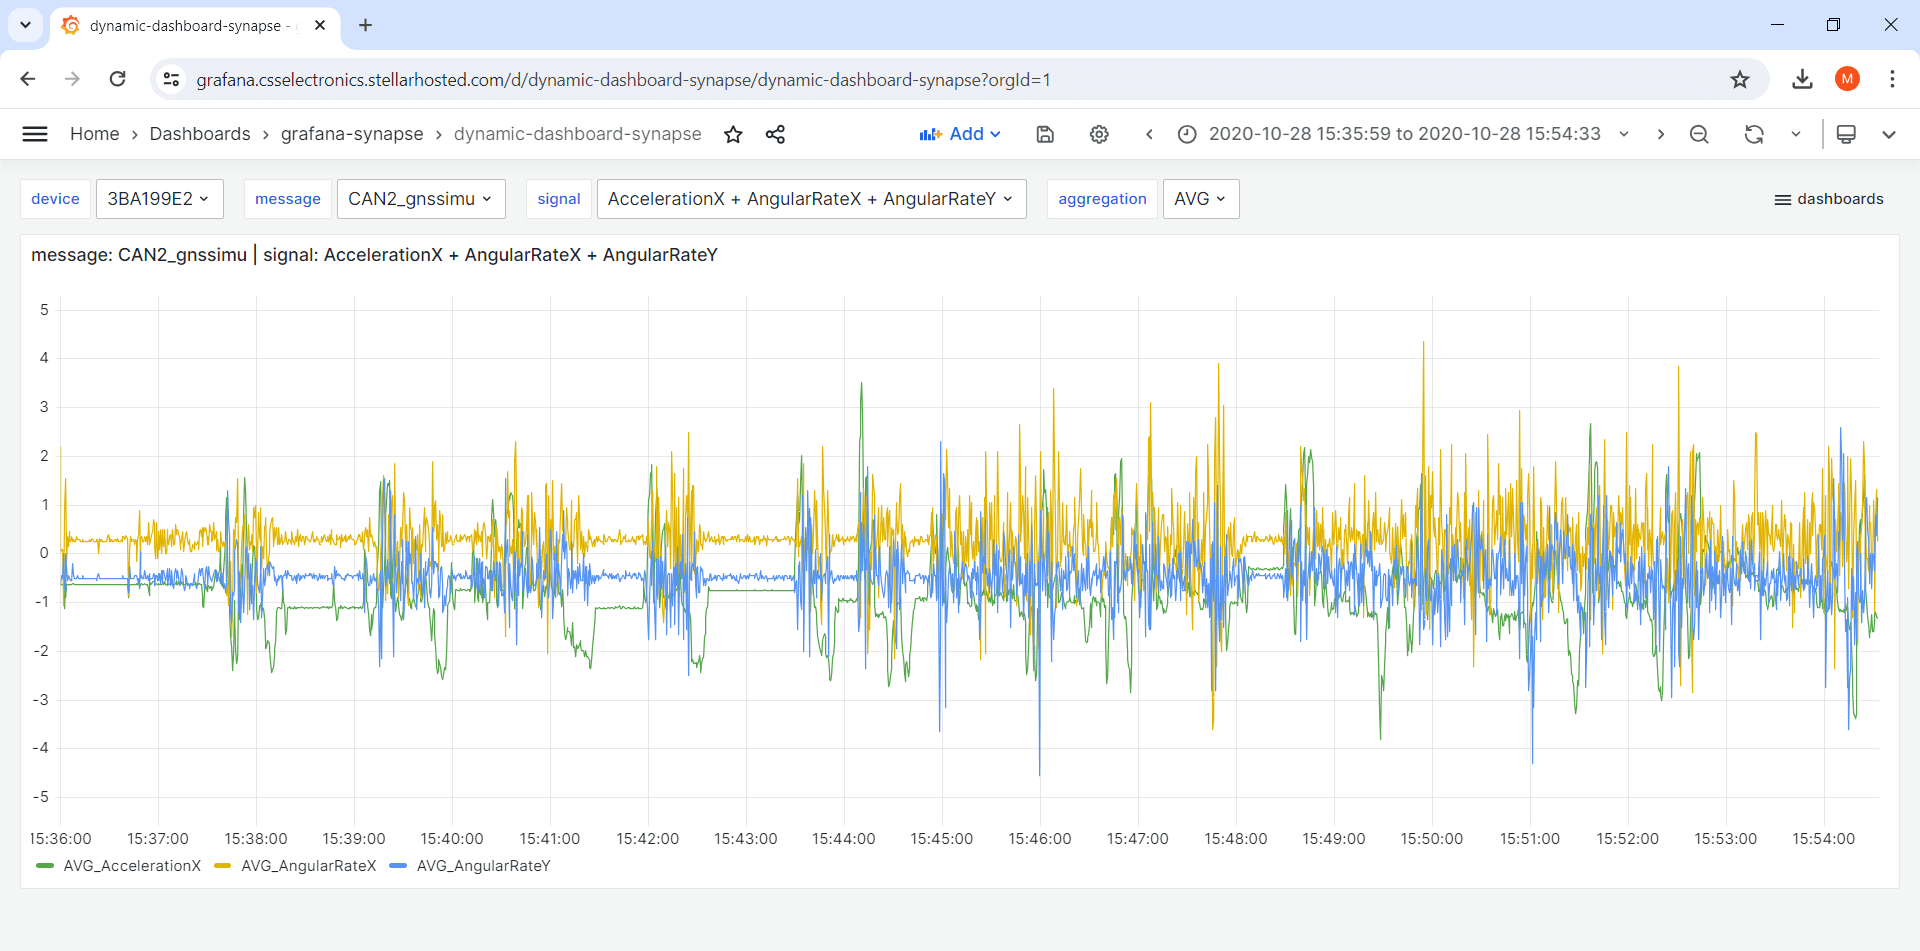
This template works for any CAN/LIN dataset and serves as a good starting point.
[`synapse-dynamic-dashboard template`](/_static/files/log-file-tools/grafana-synapse/templates/synapse-dynamic-dashboard-template.json)
### GPS/IMU dashboard

This template is ideal if you have a CANedge incl. GPS/IMU[1](#fn-geomap).
[`synapse-internal-gps-dashboard template`](/_static/files/log-file-tools/grafana-synapse/templates/synapse-internal-gps-dashboard-template.json)
## Templates - advanced
### Trip summary dashboard

This template lets you visualize [aggregated trip summary tables](../../mdf4-decoders/parquet-data-lake-advanced/aggregation.md#ref-parquet-data-lake-advanced-trip-summary)[5](#fn-color-coding) - ideal for fleets.
[`trip-summary-dashboard template`](/_static/files/log-file-tools/grafana-synapse/templates/synapse-trip-summary-template.json)
### Event summary dashboard

This template lets you visualize [event summary tables](../../mdf4-decoders/parquet-data-lake-advanced/alerts.md#ref-parquet-data-lake-advanced-alerts)[5](#fn-color-coding) - ideal for fleets.
[`event-summary-dashboard template`](/_static/files/log-file-tools/grafana-synapse/templates/synapse-event-summary-template.json)
---
## Variables
The dashboard template uses [variables](https://grafana.com/docs/grafana/latest/dashboards/variables/). These allow end users of the dashboard to dynamically control certain values, e.g. the `device`, `message` and `signal`.
#### NOTE
By default, the `device` dropdown lists all your output bucket device IDs with a meta prefix (extracted from the `device.json` files in the input bucket)[2](#fn-device-meta)
---
## Create a new panel
The Synapse data source uses standard SQL (T-SQL) to query data[3](#fn-query-details).
To create a new panel, click ‘Add/Visualization’ (top middle) and paste a query as below:
```text
SELECT
DATEADD(MILLISECOND, (DATEPART(MILLISECOND, t) / $__interval_ms) * $__interval_ms, DATEADD(SECOND, DATEDIFF(SECOND, '2020', t), '2020')) AS time,
AVG(mysignal) as AVG_mysignal
FROM
OPENROWSET(
BULK '${device:csv}/MyMessage/*/*/*/*',
DATA_SOURCE = 'ParquetDataLake',
FORMAT = 'PARQUET'
) AS r
WHERE
CONCAT(r.filepath(1), '-', r.filepath(2), '-', r.filepath(3)) BETWEEN CONVERT(date, $__timeFrom()) AND CONVERT(date, $__timeTo())
AND $__timeFilter(t)
GROUP BY
DATEDIFF(SECOND, '2020', t), DATEPART(MILLISECOND, t) / $__interval_ms
ORDER BY
time
OFFSET 0 ROWS;
```
Simply replace `MyMessage` with your message name (e.g. `CAN2_gnssspeed`) and `mysignal` with a signal (e.g. `Speed`) from that message[4](#fn-browse-names). You can also query multiple signals/aggregations:
```text
AVG(MySignal1) as AVG_mysignal1, MAX(MySignal2) as MAX_mysignal2
```
---
## Transformations
Grafana transformations allow you to create e.g. calculated signals, filters and more. In the dashboard templates, transformations are e.g. used to filter which signals are shown in certain panels - as well as scale speed (m/s) to speed (km/h).
#### NOTE
We recommend to review Grafana’s excellent [transformations docs](https://grafana.com/docs/grafana/latest/panels-visualizations/query-transform-data/transform-data/) for details
Transformations are done on the results of your SQL queries - not on the backend data. To create backend calculations, you should instead modify the SQL query (more below).
Importantly, transformations can be chained - leading to an almost limitless number of possibilities.
Below we list examples of useful Grafana transformations:
### Merge
A challenge when working with CAN data is the use of different time rasters per CAN message in the backend, which normally makes it hard to operate on signals across messages. However, the aforementioned queries resample your backend data to a common time raster on-the-fly. As a consequence, you can add multiple SQL queries in the same panel and apply a ‘merge’ operation to operate on cross-message signals in a single table with a shared time raster.
### Add field from calculation
This allows you to create calculated signals via various math operations, across one or multiple signals (incl. across messages via merging).
### Filter data by values
This is great for excluding certain values from your panels (incl. e.g. null values or outliers).
### Transpose
This pivots your data frame, which is often useful in restructuring your data in a specific way.
---
## Advanced SQL queries
For many use cases, the default SQL queries in our dashboard templates will suffice for visualizing your data - in particular when combined with the powerful Grafana transformations.
However, some calculations need to be done on the ‘original’ data in the Parquet data lake at the backend. Luckily, this can often be done via a custom SQL query.
Below we list some tips on creating custom SQL queries:
### Use our default queries as inspiration
The default queries do a lot of heavy-lifting that you should re-use in custom queries, in particular in regards to the dynamic behavior (Variables, timestamp functions) and filtering (as per the `WHERE` section). In addition, make sure to always return a result that is ‘aggregated’ (e.g. through `AVG`, `MAX`, `SUM`, …) to avoid returning e.g. millions of observations to Grafana.
### Leverage ChatGPT and similar tools
In our experience, tools like ChatGPT can help construct complex queries with great results. If you are not an SQL expert, this is a practical method to generate queries that you can immediately test out. Make sure to provide our default queries as a starting point for the development.
### Use sub queries for delta time operations
In CAN/LIN analysis you often need to analyse data with respect to time durations i.e. *delta time*. This is e.g. useful to understand how much time a vehicle spends charging, with active DTCs or at different RPM levels. To do this, you can use `WITH` sub queries and date diff operations. For inspiration, see the ‘duty cycle’ panel in our [j1939-truck-athena](https://grafana.csselectronics.stellarhosted.com/d/j1939-truck/j1939-truck) dashboard playground.
### Perform cross-table joins
In SQL, you can query data across multiple tables (i.e. different CAN messages in our context) by using `JOIN` statements, allowing you to perfrom backend calculations of signals across messages. While powerful, such operations are drastically slower vs. returning resampled data from the two tables in parallel. We therefore recommend to always consider if your cross-table signal calculations could be done by using Grafana transformations on the resampled responses of multiple queries.
---
* **[1]** These templates use Grafana’s powerful Geomap panel (specifically the ‘Route’ layer). You can add multiple layers, incl. markers, heatmaps etc. as described in the [Geomap docs](https://grafana.com/docs/grafana/latest/panels-visualizations/visualizations/geomap/). The template panel executes two queries (position, speed) from separate tables, then merges the results to allow using the speed result as color coding for the route
* **[2]** If you wish to update the meta prefix, simply update the relevant device Configuration File to trigger a change in the `device.json` once synced. After this, you can re-run the mapping job to update the mapping table queried by the `device` Variable dropdown. If you prefer to only display the device IDs, simply remove the `metaname AS text` section of the query (or hardcode the list entirely using the ‘Custom’ Variable type)
* **[3]** Note that the query uses `OPENROWSET` to fetch data, rather than referencing the tables that were mapped during the Synapse deployment. This is required in order to leverage partition pruning as done in the `WHERE` section via the `filepath` comparison. You could remove this pruning and refer to table names directly, but your queries would become drastically slower and scan more data (hence become more expensive). However, we do use the table mapping in the dynamic dropdown functionality of the Grafana dashboard template
* **[4]** If in doubt on message/signal names, you can browse them via the variable dropdowns. Note that message names are case sensitive in Synapse
* **[5]** The trip summary template works best if you align the color coding of devices across plots. We provide a small [`'device-color-generator' script`](/_static/files/log-file-tools/grafana-athena/templates/device-color-generator/device_color_generator.zip) that can be used in facilitating this. This script is provided without support
# index.html.md
# Set up Grafana-Synapse
Grafana lets you build custom dashboards to visualize data. In this section we explain how you set up Grafana with Azure Synapse as the data source (via Microsoft SQL Server).
> ##### Table of Contents
>
> * [Prerequisites: Azure Parquet data lake](#prerequisites-azure-parquet-data-lake)
> * [Set up Grafana and add Synapse data source](#set-up-grafana-and-add-synapse-data-source)
> * [Deploy your first dashboard](#deploy-your-first-dashboard)
---
## Prerequisites: Azure Parquet data lake
1. [Set up Azure Parquet data lake](../../mdf4-decoders/parquet-data-lake/azure.md#ref-parquet-data-lake-azure) [~10 min]
#### NOTE
The above steps are required before proceeding
---
## Set up Grafana and add Synapse data source
1. Make sure you have completed the prerequisites above
2. Set up a [Grafana Cloud](https://grafana.com/signup/starter/connect-account) starter account (100% free) and login
3. In Grafana go to ‘Connections/Data sources/Add new data source’
4. Select Microsoft SQL Server as the data source[1](#fn-data-source)
5. Ensure ‘Name’ is `Microsoft SQL Server`
6. In ‘Host’ use your Synapse ‘Serverless SQL endpoint’
7. As ‘Database’ use your Synapse database name (e.g. `database1`)[2](#fn-synapse-database)
8. In ‘Authentication’ use `SQL Server Authentication`
9. Authenticate with user `sqladminuser` and your SQL admin password[3](#fn-synapse-sql-admin-password)
10. Set the ‘Min time interval’ to `1ms` and click ‘Save & test’
#### NOTE
The data source name must be `Microsoft SQL Server` for our template dashboards to work
---
## Deploy your first dashboard

1. Download our [`dynamic-dashboard-synapse template`](/_static/files/log-file-tools/grafana-synapse/templates/synapse-dynamic-dashboard-template.json)
2. Go to ‘Dashboards/New/Import’, upload the updated template and click ‘Load’
3. Verify that your data is loaded in the dashboard as expected[4](#fn-timeperiod)
You are now ready to [customize your dashboard](customize-dashboard.md#ref-customize-synapse-dashboard).
---
* **[1]** There is no Azure Synapse data source in Grafana, hence we use Microsoft SQL Server as the data source instead
* **[2]** This was shown as part of the Synapse Terraform deployment output. If you do not have it, open your `synapse-map-tables-` Container App Job via the [console](https://portal.azure.com/#browse/Microsoft.App%2Fjobs) and go to Settings/Containers and click ‘synapse-map-tables’. Under ‘Environment variables/SYNAPSE_DATABASE’ you can find the database name
* **[3]** This was shown as part of the Synapse Terraform deployment output. If you do not have it, open your `synapse-map-tables-` Container App Job via the [console](https://portal.azure.com/#browse/Microsoft.App%2Fjobs) and go to Settings/Secrets/synapse-password to find it
* **[4]** You may need to change the time period via the upper-right menu to navigate to your data
# index.html.md
# Set up PowerBI-Synapse
Power BI lets you build custom dashboards/reports to visualize data. In this section we explain how you set up Power BI with Azure Synapse as the data source.
> ##### Table of Contents
>
> * [Prerequisites: Azure Parquet data lake + Synapse](#prerequisites-azure-parquet-data-lake-synapse)
> * [Example 1: Create a basic Power BI Desktop chart](#example-1-create-a-basic-power-bi-desktop-chart)
> * [Example 2: Create a dynamic Power BI dashboard](#example-2-create-a-dynamic-power-bi-dashboard)
---
## Prerequisites: Azure Parquet data lake + Synapse
1. [Set up Azure Parquet data lake](../../mdf4-decoders/parquet-data-lake/azure.md#ref-parquet-data-lake-azure) [~10 min]
#### NOTE
The above steps are required before proceeding
---
## Example 1: Create a basic Power BI Desktop chart
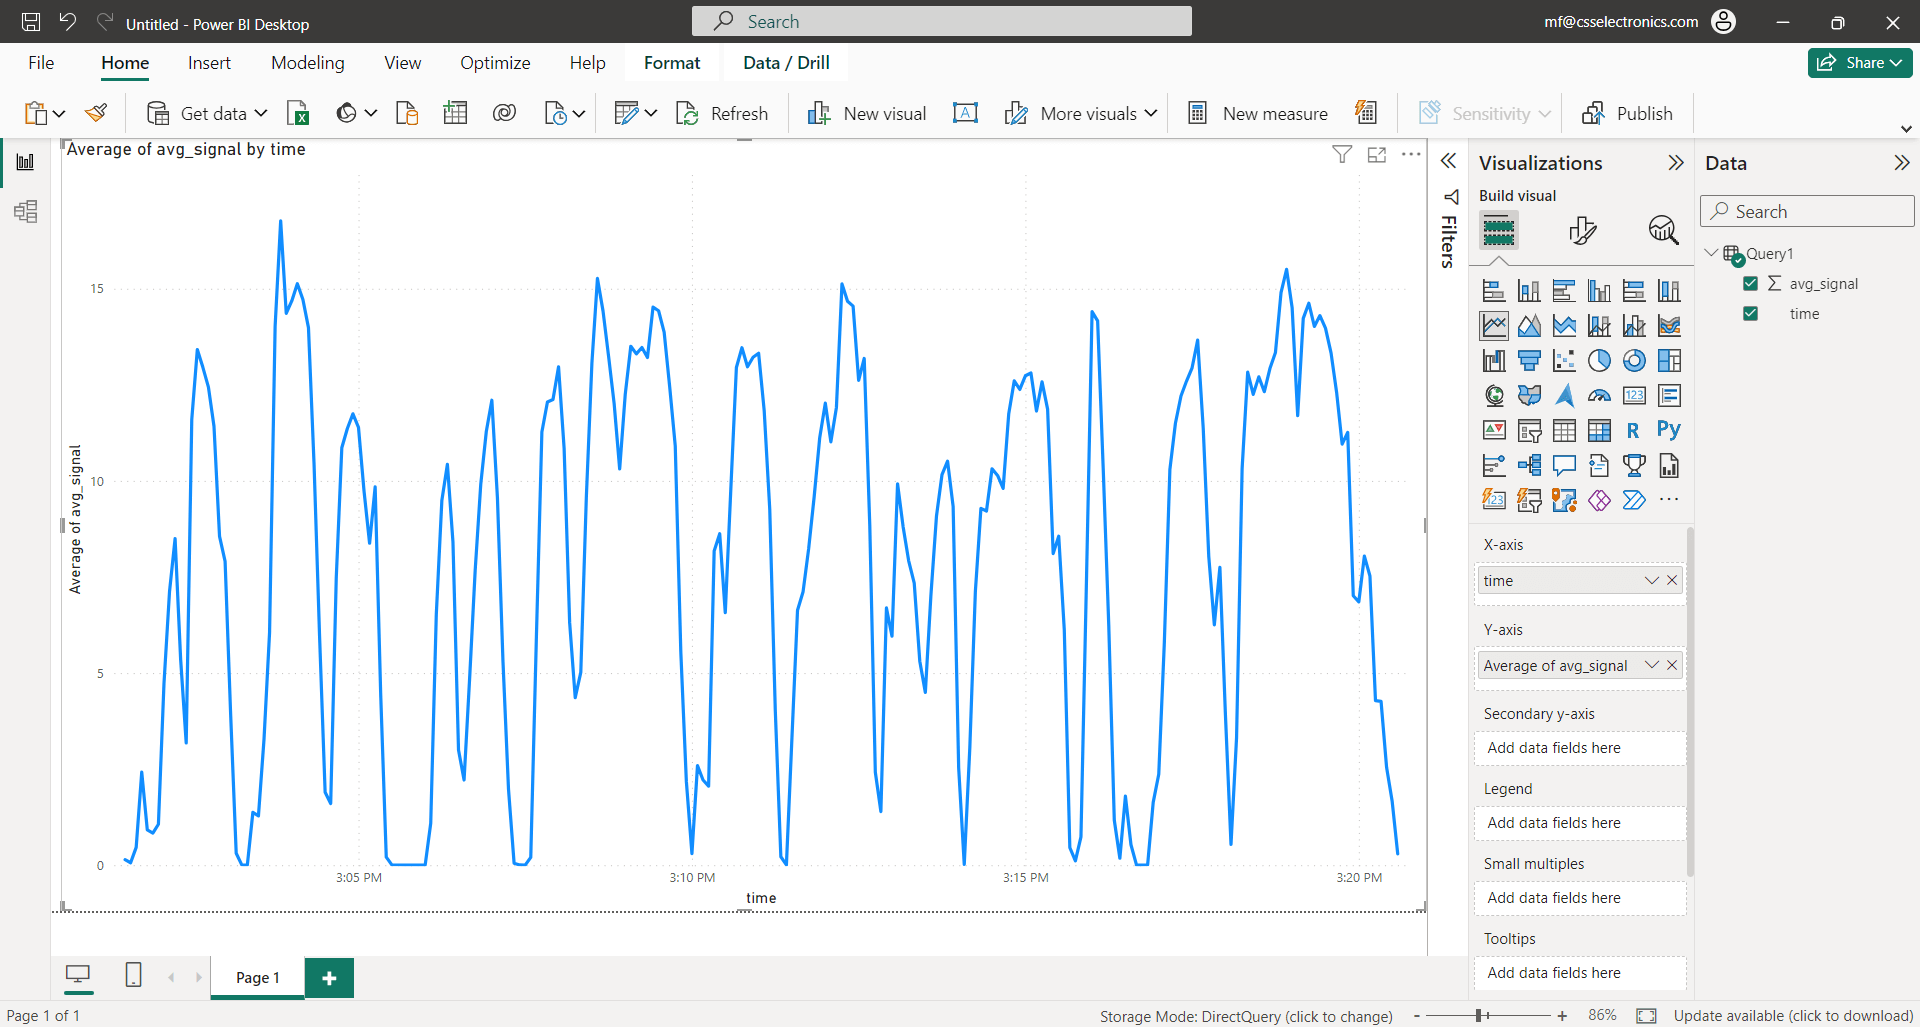
1. Make sure you have completed the prerequisites above
2. Open Power BI Desktop and create a new report
3. Go to ‘Get data/More/Azure Synapse Analytics SQL’
4. In ‘Server’, enter your ‘Serverless SQL endpoint’ from the Synapse overview
5. As ‘Database’ use your Synapse database name (e.g. `database1`)[1](#fn-synapse-database) and select ‘DirectQuery’
6. In ‘Advanced’ insert below query (after editing the bracketed fields)
7. To login, use the ‘Database’ option with `sqladminuser` and your SQL admin password[2](#fn-synapse-sql-admin-password)
```text
SELECT
DATEADD(SECOND, DATEDIFF(SECOND, '2000', t) / 5 * 5, '2000') AS time,
AVG() AS avg_signal
FROM
OPENROWSET(
BULK '///*/*/*/*',
DATA_SOURCE = 'ParquetDataLake',
FORMAT = 'PARQUET'
) AS r
WHERE
CONCAT(r.filepath(1), '-', r.filepath(2), '-', r.filepath(3)) BETWEEN '' AND ''
AND
t BETWEEN '' AND ''
GROUP BY
DATEDIFF(SECOND, '2000', t) / 5
ORDER BY
time
OFFSET 0 ROWS
```
The above query achieves a number of things:
- It extracts a single signal and time axis
- It groups the data into 5-second resampled interval averages
- It fetches data directly from the Parquet data lake via `OPENROWSET`
- It leverages date partitioning to only touch relevant files via the 1st filter
- It then filters the resulting data by time via the 2nd filter
---
## Example 2: Create a dynamic Power BI dashboard
For practical use we recommend to leverage Parameters and Slicers in Power BI. As inspiration, you can download the below `pbix` file to see how this can be set up. The Power BI file is intended as inspiration, not a plug & play template.
[`powerbi-synapse-dynamic-example`](/_static/files/log-file-tools/powerbi-synapse/powerbi-synapse-dynamic-example-v1.5.0.pbix)
---
* **[1]** This was shown as part of the Synapse Terraform deployment output. If you do not have it, open your `synapse-map-tables-` Container App Job via the [console](https://portal.azure.com/#browse/Microsoft.App%2Fjobs) and go to Settings/Containers and click ‘synapse-map-tables’. Under ‘Environment variables/SYNAPSE_DATABASE’ you can find the database name
* **[2]** This was shown as part of the Synapse Terraform deployment output. If you do not have it, open your `synapse-map-tables-` Container App Job via the [console](https://portal.azure.com/#browse/Microsoft.App%2Fjobs) and go to Settings/Secrets/synapse-password to find it