Customize your dashboard
With your first Grafana-Synapse dashboard in place, you can now start customizing.
Grafana has a tutorial on panels, so we mainly focus on some of the basics. You can also find inspiration via our dashboard playgrounds.
Templates - getting started
We recommend that you load one of the below templates to get started:
Simple dynamic dashboard
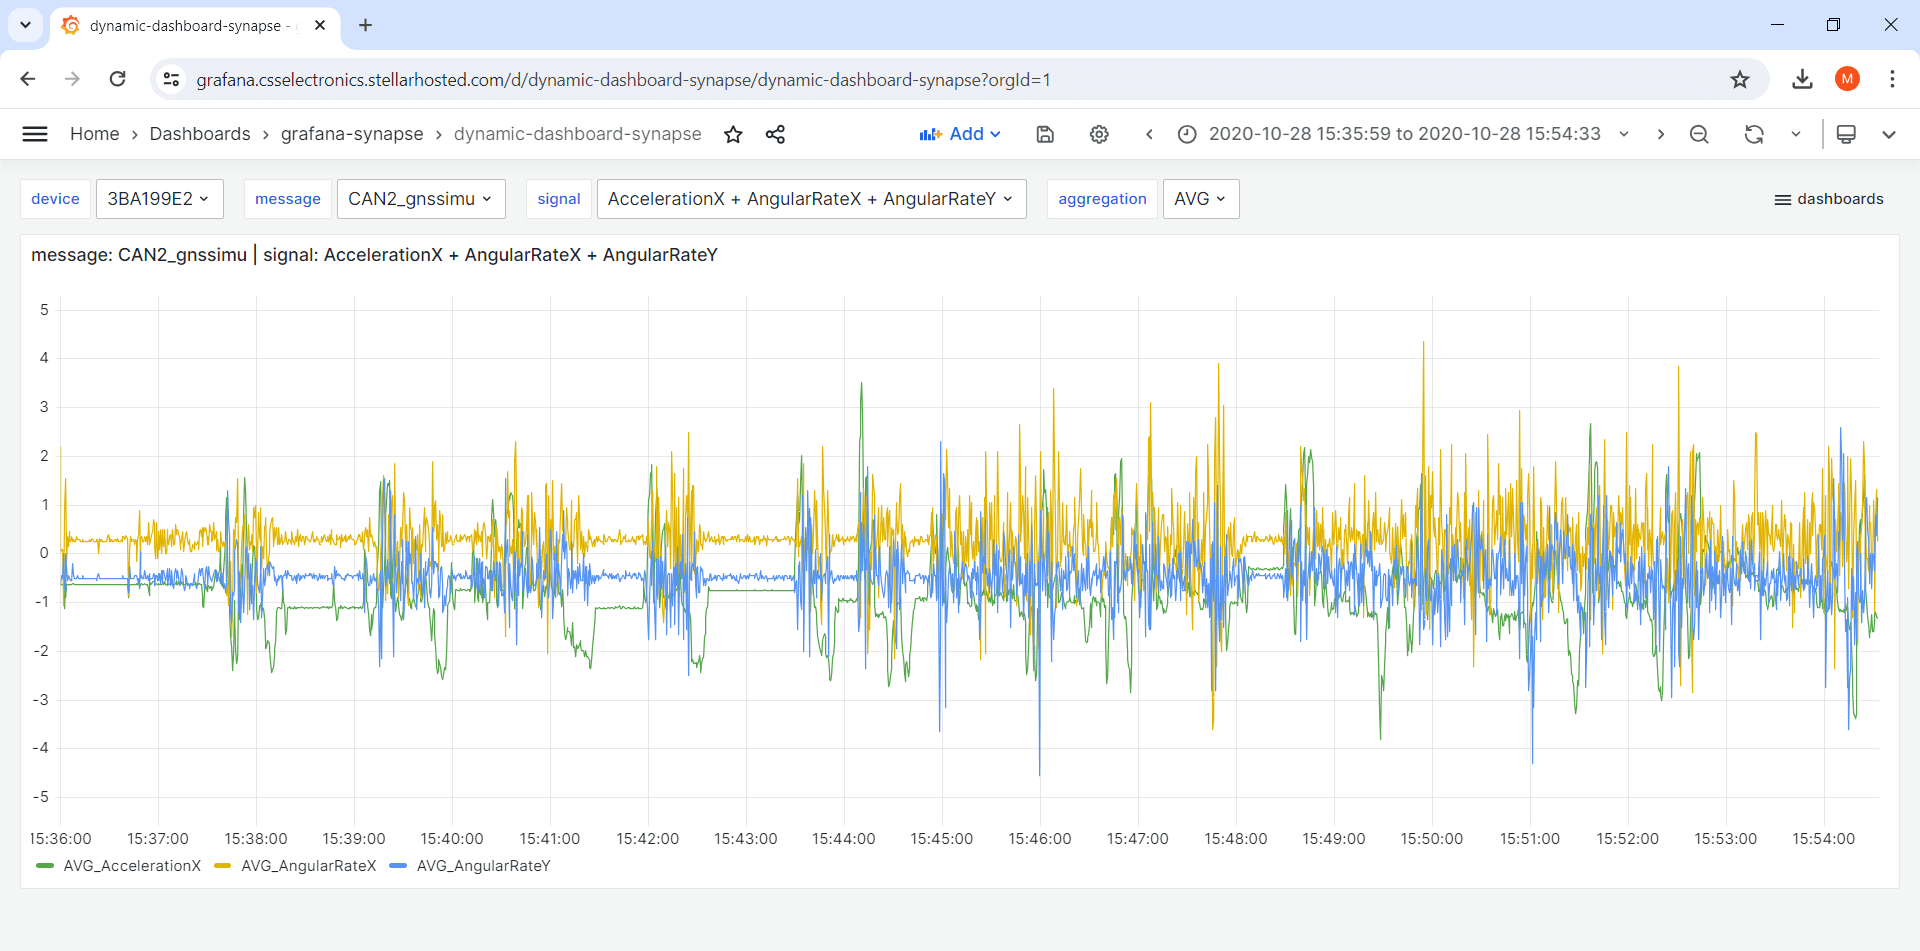
This template works for any CAN/LIN dataset and serves as a good starting point.

Templates - advanced
Trip summary dashboard
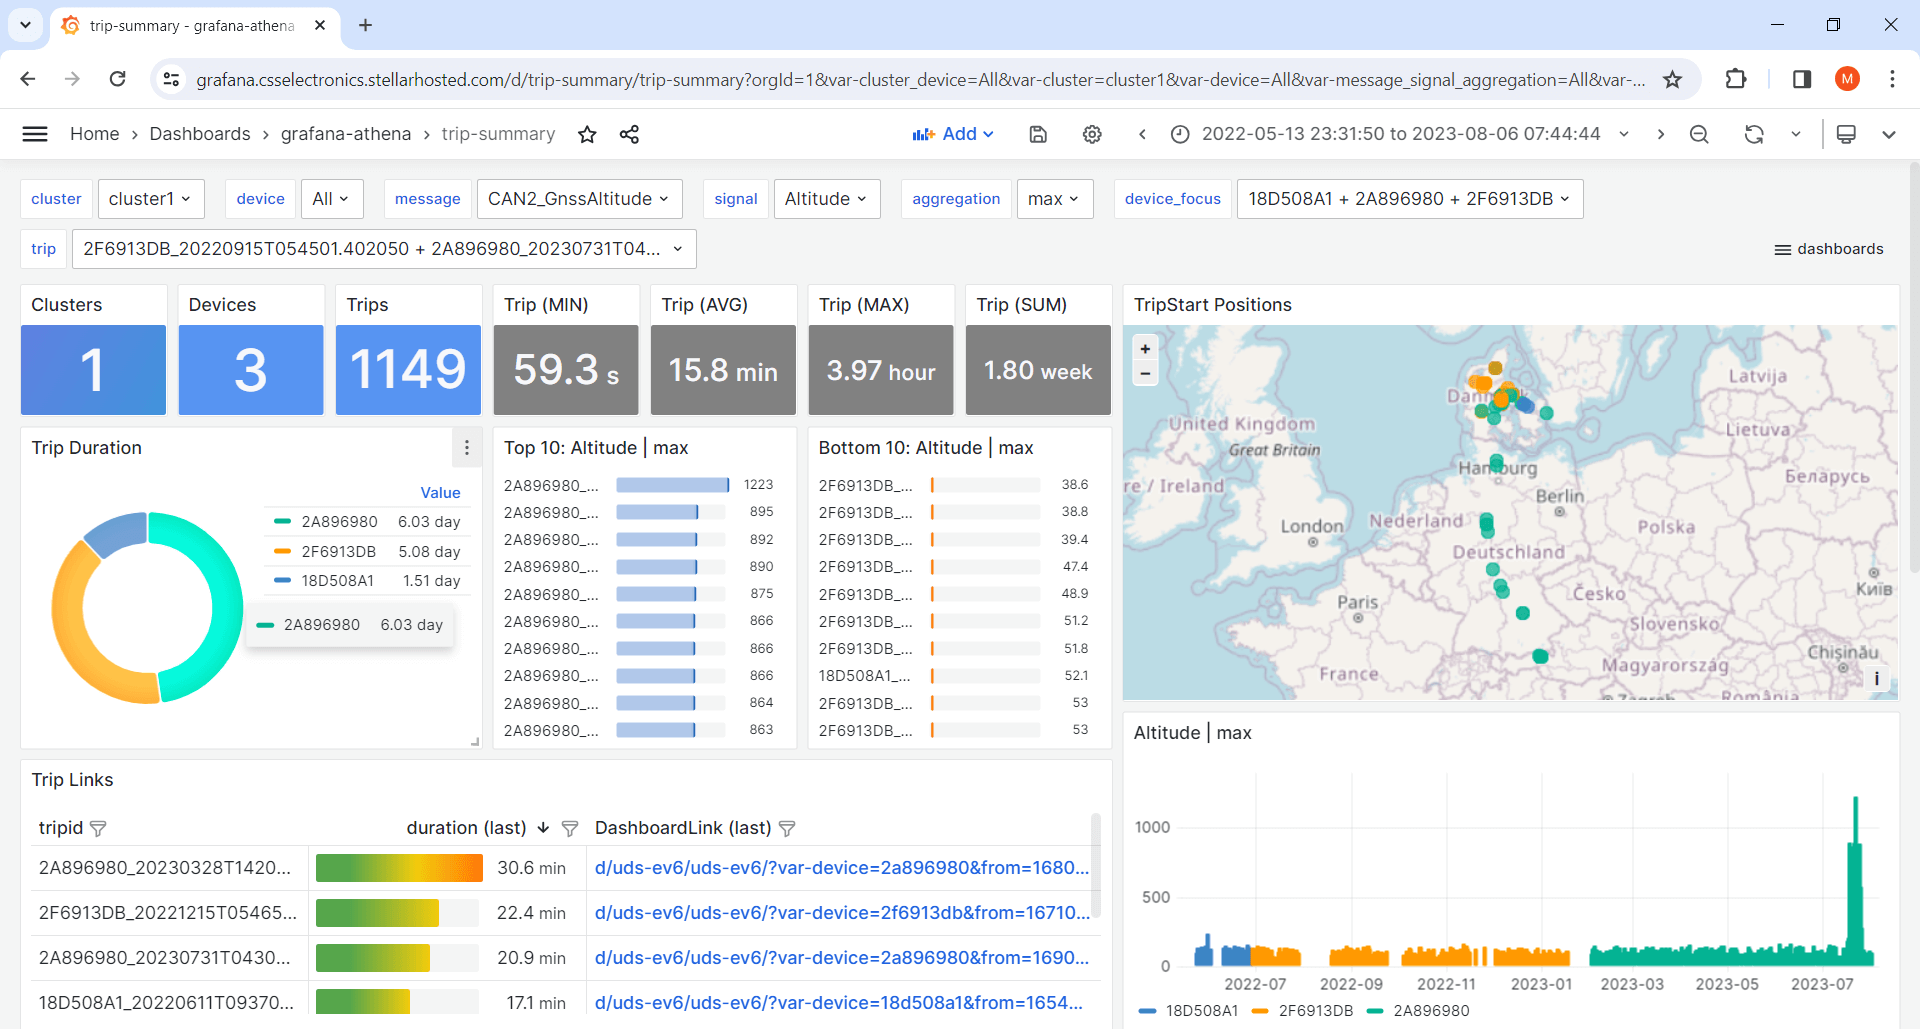
This template lets you visualize aggregated trip summary tables[5] - ideal for fleets.
Event summary dashboard
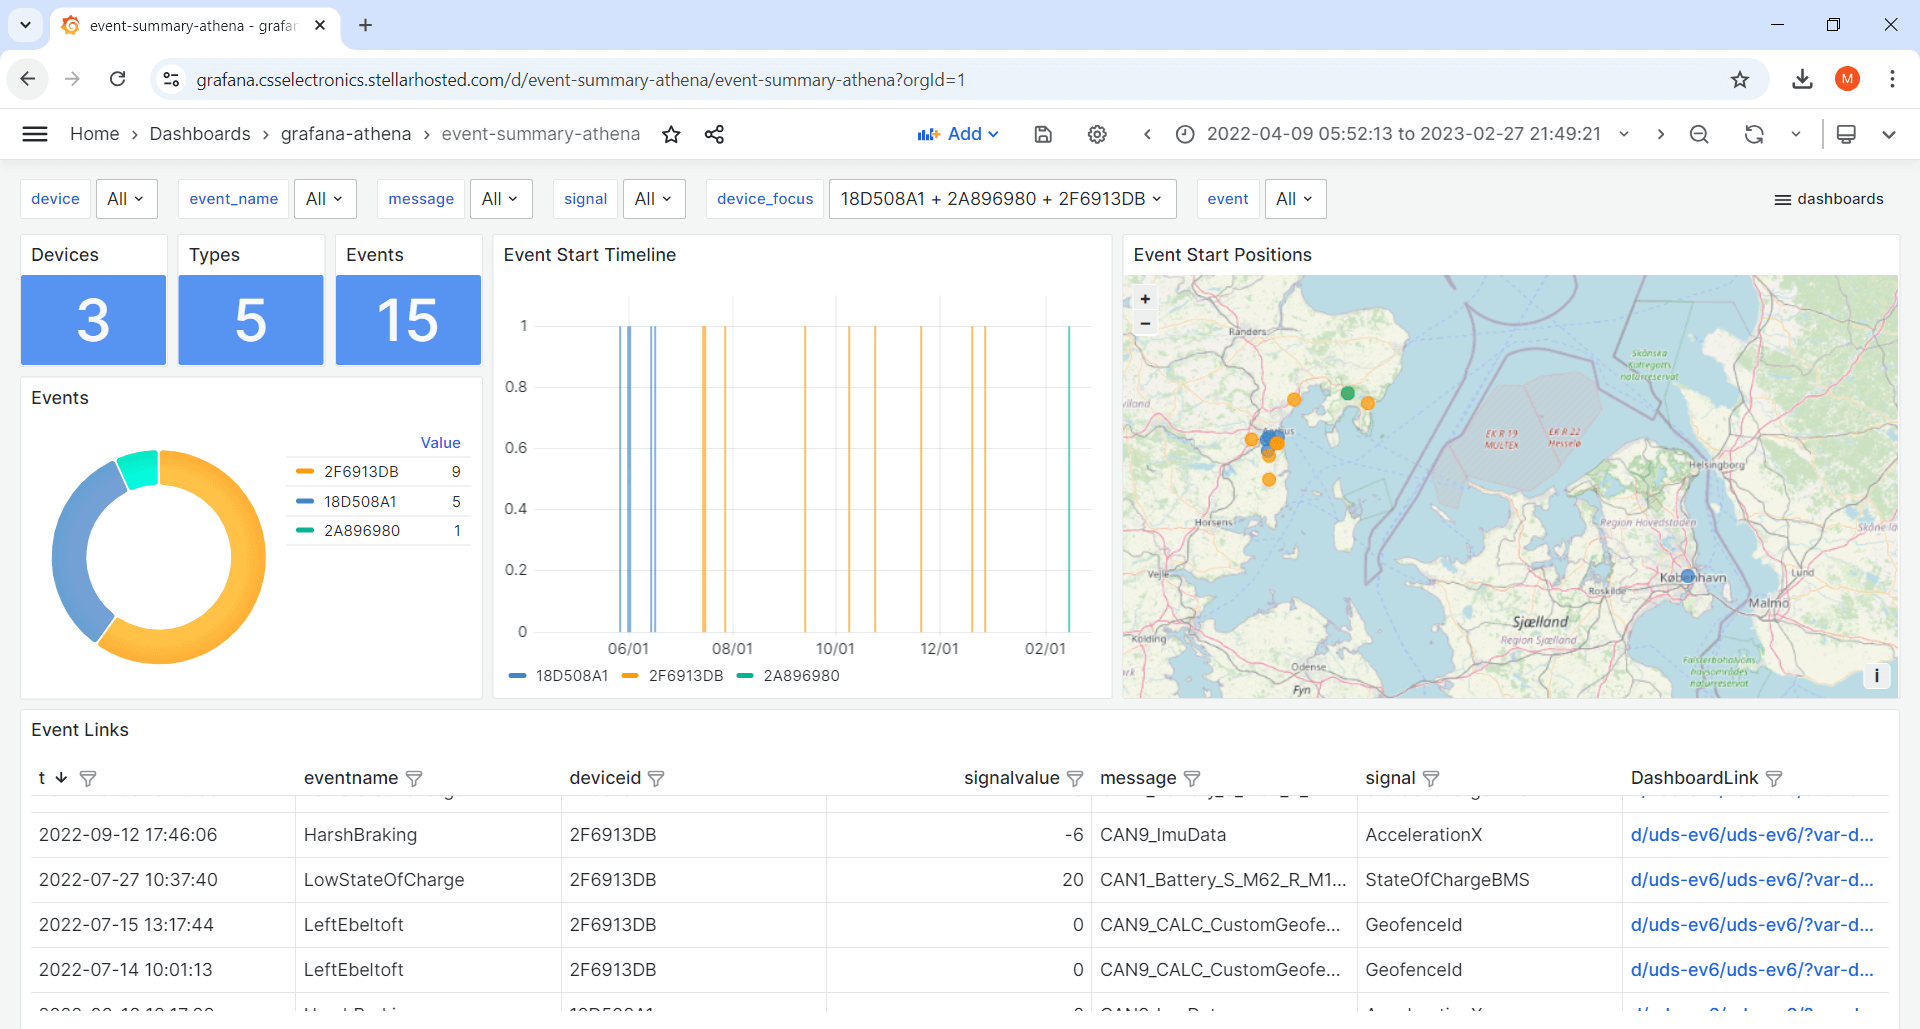
This template lets you visualize event summary tables[5] - ideal for fleets.
Variables
The dashboard template uses variables. These allow end users of the dashboard to dynamically control certain values, e.g. the device, message and signal.
Note
By default, the device dropdown lists all your output bucket device IDs with a meta prefix (extracted from the device.json files in the input bucket)[2]
Create a new panel
The Synapse data source uses standard SQL (T-SQL) to query data[3].
To create a new panel, click ‘Add/Visualization’ (top middle) and paste a query as below:
SELECT
    DATEADD(MILLISECOND, (DATEPART(MILLISECOND, t) / $__interval_ms) * $__interval_ms, DATEADD(SECOND, DATEDIFF(SECOND, '2020', t), '2020')) AS time,
    AVG(mysignal) as AVG_mysignal
FROM
    OPENROWSET(
        BULK '${device:csv}/MyMessage/*/*/*/*',
        DATA_SOURCE = 'ParquetDataLake',
        FORMAT = 'PARQUET'
    ) AS r
WHERE
    CONCAT(r.filepath(1), '-', r.filepath(2), '-', r.filepath(3)) BETWEEN CONVERT(date, $__timeFrom()) AND CONVERT(date, $__timeTo())
    AND $__timeFilter(t)
GROUP BY
    DATEDIFF(SECOND, '2020', t), DATEPART(MILLISECOND, t) / $__interval_ms
ORDER BY
    time
OFFSET 0 ROWS;
Simply replace MyMessage with your message name (e.g. CAN2_gnssspeed) and mysignal with a signal (e.g. Speed) from that message[4]. You can also query multiple signals/aggregations:
AVG(MySignal1) as AVG_mysignal1, MAX(MySignal2) as MAX_mysignal2
Transformations
Grafana transformations allow you to create e.g. calculated signals, filters and more. In the dashboard templates, transformations are e.g. used to filter which signals are shown in certain panels - as well as scale speed (m/s) to speed (km/h).
Note
We recommend to review Grafana’s excellent transformations docs for details
Transformations are done on the results of your SQL queries - not on the backend data. To create backend calculations, you should instead modify the SQL query (more below).
Importantly, transformations can be chained - leading to an almost limitless number of possibilities.
Below we list examples of useful Grafana transformations:
Merge
A challenge when working with CAN data is the use of different time rasters per CAN message in the backend, which normally makes it hard to operate on signals across messages. However, the aforementioned queries resample your backend data to a common time raster on-the-fly. As a consequence, you can add multiple SQL queries in the same panel and apply a ‘merge’ operation to operate on cross-message signals in a single table with a shared time raster.
Add field from calculation
This allows you to create calculated signals via various math operations, across one or multiple signals (incl. across messages via merging).
Filter data by values
This is great for excluding certain values from your panels (incl. e.g. null values or outliers).
Transpose
This pivots your data frame, which is often useful in restructuring your data in a specific way.
Advanced SQL queries
For many use cases, the default SQL queries in our dashboard templates will suffice for visualizing your data - in particular when combined with the powerful Grafana transformations.
However, some calculations need to be done on the ‘original’ data in the Parquet data lake at the backend. Luckily, this can often be done via a custom SQL query.
Below we list some tips on creating custom SQL queries:
Use our default queries as inspiration
The default queries do a lot of heavy-lifting that you should re-use in custom queries, in particular in regards to the dynamic behavior (Variables, timestamp functions) and filtering (as per the WHERE section). In addition, make sure to always return a result that is ‘aggregated’ (e.g. through AVG, MAX, SUM, …) to avoid returning e.g. millions of observations to Grafana.
Leverage ChatGPT and similar tools
In our experience, tools like ChatGPT can help construct complex queries with great results. If you are not an SQL expert, this is a practical method to generate queries that you can immediately test out. Make sure to provide our default queries as a starting point for the development.
Use sub queries for delta time operations
In CAN/LIN analysis you often need to analyse data with respect to time durations i.e. delta time. This is e.g. useful to understand how much time a vehicle spends charging, with active DTCs or at different RPM levels. To do this, you can use WITH sub queries and date diff operations. For inspiration, see the ‘duty cycle’ panel in our j1939-truck-athena dashboard playground.
Perform cross-table joins
In SQL, you can query data across multiple tables (i.e. different CAN messages in our context) by using JOIN statements, allowing you to perfrom backend calculations of signals across messages. While powerful, such operations are drastically slower vs. returning resampled data from the two tables in parallel. We therefore recommend to always consider if your cross-table signal calculations could be done by using Grafana transformations on the resampled responses of multiple queries.